C On Verification
The proofs in this book compile with zero sorrys. Every VJP correctness theorem is machine-checked by Lean’s type system, and that covers dense layers, convolution, batch normalization, residual connections, depthwise convolution, squeeze-and-excitation, layer normalization, and self-attention. If it builds, the gradients are right. What the proofs do not say is that training converges, or how well: an optimizer handed the exact gradient can still diverge, plateau or overfit, and that is a theorem in no framework. Every accuracy in this book is a measurement, and the measurement is sharper for the proof: when a verified run matches its JAX reference, or misses it, a wrong gradient is not among the explanations.
But “it builds” is only the first of three kinds of certainty, and they are not the same kind. Proven (deductive): in Lean, against three core axioms, each operator’s gradient is its exact reverse-mode derivative. By construction (structural): the StableHLO the GPU runs is not written but printed from the same datatype the proofs reason about, with a bridge theorem pinning it to the proven formula, so the code cannot drift from the math. Cross-checked (empirical): what cannot be proven is watched by independent oracles that must agree before the hardware is believed, and that means the lowerer’s translation of the proven text into machine code, the GPU transcendentals, and finite-precision rounding beyond its theorem layer (§ C.4). Each kind catches what the others structurally cannot. This appendix walks the mechanisms, grouped by kind.
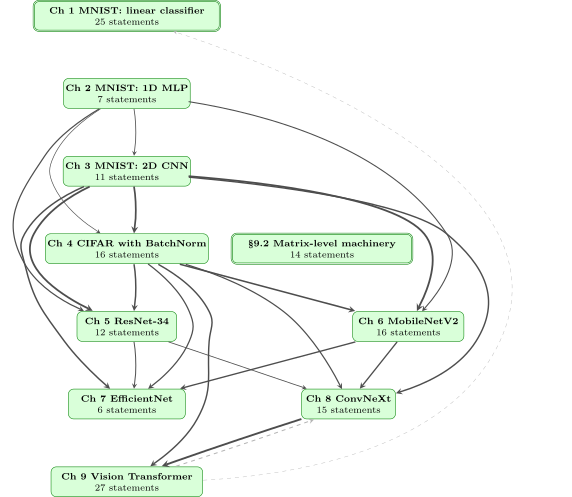
One property makes the whole edifice auditable: every chapter is pure composition. Every primitive either inherits from Mathlib’s \(\operatorname {fderiv}\) or composes previously-proved theorems, so each architecture’s whole-network VJP traces back to the Chapter 1 calculus. Figure 1.1 follows each chapter network’s whole-network certificate back through everything it cites, chapter by chapter; Figure C.1 is the citation graph between the chapters themselves.
C.1 Proven: the math is right
Two mechanisms make the deductive layer trustworthy: the proofs themselves, and an independent re-check that the kernel, not just the elaborator, accepts them with no project axioms.
C.1.1 Trust kernel
The Verified VJP Proofs suite proves the 44 VJP contracts and 9 witnesses of the table in How this book is organized, their restatements at fixed dimensions and over the committed specs, and the two smooth-point forms that global theorems superseded, each asserting backward \(= \sum _j \operatorname {pdiv}f\, x\, i\, j \cdot dy_j\); the 37 step certificates that tie the emitted programs to them; on top of the foundation \(\operatorname {pdiv}\) calculus and the differentiability/forward/witness machinery they rest on, plus the bestiary’s 45 architecture families — and zero project axioms anywhere in it. That last figure is the one that matters, because it is the only one that cannot quietly grow. The axiom audit (tests/AuditAxioms.lean) re-checks every theorem in the suite (the VJP contracts plus the forward-graph faithfulness, render, cotangent-chain, backward-tie, and finite-precision results, § C.4) — that file is the live count, quoted here deliberately as a property rather than a number — and every one closes under the same three core axioms: \(\texttt{\# print axioms vitFullHasVJP}\) shows only Lean core (propext, Classical.choice, Quot.sound), nothing project-level beneath those. (Earlier drafts axiomatized shortcuts for the kinked operators, and every one has since been proved or become a noncomputable def over the canonical \(\operatorname {fderiv}\)-derived witness. The smooth-point caveats in the chapters are all that remains of them.)
What type-checking alone cannot catch: prose narrating a different formula than the theorem states (Lean only verifies its own statement), and anything past the elaborator, which is what the next mechanism and the empirical layer are for.
C.1.2 Independent kernel re-check (comparator)
tests/comparator/ wires the project up to leanprover/comparator (lake comparator, bundled with Lean since 4.35), the Lean community’s trustworthy-judge tool for projects that claim zero project axioms. It runs with –paranoid, so besides Lean’s own kernel five independent checkers must accept every proof: leanchecker-paranoid, lean4lean, nanoda, con-leche and con-ron. It runs 88 theorems (the foundation rules, every chapter’s headline Jacobian, the public *HasVJP_correct wrappers, three smooth-point pointwise variants (reluHasVJPAt_correct, mlpHasVJPAt_correct, maxPool2HasVJPAt3_correct) whose underlying .correct field is a real proof rather than rfl, and the 35-theorem tie / faithfulness / certificate tier) through Lean’s kernel typechecker independently of the elaborator, with an axiom-allowlist of exactly \(\{ \texttt{propext}, \texttt{Quot.sound}, \texttt{Classical.choice}\} \). Any project axiom in the transitive closure of any verified theorem would fail the run.
This is what closes the gap between “the elaborator accepted my proofs” (which lake build confirms) and “the kernel agrees, audited from a separate process” (which comparator confirms). The 87 are not the whole proof suite — tests/AuditAxioms.lean prints the axiom closure of 1,751 declarations, and the same allowlist applies to all of them, because every theorem in the project closes the same way. What the 87 add is a second, non-elaborator opinion, and they include every declaration formalization.yaml puts forward as a result, together with the calculus floor those rest on.
C.2 By construction: the code is the math
C.2.1 Verified code generation
The proofs above answer whether the mathematics is right, meaning the hand-derived VJPs, their proofs, and the elaborator that accepted them. They say nothing about a different gap. The GPU never runs the Lean functions. It runs a block of emitted stablehlo that the lowerer compiles once per training program. A code generator can be handed a correct proof and still emit an operation that contracts the wrong axis, transposes backwards, or silently drops a term, and the only thing traditionally linking the proof to the emitted string is a code comment. The “MLIR: operator” section in each chapter closes that gap for one operator, and this section describes the machinery they share.
Three pieces. The link from a proof to the GPU is built from three components:
Denoted IR and a bridge theorem. The emitted backward (and forward) is not a string but a Lean datatype, a small abstract syntax tree (Back, Fwd, Back3), carrying a denotation \([\! [\cdot ]\! ]\) valued in the proofs’ own Vec and Tensor3 types. A bridge theorem then proves that this denotation equals the proven derivative: \([\! [\, \text{emitted graph}\, ]\! ] = (\text{proven VJP}).\mathrm{backward}\). Examples are conv_back_bridge_1to2, bn_back_bridge, and relu_back_bridge, and each closes under the same three axioms as the rest of the project.
A computable printer. Back carries real-valued operands and cannot be printed as it is, so IRPrint.lean defines a mirror of it, Hlo: the same node structure, with SSA names and shapes in place of values, printed one stablehlo operation per node: dotGeneral \(W\) becomes stablehlo.dot_general, a selectPos node becomes compare GT 0 plus select, and so on. That the mirror is built node for node from the bridged graph is a reading of two definitions, not a theorem. The tier where the printed text is the denoted graph’s own printout is the verified trainers’ StableHLO tier, below.
An execution oracle. A Python harness (LeanMlir/Proofs/check_ir_codegen.py) regenerates the .mlir from the printer, compiles it with IREE, runs it, and diffs the result against an independent NumPy reference. The CPU run (llvm-cpu) is the correctness gate; the GPU leg is ROCm-only and best-effort, and where it has run (a Radeon RX 7900 XTX, gfx1100) the proof-backed graph matched the reference to roughly \(10^{-6}\).
Proven versus trusted. The resulting claim is exact and bounded:
Proven (Lean, three axioms): the IR’s denotation equals the proven derivative.
Read, not proved: that the printed mirror is, node for node, the bridged IR.
Trusted (validated numerically, not proven): that the StableHLO text faithfully denotes \([\! [\cdot ]\! ]\). One piece of its syntactic half is proved: the postorder token encoding the printer works from is invertible (StableHLO.roundtrip). That is a statement about tokens, not text; how each token becomes a line of text (emitTok) is trusted, and checked by parsing and running the committed artifacts. Beyond it, three things are trusted: a formal StableHLO semantics, which does not yet exist, that the lowerer compiles the text correctly, and that the hardware’s rounding approximates \(\mathbb {R}\) within the modelled unit roundoff. The last of those is now a conditional theorem validated on real silicon (§ C.4) rather than a bare assumption.
So the gradient the GPU computes is, by a machine-checked theorem, the network’s exact reverse-mode derivative over \(\mathbb {R}\) — at a smooth point, at one replica, in f32 or bf16 — up to one printer, one lowerer, the StableHLO semantics the denotation assumes, and floating point. Where a conventional generator leaves thousands of lines of string-building linked to the proof by nothing at all, the unproven surface here is a single printer, tested end to end, plus the hand-written lines each render declares in its own comments (the report-only %loss, for one, and ConvNeXt’s GAP-backward block).
Why it is tractable. The reason a deep ResNet or a transformer block comes under this scheme as a focused engineering build, rather than a research project, is the order things were proved in. The VJP library is per-operator and generic, proved once over abstract dimensions and before any code generation existed, and the whole-network VJPs compose those per-operator lemmas through the chain rule. Code generation therefore carries no new proof obligation: every architecture’s operators were proven once, and the emitter reuses them, adding only the printer and the numerical check. Build the mathematical foundation per-operator and generic, and the code generation becomes mechanical.
From operators to whole training steps. The per-operator bridge is the demonstration, and the verified trainers run the full construction. Each reads a single committed .mlir holding its entire training step, forward through backward through the parameter update, and that file is the printout of one graph whose denotation a faithfulness theorem proves, output by output, equal to the certified per-layer step: each parameter update is \(\theta - \mathrm{lr} \cdot (\text{that layer's certified Jacobian} \cdot \text{the chain cotangent})\). A companion tie theorem per network (mlp_train_step_tied_certified, r34_net_tiedB, vit_net_tied_certified and their peers) then closes the gap a per-output bridge leaves open: the cotangent each parameter update consumes is the one the network’s own backward pass delivers at that site, threaded through the real forward activations, so each update is one composed equation rooted at the proven forward rather than a quantifier over a free cotangent. All thirteen chapter networks are tied this way, from the MNIST linear classifier to depth-12 ViT-Tiny, and each deep net’s chain cotangent is pinned to its block’s certified VJP (r34IdCotIn_eq_vjp, vitBlockCotInB_eq_vjp and their peers). For the seven ImageNet networks one more theorem composes the two halves: at the tie’s own cotangent, every parameter gradient node is \(\partial L/\partial \theta \) of the whole network, for any loss \(L\) with a gradient at the logits and in particular for the label-smoothed cross-entropy the artifacts emit (r34_net_lossGrad and its peers; one replica, either precision). The axiom audit re-derives every tie under the same three axioms, and CI prints a green cell for a network only when its tie capstone is in that closure, so the scorecard cannot claim more than the kernel checked. What stays trusted is exactly what the per-operator story already trusted, now carried across the whole step: the one printer, and that each emitted operation’s text denotes what \([\! [\cdot ]\! ]\) says it does.
The one conditional. For the smooth operators the bridge is unconditional, holding at every input, and those are BatchNorm and LayerNorm (given \(\varepsilon {\gt} 0\)), GELU, swish, sigmoid, softmax, and attention. For the kinked operators, which are ReLU, ReLU6 and max-pool, it holds only at a smooth point: no pre-activation exactly on the kink (zero for ReLU, \(0\) or \(6\) for ReLU6), and every \(2 \times 2\) pooling window’s maximum attained at one cell (MaxPool2Smooth). The equality is permitted to fail precisely on that set, and nowhere else. For ReLU the set has measure zero; for a pool on its own it does not, because an all-zero post-ReLU window attains its maximum at every cell, and the whole-net theorems carry the pooling clause as a hypothesis at the activations. The ResNets’ \(3 \times 3\)/s2 stem pool is certified together with the ReLU before it (stemReluPoolLayer), which admits the all-zero windows too: there every pre-activation is negative, so the pair is locally constant. What the stem still excludes is a window whose positive maximum sits at two positions (StemPoolSmoothAt). Real batches have such windows, from two cells reading identical input patches in a flat image region; there the network has no derivative in the image, so an input-gradient statement cannot hold, but the tied cells are the same function of the stem’s weights and the loss gradients in the parameters allow them (StemPoolTwinAt); routing a tied window’s cotangent to either twin gives the same parameter gradient (r34Stem_select_grads_eq). That set is the boundary the smooth-point caveats in the chapter sections refer to.
C.2.2 Inside a bridge theorem
The “denoted IR and a bridge theorem” above is worth seeing concretely, because it is the step that does the real work, the place where a string of emitted code becomes a proposition Lean can check. Take the backward pass. It is represented not as text but as a value of an inductive type, a small abstract syntax tree whose constructors are exactly the StableHLO operations a backward uses:
inductive Back (inp : Nat) : Nat -> Type where
  | cotangent  : Back inp inp            -- the input dy
  | dotGeneral {m n : Nat} (A : Mat m n) : Back inp n -> Back inp m   -- matmul
  | selectPos {n : Nat} (x : Vec n) : Back inp n -> Back inp n   -- ReLU mask
  -- plus scale, sub, add, sumBroadcast, scaleConst (BN, residuals)
A Back value is a closed description of one backward graph. The dense backward, for instance, is just dotGeneral W cotangent, which feeds the incoming cotangent into a single matrix multiply. Two functions are defined on this type, and everything rests on the gap between them being closed by a theorem.
The denotation. The first function, Back.denote, interprets a graph into the proofs’ own Vec type, saying what the graph means mathematically:
and likewise for the remaining constructors (scale, sub, sumBroadcast, scaleConst and add), which are the pieces that assemble BatchNorm’s three-term backward and the residual fan-in. So a Back value denotes a concrete \(\texttt{Vec} \to \texttt{Vec}\) function, living in the same world as the VJP theorems.
The bridge, as an equation. A bridge theorem states that this denotation equals the proven derivative. For the dense layer:
Its proof is one word, rfl: both sides reduce to the same term, Mat.mulVec \(W\, dy\), so the denotation of the emitted graph and the proven backward are definitionally identical. That base case pins the plumbing. The ReLU bridge is the first with real content:
The proof unfolds the denotation to \(\text{if } x_i {\gt} 0 \text{ then } dy_i \text{ else } 0\) and shows it equals the canonical ReLU subgradient, but only under the hypothesis \(h_{\text{smooth}}\) that no coordinate sits on the kink. That hypothesis is not a technicality. It names exactly the measure-zero set where the emitted compare GT 0 disagrees with the true derivative, and the theorem is written to permit failure precisely there and nowhere else. The convolution bridge of Chapter 3 is the same shape with a harder proof: convBackDenote unfolds to a forward conv2d of the reversed-and-transposed kernel, discharged by expansion at the concrete tensor shape.
Composing the per-operator bridges. Whole-network backwards are assembled by substitution. The function Back.subst plugs one graph into another’s cotangent leaf, and a chain-rule lemma proves the denotation composes:
proved by induction over the graph, the IR-level analogue of the vjpComp that builds whole-network VJPs from per-layer ones. So the per-operator bridges compose into a whole-network bridge the same way the VJP theorems compose into a whole-network VJP: the MLP’s mlp_whole_bridge is this one substitution, chaining its five per-operator bridges.
Why the datatype is the point. The Back value is the pivot between two arrows. The printer walks it and emits one stablehlo operation per constructor (dotGeneral \(\mapsto \) stablehlo.dot_general, and selectPos \(\mapsto \) compare GT 0 plus select), and that arrow is the trusted one, producing the text in each chapter’s listing. The denotation interprets the same value into the proofs’ Vec type, and the bridge proves the result equals the derivative, so that arrow is machine-checked. Because both arrows start from one concrete datatype rather than from a string, “the emitted code computes the proven gradient” is a theorem about a value, not a hope about a comment.
C.3 Cross-checked
Neither lowerer can itself be proven, and GPU transcendentals have no IEEE specification, so the last stretch from proven math to executed kernel is covered by independent oracles that must agree before the hardware is believed. Each watches a different failure mode.
The property that makes this work is that the two sides do not share a compiler. The Lean-side pipeline of the oracles below lowers through IREE, and the reference pipeline is JAX, which lowers through XLA. Different code generation, different runtime, different kernels, and different authors. Agreement between them is evidence precisely because a bug would have to occur twice, in the same direction, in two unrelated compilers. This is IREE’s real job in the project, and it is not the one the runtime-size comparison in Appendix B might suggest. IREE is not kept because it is small. It is kept because it is not XLA.
C.3.1 Finite-difference gradient checks
The script LeanMlir/Proofs/check_jacobians.py runs 30 finite-difference gradient checks. For each, it perturbs the input by \(\varepsilon \), compares the claimed VJP against the centered difference \((f(x + \varepsilon ) - f(x - \varepsilon )) / 2\varepsilon \), and asserts agreement within tolerance (typical max-error \(\sim 10^{-11}\) at \(\varepsilon = 10^{-5}\) in float64).
Every FD check is a belt-and-suspenders pass over a proved Jacobian theorem. The proofs already establish that each formula equals \(\operatorname {fderiv}\) at the relevant points, and the FD checks confirm the formulas-as-written agree numerically with what the function actually does. Coverage spans every closed-form Jacobian we use downstream: \(\operatorname {pdiv}\_ \texttt{dense}\) and its weight/bias companions, \(\operatorname {pdiv}\_ \texttt{relu}\) (at smooth points), softmax cross-entropy, all four BN pieces (bnNormalize, bnCentered, bnIstdBroadcast, bnAffine), the conv2d and depthwise input/weight/bias VJPs, the maxPool2 input VJP, and the softmax Jacobian. It also covers the three single-head SDPA Q/K/V backwards, GELU, the bundled multi-head SDPA reduction (per-head sdpa_back stacked over the head axis), the patch-embed input VJP, the full-network MLP composition, and bestiary spot-checks (bilinear upsample, channel concat, per-pixel softmax cross-entropy, U-Net skip plumbing).
What the FD pass catches that the symbolic proof can’t: typos between the proof and the prose that uses the same Jacobian. If a chapter narrates one formula but the Lean theorem states another, the proof still type-checks (Lean only verifies its own statement), but the FD test runs against the formula the prose published and would diverge.
FD is cheap, easy to reason about, and tight enough for spot-checking formulas, but it can’t probe what the compiled code actually computes on the GPU, only what the formula says in Python, and it struggles at non-smooth points where the limit definition breaks down. For those gaps and for end-to-end pipeline verification, the next oracle takes over.
C.3.2 The JAX parallel pipeline
A separate Lean \(\to \) JAX \(\to \) XLA pipeline (jax/Jax/Codegen.lean, \(\sim 3700\) lines) produces an idiomatic JAX training script from the same NetSpec the Lean \(\to \) StableHLO MLIR pipeline consumes. XLA is the compiler JAX uses to produce GPU code, the same backend that powers TensorFlow and other frameworks. For this comparison the Lean side is lowered by IREE, so the two stacks are independent end to end, with different code generation, different runtime and different kernels, and that is why agreement between them is a meaningful cross-check. Running both from identical initial parameters on identical batches gives us a pair of trace files, one per stack, that should agree modulo float32 rounding if both pipelines compute the same math.
The agreement is very tight. For the MNIST MLP, step-1 losses agree to \(\sim 2 \times 10^{-7}\), which is float32 ULP, across the JAX-CPU-vs-IREE-ROCm comparison, and the IREE output is bit-identical across AMD and NVIDIA hardware at step 1. For the MNIST CNN with batch norm, step-1 agrees to \(\sim 10^{-4}\), looser because variance reductions over \(\sim 100\)k-element tensors amplify cross-compiler reduction-tree differences. Both pipelines do correct math, they just sum it in different orders. Full results are committed to the repo as reproducible JSON-Lines traces, in historical/traces/CROSS_BACKEND_RESULTS.md.
One asymmetry, stated plainly. The trainers in this book default to XLA, while the oracles above lower the Lean side through IREE. That is deliberate, because an oracle that shared a compiler with its own reference would not be checking the compiler at all. The consequence is worth being clear about: it is IREE’s translation of the proven text that these oracles exercise directly, so the default training path’s lowering carries less of this particular kind of evidence than the path the oracles run. Every other layer is unaffected, since the proofs, the bridge theorems and the rounding budgets are statements about the graph rather than about any compiler, and both lowerers consume the identical proven StableHLO.
Layered on top of the end-to-end trace diff is a per-axiom differential test in tests/vjp_oracle/, which compares each Lean-proved backward pass against JAX’s value_and_grad autodiff on a minimal one-step training run. Fourteen cases each agree with JAX autodiff on the step-2 loss, to between \(2 \times 10^{-7}\) and \(10^{-4}\), the wider ones where a max-pool or a depthwise reduction changes the summation order: dense, dense+ReLU, conv, conv+BN, conv+max-pool, residual, depthwise, global average pool, attention, and the SE-gated MBConv, bottleneck, MBConv-V3, fused-MBConv and UIB blocks. Any future hand-derived VJP added to the Lean proof base can be validated by a one-step comparison against JAX, catching algebraic errors that FD would miss (sign flips, wrong contraction axis, swapped indices).
C.3.3 The execution oracle and the margin probe
Two further watchers close the loop. The IREE-versus-NumPy oracle (§ C.2.1) regenerates the per-operator and small-network graphs (linear, MLP, CNN, convolution, max-pool, BatchNorm, the loss cotangent and a ConvNeXt block) from the printer, compiles them for CPU, and diffs the result against an independent NumPy reference, which is the one check that reaches past the proofs to IREE’s lowering itself. And the margin probe (scripts/certs/margin_probe.py) re-runs a real training trajectory in coupled f32/f64 and checks that the run stays inside the float theorems’ hypotheses, with no flipped ReLU mask and no logit drift past \(\delta \) (§ C.4). It is what keeps the conditional theorems honest about actual training rather than hypothetical nets.
Each kind fails differently, and overlaying them is the guarantee. A deductive proof is blind to a miscompile, an empirical diff is blind to a measure-zero kink, and a faithful bridge is blind to a wrong formula it renders perfectly. Verified code generation straddles two of the kinds: its bridge is structural, its oracle empirical. The finite-precision theorem layer, next, straddles the other pair: its budgets are deductive, its interface constants (\(u\), \(e_{\exp }\), \(\delta \)) empirical.
C.4 Finite precision
Every theorem in this book is over exact reals, and the GPU computes in finite precision. Until recently that gap lived entirely in the empirical layer, where the oracles agree to float32 precision. It is now a theorem layer, and it has two halves of different reach. Keeping them apart is the honest part — as is keeping the layer’s generality apart from its usefulness, which § ?? below returns to. The closeness half (\(|\, \text{float op} - \text{real op}\, | \le \) budget) is per-operator: FloatBridge.lean budgets every operator the networks are built from, and the certified backward ties say each net’s hand-written gradient chain is the certified one. The descent half (a rounded step provably decreases the loss) closes only for the shallow nets (SgdDescent{Linear,Mlp,Cnn,CnnFloat,Cifar}.lean). The way the chain avoids new axioms is the part worth explaining.
The model is a hypothesis.
A FloatModel is any rounding operator \(\mathrm{rnd}\) with relative error \(u\): \(|\mathrm{rnd}(x) - x| \le u\, |x|\). Binary32 round-to-nearest satisfies this with \(u = 2^{-24}\) on the normal range; in the subnormal range the rounding error is absolute, not relative, and the model does not cover it. The exact-arithmetic model (\(\mathrm{rnd} = \mathrm{id}\), \(u = 0\)) shows the interface is inhabited and collapses every budget to zero. Nothing about IEEE-754 is postulated, and the theorems are conditional on the standard model, the same way the ReLU theorems are conditional on being off the kink, and the axiom audit is untouched. Two further design choices are forced by the hardware: the dot-product budgets are stated in the classical compounded form valid for every summation association, because IREE tiles and reorders reductions freely (the price is a fan-in factor \(n\cdot u\), and the tree-reduction bound below recovers \(\log _2 n\cdot u\) under a named balance hypothesis). And \(\exp \) enters as a hypothesis (\(|\widehat{\exp }(t) - e^t| \le e_{\exp }\, e^t\)) because GPU transcendentals have no IEEE specification. \(e_{\exp }\) is precisely the constant the margin probe pins on the device at 1–2 ULP (Measured against proven, below), so the deductive and empirical layers meet at a named interface instead of a hand-wave.
How far the model reaches, and where it stops being useful.
Because \(u\) is a parameter, nothing in the chain is float32-specific. Binary32Instance.lean constructs the rounding operator as round-to-nearest on the \(p\)-bit-significand grid and instantiates it twice: binary32 at \(p = 23\), \(u_{32} = 2^{-24}\), and fp8E4M3 at \(p = 3\), \(u_{\mathrm{e4m3}} = 2^{-4}\). Every bridge quantifies over (M : FloatModel) — the per-operator lemmas, the residual-block chain, the MNIST descent chain — so none of them is a statement about binary32 that happens to be proved; each is a statement about any rounding model, of which binary32 is one instance.
That generality is free. Usefulness is not, and the two should not be confused. The dot-product budget carries the classical fan-in factor \((1+u)^{n+1} - 1\), which goes vacuous once \(n\, u\) approaches 1 — a wall at \(n \approx 1/u\). At \(u_{32}\) that wall sits near \(1.7 \times 10^{7}\) and no layer in this book comes close. At pure bf16 (\(u = 2^{-8}\)) it sits at \(n \approx 256\), and ResNet-34’s \(3\times 3\) convolution at 512 channels has fan-in 4608. The budget is still true there. It is also worthless there.
Which is why the low-precision result is stated mixed rather than pure. dotMixed rounds the operands through a leaf model \(L\) (bf16 \(2^{-8}\), or fp8-E4M3 \(2^{-4}\)) and accumulates through \(M\) at \(u_{\mathrm{acc}}\), which is the shape the hardware actually runs: low-precision inputs, fp32 accumulator. dot_close_mixed then splits the error in two, and the split is the whole point — the leaf precision contributes a flat \((2u_{\mathrm{leaf}} + u_{\mathrm{leaf}}^2)\sum |x_i y_i|\) term that is not fan-in amplified, while the amplification rides entirely on \(u_{\mathrm{acc}}\). The wall stays at \(1/u_{\mathrm{acc}}\) no matter how coarse the leaf is. That is exactly why bf16-mixed is non-vacuous where pure bf16 is not, and it is carried to convolution and depthwise convolution in ConvMixedFloatBridge.lean, DepthwiseMixedFloatBridge.lean and ConvMixedComposeBridge.lean. The emitted bf16 graphs are tied at their gradient nodes in Bf16GradNodes.lean, and at the identity rounding the renderers instantiate each bf16 kind denotes its f32 peer (Bf16Erasure.lean), which is how every whole-network step tie is stated at either precision; Bf16Fold.lean (bf16_render_faithful, its emittable form bf16_render_faithful_emit, and bf16_render_faithful_depth2 at two layers) and E4M3Fold.lean prove, for the linear net, that the mixed-precision graph denotes the intended algorithm. The fp8 one is proved for a graph no backend here lowers, and the one committed fp8 artifact, cifar8b_fp8_adam_train_step.mlir, is a lowering probe with no fold of its own.
So the honest summary is three sentences, not one. The theorems are over \(\mathbb {R}\). The budgets are over an arbitrary rounding model, so binary32, bf16-mixed and fp8-E4M3 are instances rather than separate theories. And the numbers those budgets produce are worth having at fp32 accumulate, worth having at a low-precision leaf over an fp32 accumulator, and not worth having at pure low precision — which is a fact about the arithmetic, not a gap in the proofs.
The chain.
Four links, each in the three-axiom audit. Forward: mlp_float_close_uniform budgets the rounded \(784{\to }512{\to }512{\to }10\) forward against the exact one, from coordinatewise magnitude bounds alone. Backward: mlp_{w2,w1,w0,b2,b1,b0}_step_float_close budget every rounded SGD parameter entry against \(\theta - \mathrm{lr}\cdot (a_i c_j)\), entry for entry, and the emitWeightGrad quantities the render closes (§ C.2.1) prove equal to the \(\operatorname {pdiv}\)-Jacobian contractions, so the float step chains to the proven gradient. The loss head: softmax_ce_cot_close budgets the rounded softmax-minus-onehot cotangent against the certified \(\partial (\mathrm{crossEntropy})/\partial (\mathrm{logits})\). Descent: sgd_descends proves an \(\eta \)-accurate gradient step still decreases the loss, and linear_sgd_descends discharges its smoothness hypothesis with the explicit constant \(2a^2/(1-2aD)\), with no Hessian, because the softmax ratio sandwich that powers the float budgets turns out to be the Lipschitz engine too. With the float budget fused in, so that the step’s \(\eta \) is the proven binary32 gradient accuracy rather than an assumed parameter, this closes for the linear classifier (linear_float_sgd_descends), the entire MLP (mlp_{output,hidden,input}_float_sgd_descends), and the entire Chapter-3 CNN, both conv weights and biases (cnn_conv{1,2}_float_sgd_descends). What is rounded in those statements is the gradient and nothing else: each is one example, the update \(\theta - \alpha \, \tilde g\) is taken in \(\mathbb {R}\), the loss it decreases is the real one, and the \(\exp \) inside the softmax enters through an accuracy hypothesis that the trained-weight instance (trained_linear_sgd_descends_concrete) discharges at the exact \(\exp \). The \(\mathbb {R}\)-side argument reaches one layer further: cifar8_lastConv_sgd_descends is the first non-MNIST descent. It is CIFAR-8’s last conv, proved as an instance of the CNN lemma at its frozen earlier features, and that framing is exactly why it stops there. The admissible \(\mathrm{lr}\) is a product of per-layer operator-norm factors, so each added layer shrinks it geometrically. Full-depth CIFAR and all five deep nets stay closeness-only, by design, not for want of effort.
The kink.
Over \(\mathbb {R}\), ReLU forced the hypotheses \(x_k \ne 0\). In float the same op inverts its role twice. The forward mask is exact, since compare-and-select rounds nothing, so the op that causes all the \(\mathbb {R}\)-side conditions is the free op here. But the backward mask reads the rounded pre-activation, so the hypotheses return with a number in them, \(\mathit{ez} {\lt} |z_i|\), meaning the accumulated rounding error must not flip a sign (reluMask_close). A qualitative side condition became a checkable margin.
Measured against proven.
The numeric capstones are instantiated at the trained magnitudes of a real 12-epoch, 97.8% GPU run (\(|W| \le 3/5\), covering the measured \(0.52\), and He initialization already exceeds prettier bounds in its tails). An f32/f64 twin of that run (scripts/certs/margin_probe.py, per-step coupled to match the single-step theorems) measures what the theorems bound:
|
quantity |
worst-case theorem |
measured |
|
logit drift |
\(\le 5100\) (mnist_mlp_float_budget) |
\(1.6\cdot 10^{-5}\) |
|
cotangent |
\(\le 21/1000\) (mnist_cot_budget) |
\(2.2\cdot 10^{-6}\) |
|
\(W_2\) SGD step |
\(\le 5/4\) (mnist_w2_step_float_budget) |
\(7.5\cdot 10^{-9}\) |
|
ReLU mask flips |
\(0\) under margins |
\(\mathbf{0}\, /\, 29.5\mathrm{M}\) |
The worst-case bounds hold with up to \(10^{8}\) to spare because worst-case composition compounds magnitude bounds the way no real activation pattern does. And the flip count is zero across 29.5 million measured pre-activations. The margin hypotheses are not a technicality the proofs hide behind. They are what training actually looks like.