1 MNIST: linear classifier
A VJP (vector-Jacobian product) is the backward function for a layer: takes an upstream gradient, returns the downstream one. Every backward function in this book is a VJP built by composing the foundation here. That foundation is the partial-derivative function \(\operatorname {pdiv}\) (defined via Mathlib’s \(\operatorname {fderiv}\)), its three structural rules of chain, sum, and product, and three VJP record types (\(\mathsf{HasVJP}\), \(\mathsf{HasVJPMat}\), \(\mathsf{HasVJP3}\), one per tensor rank) that bundle a backward function with its correctness claim.
This is the densest chapter in the book, by design. Going from nothing to a complete trained model is the entire machinery, and we build all of it here: the \(\operatorname {pdiv}\) calculus, the VJP framework, a forward pass, a loss, a backward pass, an SGD step, all the way down to the GPU. We do it on the smallest possible network (one matrix multiply: the MNIST linear classifier) to demonstrate the pattern. Once that machinery exists, every later chapter is just adding a layer: one new primitive dropped into the same forward / loss / backward / optimize loop.
1.1 Run it first
Before any of the math, train the thing. Four commands and about three seconds of GPU time:
lake exe cache get                            # Mathlib oleans, ~30 s
./scripts/datasets/download_mnist.sh          # ~11 MB
lake build mnist-linear-verified
./.lake/build/bin/mnist-linear-verified data
On one RTX 4060 Ti (CUDA 12.9), from runs/2026-09-01-linear-verified-xla-cuda/. XLA’s startup banner is removed and two long lines are wrapped:
[pjrt_ffi] XLA backend: PJRT 0.114, 1 device(s)
[pjrt_ffi] command buffers: enabled (CUDA default)
[pjrt_ffi] compiled verified_mlir/linear_train_step.mlir
             (@linear_train_step, 2 outputs, 1 replica) in 604 ms
[pjrt_ffi] compiled verified_mlir/linear_fwd.mlir
             (@linear_fwd, 1 outputs, 1 replica) in 116 ms
MNIST-Linear via the VERIFIED renderer (pretty∘emit) → XLA/PJRT → GPU
  xla/pjrt verified_mlir/linear_train_step.mlir
  xla/pjrt verified_mlir/linear_fwd.mlir
  train 60000, test 10000; dense 784->10, bs 128, SGD
  epoch 1: test_acc = 8977/10000 = 89.770000%  [95% CI 89.16–90.35] (173ms)
  epoch 2: test_acc = 9081/10000 = 90.810000%  [95% CI 90.23–91.36] (175ms)
  epoch 3: test_acc = 9123/10000 = 91.230000%  [95% CI 90.66–91.77] (217ms)
  epoch 4: test_acc = 9157/10000 = 91.570000%  [95% CI 91.01–92.10] (242ms)
  epoch 5: test_acc = 9167/10000 = 91.670000%  [95% CI 91.11–92.20] (219ms)
  epoch 6: test_acc = 9176/10000 = 91.760000%  [95% CI 91.20–92.28] (239ms)
  epoch 7: test_acc = 9186/10000 = 91.860000%  [95% CI 91.31–92.38] (239ms)
  epoch 8: test_acc = 9194/10000 = 91.940000%  [95% CI 91.39–92.46] (239ms)
  epoch 9: test_acc = 9199/10000 = 91.990000%  [95% CI 91.44–92.51] (243ms)
  epoch 10: test_acc = 9198/10000 = 91.980000%  [95% CI 91.43–92.50] (246ms)
  epoch 11: test_acc = 9203/10000 = 92.030000%  [95% CI 91.48–92.54] (247ms)
  epoch 12: test_acc = 9210/10000 = 92.100000%  [95% CI 91.56–92.61] (205ms)
done (trained MNIST-Linear via the proof-rendered StableHLO).
Twelve epochs at about 224 ms each, and 92.10% on the full 10,000-image test set. That is the going rate for a linear classifier on MNIST, and LeCun’s original 1998 benchmark put a comparable model at around 92%.
The bracketed interval is worth reading once, because every accuracy in this book carries one. 92.10% is 9,210 images out of 10,000, and a different 10,000 handwritten digits would not have given exactly that number; the 95% Wilson interval says the rate underneath it lies plausibly anywhere between 91.56 and 92.61%. The six decimal places the trainer prints are formatting rather than precision — only the first three digits are real, and on a test set this size a gap of less than about half a point is not yet a result.
This chapter’s accuracy is also the one that does not move. Trained five times over, the linear model finishes at 92.10% every time. It is zero-initialized rather than randomly, so there is no seed for the initializer to spend, and the only variation left is the order in which the GPU accumulates its sums — worth a single image at epochs 3 and 9, and nothing at all by epoch 12. Every later chapter has a real spread across seeds and reports it. This one has none to report, which makes it the cleanest baseline in the book to start from.
1.2 How it works
The theorems of this chapter all reduce to a single definition (\(\operatorname {pdiv}\)) plus chain rule, sum rule, and product rule, and every later chapter’s theorems reduce to this chapter’s. Before we drop you into the deep end, here is the shape of what’s coming, at the scale of chapters:
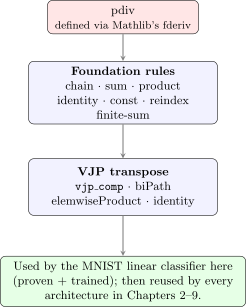
Read down a column, this is what one network’s certificate stands on; read across a row, this is what one chapter contributes, and this chapter’s row is the only one every column crosses. Each chapter’s theorems section opens with the same picture at the scale of its own statements, and the full clickable dependency graph is in the blueprint web view.
How the proofs are written.
The proofs in this book follow Lamport’s structured style (How to Write a 21st Century Proof). Hypotheses are named up front in an assume:/prove: header, with the matching Lean hypothesis name in brackets. The proof is a numbered sequence of steps. Each step carries its own proof naming exactly the facts it follows from, and the final step is always q.e.d., which explains why the steps prove the goal. In equational chains, \(\mathord {@}\) stands for the expression established by the previous step. Each step mirrors one tactic block of the corresponding Lean proof, so the informal argument can be audited against the formal one step by step. One-line lemmas (pdiv_id, pdiv_const, pdiv_reindex, the identity VJP) stay unstructured: structuring a one-simp proof would be ceremony.
1.3 The theorems
Figure 1-2 is the dependency graph of this section. Every chapter’s theorems section opens with its own, and the legend after this one applies to all of them.
The statements of this section and what each stands on, in the order the proofs compose them. A dashed box is a statement from elsewhere (its chapter, or above/below in this one); a double border marks a statement every chapter uses; one that feeds eight or more boxes of its own figure keeps its box, tagged with the count, and drops the arrows; a statement that leans on many others shows only what fits, and its \uses line has the rest; one that stands only on what every chapter uses hangs from the figure’s shared box, which says where those statements live; every box is a link.
The partial derivative function. For \(f : \mathbb {R}^{m} \to \mathbb {R}^{n}\), \(\operatorname {pdiv}\, f\, x\, i\, j\) is the \((i, j)\)-entry of the Jacobian at \(x\), defined as \(\operatorname {fderiv}_{\mathbb {R}}\, f\, x\, (\mathbf{e}_i)\, j\) — the \(j\)-th coordinate of Mathlib’s Fréchet derivative applied to the \(i\)-th standard basis vector.
assume:
\(f : \mathbb {R}^{m} \to \mathbb {R}^{n}\) is differentiable at \(x\) [hf]
\(g : \mathbb {R}^{n} \to \mathbb {R}^{p}\) is differentiable at \(f(x)\) [hg]
prove: for all \(i, k\):
Sketch: reduce to Mathlib’s chain rule for \(\operatorname {fderiv}\), then decompose over the standard basis to turn a composite of linear maps into the sum over the middle index.
\(\operatorname {pdiv}(g \circ f)\, x\, i\, k = \operatorname {fderiv}_{\mathbb {R}}\, (g \circ f)\, x\, (\mathbf{e}_i)\, k\).
proof: Definition 1.\(\operatorname {fderiv}_{\mathbb {R}}\, (g \circ f)\, x = \operatorname {fderiv}_{\mathbb {R}}\, g\, (f\, x) \circ \operatorname {fderiv}_{\mathbb {R}}\, f\, x\).
proof: Mathlib’s fderiv_comp, applicable by assumptions 1 and 2.Let \(v := \operatorname {fderiv}_{\mathbb {R}}\, f\, x\, (\mathbf{e}_i) \in \mathbb {R}^{n}\). Then \(v = \sum _j v_j \cdot \mathbf{e}_j\).
proof: Pointwise: at coordinate \(j'\) the sum collapses to \(v_{j'}\), because \((\mathbf{e}_j)_{j'}\) is the Kronecker delta.\(\operatorname {fderiv}_{\mathbb {R}}\, g\, (f\, x)\, v\, k = \sum _j v_j \cdot \operatorname {fderiv}_{\mathbb {R}}\, g\, (f\, x)\, (\mathbf{e}_j)\, k\).
proof: By 3 and linearity of \(\operatorname {fderiv}_{\mathbb {R}}\, g\, (f\, x)\) (LinearMap.pi_apply_eq_sum_univ, which is steps 3 and 4 in one lemma).q.e.d.
proof: By Definition 1, \(v_j = \operatorname {pdiv}f\, x\, i\, j\) and \(\operatorname {fderiv}_{\mathbb {R}}\, g\, (f\, x)\, (\mathbf{e}_j)\, k = \operatorname {pdiv}g\, (f\, x)\, j\, k\); chaining 1, 2, and 4 gives the goal.
assume:
\(f, g : \mathbb {R}^{m} \to \mathbb {R}^{n}\) are both differentiable at \(x\) [hf, hg]
prove: for all \(i, j\):
\(\operatorname {pdiv}(f + g)\, x\, i\, j = \operatorname {fderiv}_{\mathbb {R}}\, (f + g)\, x\, (\mathbf{e}_i)\, j\).
proof: Definition 1; the pointwise sum \(\lambda y\, k.\; f\, y\, k + g\, y\, k\) is definitionally the function \(f + g\).\(\operatorname {fderiv}_{\mathbb {R}}\, (f + g)\, x = \operatorname {fderiv}_{\mathbb {R}}\, f\, x + \operatorname {fderiv}_{\mathbb {R}}\, g\, x\).
proof: Mathlib’s fderiv_add, applicable by the assumption.q.e.d.
proof: Evaluate 2 at \((\mathbf{e}_i, j)\); by Definition 1 the two terms are \(\operatorname {pdiv}f\, x\, i\, j\) and \(\operatorname {pdiv}g\, x\, i\, j\).
assume:
\(f, g : \mathbb {R}^{m} \to \mathbb {R}^{n}\) are both differentiable at \(x\) [hf, hg]
prove: for all \(i, j\):
where \((f \odot g)\, y\, k = f\, y\, k \cdot g\, y\, k\) is the elementwise product.
\(\operatorname {pdiv}(f \odot g)\, x\, i\, j = \operatorname {fderiv}_{\mathbb {R}}\, (f \cdot g)\, x\, (\mathbf{e}_i)\, j\).
proof: Definition 1; the elementwise product is definitionally the algebra product \(f \cdot g\) in \(\mathbb {R}^{n}\) (Pi.normedAlgebra), so Mathlib’s calculus of algebra-valued maps applies.\(\operatorname {fderiv}_{\mathbb {R}}\, (f \cdot g)\, x = f\, x \cdot \operatorname {fderiv}_{\mathbb {R}}\, g\, x + g\, x \cdot \operatorname {fderiv}_{\mathbb {R}}\, f\, x\) (scalar action taken pointwise).
proof: Mathlib’s fderiv_mul, applicable by the assumption.q.e.d.
proof: Evaluate 2 at \((\mathbf{e}_i, j)\): the pointwise scalar action gives \(f\, x\, j \cdot \operatorname {pdiv}g\, x\, i\, j + g\, x\, j \cdot \operatorname {pdiv}f\, x\, i\, j\) by Definition 1; commute the second summand (ring) to match the goal.
\(\operatorname {pdiv}(\mathrm{id})\, x\, i\, j = \delta _{ij}\).
Mechanical; see Proofs.pdiv_id.
\(\operatorname {pdiv}(\lambda \_ .\; c)\, x\, i\, j = 0\) for any constant \(c \in \mathbb {R}^{n}\).
Mechanical; see Proofs.pdiv_const.
For \(\sigma : \mathrm{Fin}\, b \to \mathrm{Fin}\, a\),
Covers permutations, reshapes, slicing. Generalizes pdiv_id (\(\sigma = \mathrm{id}\)). A gather is a continuous linear map (reindexCLM), so the argument is the affine rule’s (Theorem 9): the map is its own derivative, evaluated at \(\mathbf{e}_i\).
Mechanical; see Proofs.pdiv_reindex.
assume:
\(S\) is a finite index set with a function \(f_s : \mathbb {R}^{m} \to \mathbb {R}^{n}\) for each \(s \in S\)
every \(f_s\) is differentiable at \(x\) [hdiff]
prove: for all \(i, j\):
The coordinatewise sum \(\lambda y\, k.\, \sum _{s \in S} f_s\, y\, k\) is the pointwise sum of functions \(\sum _{s \in S} f_s\).
proof: Extensionality (Finset.sum_apply).\(\operatorname {fderiv}_{\mathbb {R}}\bigl(\sum _{s \in S} f_s\bigr)\, x = \sum _{s \in S} \operatorname {fderiv}_{\mathbb {R}}\, f_s\, x\).
proof: Mathlib’s fderiv_fun_sum, applicable by assumption 2.q.e.d.
proof: Evaluate 2 at \((\mathbf{e}_i, j)\) (Definition 1); a sum of linear maps evaluates pointwise (Finset.sum_apply).
assume:
\(f : \mathbb {R}^{m} \to \mathbb {R}^{n}\) is additive, \(f(u + v) = f(u) + f(v)\) [hadd]
\(f\) is homogeneous, \(f(a \cdot v) = a \cdot f(v)\) [hsmul]
prove: for every constant \(c \in \mathbb {R}^{n}\), every \(x\) and all \(i, j\):
At \(c = 0\) this is pdiv_of_linear: the Jacobian of a linear map is the map itself, read on the standard basis. There is no differentiability hypothesis, because a linear map on a finite-dimensional space is continuous and so is its own derivative everywhere. This is the rule every layer that is linear in the variable being differentiated goes through — dense in \(x\), in \(W\) and in \(b\); conv, depthwise and the patch embedding in each of their arguments; BatchNorm’s centering and affine steps; matmul against a constant factor — in place of distributing the sum, product and reindex rules through the layer’s definition term by term. Each use is two one-line algebra side conditions, then the entry is read off \(f(\mathbf{e}_i)\) and a Kronecker indicator collapses.
Assumptions 1 and 2 make \(f\) an \(\mathbb {R}\)-linear map \(L\), and \(L\) is continuous because \(\mathbb {R}^{m}\) is finite-dimensional.
proof: Bundle the two laws; LinearMap.continuous_on_pi.\(\operatorname {fderiv}_{\mathbb {R}}\, (v \mapsto L\, v + c)\, x = L\).
proof: fderiv_add_const drops \(c\), and a continuous linear map is its own Fréchet derivative (ContinuousLinearMap.fderiv).q.e.d.
proof: Evaluate 2 at \((\mathbf{e}_i, j)\) by Definition 1.
For \(f : \mathbb {R}^{m} \to \mathbb {R}^{n}\), \(\mathsf{HasVJP}\, f\) bundles a backward function \(B : \mathbb {R}^{m} \to \mathbb {R}^{n} \to \mathbb {R}^{m}\) with its correctness claim: for all \(x\), \(dy\), \(i\),
Exhibiting a \(\mathsf{HasVJP}\, f\) is exactly the statement “this backward function computes the vector–Jacobian product of \(f\).” Some witness exists for every \(f\): take \(B\) to be the contraction itself (HasVJP.canonical). So a witness says something only through what its \(B\) is: a formula such as a layer’s closed-form backward, the per-layer backwards composed in reverse order, or a rendered chain proved equal to one of those.
assume:
\(B_f\) is a correct backward function for \(f\) (\(\mathsf{HasVJP}\, f\)) [hf]
\(B_g\) is a correct backward function for \(g\) (\(\mathsf{HasVJP}\, g\)) [hg]
\(f\) is differentiable everywhere [hf_diff]
\(g\) is differentiable everywhere [hg_diff]
prove: \(\mathsf{HasVJP}\, (g \circ f)\).
Sketch: the composite backward is “run \(B_g\), feed the result to \(B_f\)”; correctness is the two correct fields glued by the chain rule for \(\operatorname {pdiv}\).
Define \(B(x, dy) := B_f\bigl(x,\; B_g(f\, x,\; dy)\bigr)\).
suffices: for all \(x\), \(dy\), \(i\): \(B(x, dy)_i = \sum _k \operatorname {pdiv}(g \circ f)\, x\, i\, k \cdot dy_k\).
proof: Definition 10, with \(B\) as the candidate backward function.\(B(x, dy)_i = \sum _j \operatorname {pdiv}f\, x\, i\, j \cdot B_g(f\, x, dy)_j\).
proof: Correctness of \(B_f\) (assumption 1).\(\mathord {@}= \sum _j \operatorname {pdiv}f\, x\, i\, j \sum _k \operatorname {pdiv}g\, (f\, x)\, j\, k \cdot dy_k\).
proof: Correctness of \(B_g\) (assumption 2).\(\mathord {@}= \sum _k \Bigl(\sum _j \operatorname {pdiv}f\, x\, i\, j \cdot \operatorname {pdiv}g\, (f\, x)\, j\, k\Bigr)\, dy_k\).
proof: Distribute and swap the two sums (Finset.mul_sum, Finset.sum_comm); both are finite, so no convergence question arises.q.e.d.
proof: By the chain rule (Theorem 2), applicable at every \(x\) by assumptions 3 and 4, the inner sum in 5 is \(\operatorname {pdiv}(g \circ f)\, x\, i\, k\); with 2 this is the goal.
Used for residual connections. assume:
\(B_f\) is a correct backward function for \(f\) (\(\mathsf{HasVJP}\, f\)) [hf]
\(B_g\) is a correct backward function for \(g\) (\(\mathsf{HasVJP}\, g\)) [hg]
\(f\) is differentiable everywhere [hf_diff]
\(g\) is differentiable everywhere [hg_diff]
prove: \(\mathsf{HasVJP}\, (f + g)\).
Define \(B(x, dy)_i := B_f(x, dy)_i + B_g(x, dy)_i\).
suffices: for all \(x\), \(dy\), \(i\): \(B(x, dy)_i = \sum _j \operatorname {pdiv}(f + g)\, x\, i\, j \cdot dy_j\).
proof: Definition 10, with \(B\) as the candidate backward function.\(B(x, dy)_i = \sum _j \bigl(\operatorname {pdiv}f\, x\, i\, j + \operatorname {pdiv}g\, x\, i\, j\bigr) \cdot dy_j\).
proof: Correctness of \(B_f\) and \(B_g\) (assumptions 1, 2); merge the two finite sums (Finset.sum_add_distrib) and factor out \(dy_j\) (ring).q.e.d.
proof: The sum rule (Theorem 3), applicable at every \(x\) by assumptions 3 and 4, rewrites the bracket in 3 to \(\operatorname {pdiv}(f + g)\, x\, i\, j\); with 2 this is the goal.
Used for Squeeze-and-Excitation. assume:
\(B_f\) is a correct backward function for \(f\) (\(\mathsf{HasVJP}\, f\)) [hf]
\(B_g\) is a correct backward function for \(g\) (\(\mathsf{HasVJP}\, g\)) [hg]
\(f\) is differentiable everywhere [hf_diff]
\(g\) is differentiable everywhere [hg_diff]
prove: \(\mathsf{HasVJP}\, (f \odot g)\) for \(f, g : \mathbb {R}^{n} \to \mathbb {R}^{n}\), where \((f \odot g)\, x\, i = f\, x\, i \cdot g\, x\, i\).
Define \(B(x, dy)_i := B_f\bigl(x,\; g(x) \odot dy\bigr)_i + B_g\bigl(x,\; f(x) \odot dy\bigr)_i\), where \(\bigl(g(x) \odot dy\bigr)_j = g\, x\, j \cdot dy_j\).
suffices: for all \(x\), \(dy\), \(i\): \(B(x, dy)_i = \sum _j \operatorname {pdiv}(f \odot g)\, x\, i\, j \cdot dy_j\).
proof: Definition 10, with \(B\) as the candidate backward function.\(B(x, dy)_i = \sum _j \bigl(\operatorname {pdiv}f\, x\, i\, j \cdot g\, x\, j + f\, x\, j \cdot \operatorname {pdiv}g\, x\, i\, j\bigr) \cdot dy_j\).
proof: Correctness of \(B_f\) at upstream gradient \(g(x) \odot dy\) and of \(B_g\) at \(f(x) \odot dy\) (assumptions 1, 2); merge the two finite sums and factor out \(dy_j\) (Finset.sum_add_distrib, ring).q.e.d.
proof: The product rule (Theorem 4), applicable at every \(x\) by assumptions 3 and 4, identifies the bracket in 3 with \(\operatorname {pdiv}(f \odot g)\, x\, i\, j\); with 2 this is the goal.
\(\mathsf{HasVJP}\, \mathrm{id}\), with backward \(B(x, dy) = dy\): the identity passes the upstream gradient through unchanged.
Mechanical; see Proofs.identityHasVJP.
The dense layer
Everything above is machinery. Here is the first layer it is used on, and the one every network in this book ends in.
A neural network is a long chain of functions, and “training” means using the partials of those functions to nudge their parameters in a direction that reduces a loss. Two different motions, and this book keeps two words for them: you nudge a parameter to move the loss, and you jiggle an input to find out what would move it. Every theorem from here to the end of the book is the answer to the same question, asked about a different building block: if I jiggle this input by \(\varepsilon \), how does the output jiggle?
For a scalar function \(f : \mathbb {R} \to \mathbb {R}\) the answer is one number, the derivative. A layer takes \(n\) numbers in and puts \(m\) numbers out, so the full picture of how every output coordinate responds to every input coordinate is an \(m \times n\) table of slopes, one per (output, input) pair. That table is the Jacobian, and \(\operatorname {pdiv}\) above is one entry of it at a chosen \((i, j)\).
Our smallest building block is a dense (or “fully connected”) layer: \(y = Wx + b\), where \(W\) is an \(m \times n\) weight matrix, \(x\) is an \(n\)-vector, and \(b\) is an \(m\)-vector. Pick any output coordinate \(y_j\) and write it out:
Now jiggle \(x_i\) by \(\varepsilon \). Of the \(n\) terms in the sum, only the \(k = i\) term notices, and it changes by \(W_{ji}\, \varepsilon \). So \(\partial y_j / \partial x_i = W_{ji}\). The Jacobian of \(y = Wx + b\) with respect to \(x\) is the weight matrix \(W\) itself. No new structure and no surprise, because the Jacobian of a linear map is the linear map, written as a matrix.
The same exercise for the partial with respect to \(W\) gives an analogous answer: the dependence is local, and the entries of the Jacobian are just \(x_{i'}\, \delta _{jj'}\). These two, the input-Jacobian and the weight-Jacobian, are the only objects a dense layer needs.
Training does not multiply Jacobians together. What it wants is the Jacobian transposed and applied to the upstream gradient \(dy\), which is the VJP of Definition 10, and for a dense layer the three answers fall out by transposing the picture above:
Two more notions, used by the ImageNet chapters’ loss-gradient theorems: a scalar function with a known gradient at a point, and how such a gradient pulls back through a certified VJP into a parameter’s loss gradient.
For \(G : \mathbb {R}^{m} \to \mathbb {R}^{1}\) and \(x, dy \in \mathbb {R}^{m}\), \(\texttt{HasGradAt}\, G\, x\, dy\) says \(G\) is differentiable at \(x\) and \(\operatorname {pdiv}\, G\, x\, j\, 0 = dy_j\) for every \(j\). The loss read at any activation of a network is such a \(G\), and the chain’s cotangent there is its \(dy\). The differentiability is part of the claim: \(\operatorname {pdiv}\) alone is \(0\) wherever \(G\) is not differentiable.
assume:
\(G\) has gradient \(dy\) at \(f(x)\) [hG]
\(f\) is differentiable at \(x\), with a VJP there [hf, vf]
prove: \(G \circ f\) has gradient \(\mathrm{backward}\, dy\) at \(x\), the VJP’s backward of \(dy\) (HasGradAt.comp). Read at a parameterised op \(\theta \mapsto \mathrm{layer}\, \theta \) whose output gradient is \(dy\), the loss as a function of \(\theta \) has gradient the op’s parameter Jacobian against it, \(\sum _j \operatorname {pdiv}\, \mathrm{layer}\, \theta \, i\, j \cdot dy_j\) (HasGradAt.param); at a batched op it is the \(\sum _n \sum _j\) every batched gradient node denotes (HasGradAt.param_batchMap).
The chain rule (Theorem 2) at the composite, then the VJP’s correctness field and the gradient hypothesis for \(G\); the parameterised readings take the op as \(f\), differentiable in \(\theta \).
One convention to fix before the theorems, because the prose and the Lean write the weight matrix two ways. The prose writes \(y = Wx + b\) with \(W\) output-major, so the input gradient is \(dx = W^{\top } dy\). The Lean stores \(W\) input-major — \(\mathrm{dense}(W, b)\, x\, j = \sum _i x_i W_{ij} + b_j\), which is what the dense listing in the introduction says — so the same gradient reads \(B(x, dy) = W\, dy\) in Theorem 19, and in the MLIR it is a contraction over the output axis of both operands. One transpose, three spellings.
For the dense layer \(\mathrm{dense}(W, b)\, x = \lambda j.\; \bigl(\sum _i x_i\, W_{ij}\bigr) + b_j\):
No hypotheses: dense is affine, so the differentiability obligations are discharged inside the proof rather than assumed.
Sketch: the layer is a linear map plus the constant \(b\); the affine rule reads the Jacobian entry off the basis vector.
\(\mathrm{dense}(W, b) = \bigl(y \mapsto \lambda j'.\, \textstyle \sum _{i'} y_{i'} W_{i'j'}\bigr) + b\), and the first summand is additive and homogeneous in \(y\).
proof: Unfold; \(\sum _{i'} (u + v)_{i'} W_{i'j'}\) and \(\sum _{i'} (a\, u)_{i'} W_{i'j'}\) distribute (add_mul, Finset.sum_add_distrib, Finset.mul_sum).\(\operatorname {pdiv}\bigl(\mathrm{dense}(W, b)\bigr)\, x\, i\, j = \sum _{i'} (\mathbf{e}_i)_{i'}\, W_{i'j}\).
proof: Affine rule (Theorem 9) with 1.q.e.d.
proof: \((\mathbf{e}_i)_{i'} = \delta _{i i'}\), so the sum collapses to \(W_{ij}\) (Finset.sum_ite_eq).
The symmetric counterpart of Theorem 17, differentiating in \(W\) instead of \(x\). Since \(\operatorname {pdiv}\) works on vectors, view the layer as a function of the flattened weights: for \(v \in \mathbb {R}^{m \cdot n}\), let \(F(v) := \mathrm{dense}(\mathrm{unflatten}\, v,\, b)\, x\), and write \(\varphi \) for the index bijection \((i, j) \leftrightarrow \varphi (i, j)\) (finProdFinEquiv). prove: for all \(i, j', j\):
Sketch: as Theorem 17, with the flatten bijection inside the linear part.
\(F(v)_{j_o} = \bigl(\sum _{i'} x_{i'} \cdot v_{\varphi (i', j_o)}\bigr) + b_{j_o}\), and the first summand is additive and homogeneous in \(v\).
proof: Unfold \(\mathrm{dense}\) and \(\mathrm{unflatten}\); mul_add, Finset.sum_add_distrib, Finset.mul_sum.\(\operatorname {pdiv}F\, (\mathrm{flatten}\, W)\, \varphi (i, j')\, j = \sum _{i'} x_{i'} \cdot (\mathbf{e}_{\varphi (i, j')})_{\varphi (i', j)}\).
proof: Affine rule (Theorem 9) with 1.q.e.d.
proof: The basis entry is \(1\) exactly when \(\varphi (i, j') = \varphi (i', j)\), which by injectivity of \(\varphi \) is \(i' = i \wedge j = j'\). If \(j = j'\) the sum collapses to \(x_i\); otherwise every term is \(0\). Both match \(\delta _{jj'}\, x_i\).
\(\mathsf{HasVJP}\, \bigl(\mathrm{dense}(W, b)\bigr)\): the input-gradient backward of a dense layer is multiplication by \(W\).
Define \(B(x, dy) := W\, dy\), i.e. \(B(x, dy)_i = \sum _j W_{ij}\, dy_j\).
suffices: for all \(x\), \(dy\), \(i\): \(B(x, dy)_i = \sum _j \operatorname {pdiv}\bigl(\mathrm{dense}(W, b)\bigr)\, x\, i\, j \cdot dy_j\).
proof: Definition 10, with \(B\) as the candidate backward function.q.e.d.
proof: The Dense Jacobian (Theorem 17) gives \(\operatorname {pdiv}\bigl(\mathrm{dense}(W, b)\bigr)\, x\, i\, j = W_{ij}\); substituting into 2 leaves exactly \(\sum _j W_{ij}\, dy_j = B(x, dy)_i\).
\(dW = x \otimes dy\), with \(F\) and \(\varphi \) as in Theorem 18, prove: for all \(i, j\):
Each summand: \(\operatorname {pdiv}F\, (\mathrm{flatten}\, W)\, \varphi (i, j)\, k \cdot dy_k = (\text{if } k = j \text{ then } x_i \text{ else } 0) \cdot dy_k\).
proof: Dense Jacobian wrt weight (Theorem 18).q.e.d.
proof: The sum in 1 collapses at \(k = j\) (Finset.sum_ite_eq) to \(x_i \cdot dy_j\), which is \((x \otimes dy)_{ij}\) by definition of the outer product.
\(db = dy\). prove: for all \(i\):
\(\operatorname {pdiv}\bigl(b' \mapsto \mathrm{dense}(W, b')\, x\bigr)\, b\, i\, j = \delta _{ij}\).
proof: As a function of \(b'\), the layer is \(b' + (\text{constant in } b')\), the identity plus a constant, so the affine rule (Theorem 9) at \(f = \mathrm{id}\) gives \((\mathbf{e}_i)_j = \delta _{ij}\). (This is the Lean lemma pdiv_dense_b.)q.e.d.
proof: Substitute 1: \(\sum _j \delta _{ij}\, dy_j = dy_i\) (Finset.sum_ite_eq).
The loss
The last building block is the loss: softmax cross-entropy between the model’s output \(z \in \mathbb {R}^{10}\) and the true class label \(y \in \{ 0, \ldots , 9\} \). The full computation is
The loss is a scalar, so its Jacobian with respect to \(z\) is a vector, not a matrix. Working through the algebra (chain rule on \(-\log \circ \mathrm{softmax}\) at the label index) produces a remarkably clean answer:
The gradient of the loss is the difference between the model’s predicted distribution and the truth. Theorem 22 makes this formal. Its one ingredient from outside this chapter is the softmax Jacobian, which is proved in Chapter 9 alongside the rest of the softmax machinery and used here as a finished fact.
Write \(p := \mathrm{softmax}(z)\) and \(\mathrm{CE}(z, \ell ) := -\log p_\ell \) (viewed as \(\mathbb {R}^{1}\)-valued so \(\operatorname {pdiv}\) applies; we read off the only output coordinate). prove: for all \(j\):
Sketch: chain rule on \(-\log \circ (z \mapsto p_\ell )\), with the softmax Jacobian (proved in Ch 9) supplying the inner derivative; the \(1/p_\ell \) from \(\log \) cancels the \(p_\ell \) the Jacobian produces.
\(p_\ell {\gt} 0\), in particular \(p_\ell \neq 0\).
proof: \(p_\ell \) is a positive exponential over a positive finite sum of exponentials.\(\operatorname {pdiv}\bigl(\mathrm{CE}(\cdot , \ell )\bigr)\, z\, j\, 0 = \operatorname {fderiv}_{\mathbb {R}}\, \bigl(z' \mapsto \mathrm{CE}(z', \ell )\bigr)\, z\, (\mathbf{e}_j)\).
proof: Definition 1; the \(\mathbb {R}^{1}\) wrapper just evaluates the single output coordinate (pdiv_eq_fderiv_coord), legitimate because the wrapper is differentiable — \(\mathrm{softmax}\) is differentiable and \(\log \) is differentiable away from \(0\), which 1 grants.\(\operatorname {fderiv}_{\mathbb {R}}\, \bigl(z' \mapsto \mathrm{CE}(z', \ell )\bigr)\, z = -\bigl(p_\ell ^{-1} \cdot \operatorname {fderiv}_{\mathbb {R}}\, (z' \mapsto \mathrm{softmax}(z')_\ell )\, z\bigr)\).
proof: \(\mathrm{CE}(\cdot , \ell ) = -\log \circ (z' \mapsto \mathrm{softmax}(z')_\ell )\); HasFDerivAt.log with 1 differentiates the \(\log \), then negate.\(\operatorname {fderiv}_{\mathbb {R}}\, (z' \mapsto \mathrm{softmax}(z')_\ell )\, z\, (\mathbf{e}_j) = \operatorname {pdiv}(\mathrm{softmax})\, z\, j\, \ell = p_\ell \, (\delta _{j\ell } - p_j)\).
proof: Definition 1, then the softmax Jacobian (Theorem 131).q.e.d.
proof: Chain 2–4: \(-p_\ell ^{-1} \cdot p_\ell \, (\delta _{j\ell } - p_j) = p_j - \delta _{j\ell }\), cancelling by 1; and \(\mathrm{onehot}(\ell )_j = \delta _{j\ell }\) by definition.
Three certificates close this chapter and each of the next three: the emitted train step is the certified step (a fold over its update operations), each gradient node is the loss’s derivative in its parameter, and one SGD step decreases the loss.
For a batch of \(N\) examples \(x_k\) with labels \(\ell _k\), write \(L_k(W) := \mathrm{CE}(\mathrm{dense}(W, b)\, x_k,\ \ell _k)\) for example \(k\)’s loss at fixed \(b\), and \(p_k := \mathrm{softmax}(\mathrm{dense}(W, b)\, x_k)\). prove: the two update operations of § 1.7’s linear_train_step.mlir, read as the batched graph that text is the print of, denote
for every \(N\); and at \(\alpha = \eta / N\), \(N \ge 1\), the weight update is one gradient step at rate \(\eta \) on the batch-mean loss \(\tfrac {1}{N}\sum _k L_k\). That is, the emitted step is the certified gradient step on the batch, the forward it differentiates is the proven fwdGraph lifted across the batch, and the artifact is the instance \(N = 128\), \(\alpha = 0.1/128\). (The single-example reading, poc_train_step_tail_certified, is the \(N = 1\) case; the batched graph prints the committed text byte for byte, tests/TestSmallNetsBatchedEmit.lean.)
Each emitted operation’s denotation is by definition the certified update (poc_weightSgd_den_eq, poc_biasSgd_den_eq); the weight half is Theorem 20 composed with Theorem 22 by the chain rule, the bias half Theorem 21 at that cotangent; the batched reading slices each node into its \(N\) per-example terms; see Proofs.LinFoldB.lin_train_step_tiedB.
assume:
\(L\) is any loss of the logits, with gradient \(g\) there [hL]
prove: the classifier’s weight and bias gradient nodes, fed \(g\), are \(\partial L/\partial W\) and \(\partial L/\partial b\) of mnistLinear with that one parameter varied: \(L\) is differentiable in it and the node is its gradient. Instantiated at the softmax cross-entropy with the emitted loss cotangent.
Theorem 16 at the dense layer’s two parameter Jacobians (Theorems 20 and 21); see Proofs.LinFold.linear_net_lossGrad.
assume:
every pixel is bounded, \(|x_i| \le a\) [hx]
the gradient \(g\) the step uses is within \(\eta \) of \(\nabla L\) in every coordinate [hgh]
the small-step condition \(2aD {\lt} 1\) at the step’s \(\ell _1\)-radius \(D := \alpha \, (\| \nabla L\| _1 + mn\, \eta )\) [hsmall]
the error is dominated by the gradient: \(\alpha \eta \, \| \nabla L\| _1\) and \(\tfrac {2a^2}{1-2aD}\, D^2\) are each at most \(\alpha \, \| \nabla L\| _2^2/4\) [h1, h2]
\(a\), \(\alpha \) and \(\eta \) are non-negative [ha, hlr, h\(\eta \)]
prove: the step on the weights, at one example with the bias fixed, decreases the loss,
The same holds at the bias, and with the binary32 gradient in place of \(g\), its \(\eta \) the rounding budget of § B.5 rather than an assumption, under that forward’s exp-accuracy and logit-drift bounds.
The descent lemma along the segment from \(W\) to \(W - \alpha g\), its Lipschitz hypothesis discharged with the explicit constant \(2a^2/(1-2aD)\) and no Hessian: the gradient is \(x_i\, (p_j - \mathrm{onehot}(\ell )_j)\) by Theorems 18 and 22, the logits move linearly in \(W\), and a softmax perturbation bound turns that into a gradient drift linear along the segment. The binary32 form supplies \(\eta \) by linear_grad_close; see Proofs.linear_sgd_descends.
1.4 Example: MNIST linear classifier
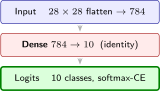
The smallest network that learns: a single dense layer mapping 784-dim images to 10-dim logits, trained with softmax cross-entropy and plain SGD. About 7,850 parameters. \(\sim \)92% test accuracy in seconds. Figure 1-3 is the whole network.
The forward pass and loss, in math.
For an input image \(x \in \mathbb {R}^{784}\) and true class index \(t \in \{ 0, \dots , 9\} \):
The trainable parameters are \(W\) and \(b\), which is 7,850 floats in total.
The same thing, as a VerifiedNetSpec.
def linearVerified : VerifiedNetSpec where
  name     := "MNIST-Linear"
  slug     := "linear"
  inC      := 1
  imageH   := 28
  imageW   := 28
  data     := .mnist
  layers   := [.dense 784 10]
  blurb    := "MNIST-Linear via the VERIFIED renderer
                (pretty∘emit) → %LOWERER% → GPU"
The layer emits raw logits \(z = W x + b\). Softmax and cross-entropy are added by the training driver, because this is a classification task. The slug names the committed render, so this spec is bound to verified_mlir/linear_train_step.mlir and linear_fwd.mlir, which are the two files the run at the top of the chapter compiled. The blurb is the banner the run prints before its first epoch, %LOWERER% filled in with whichever lowerer was selected; it is one line in the source and wrapped here.
What .dense 784 10 contributes.
Layers are constructors of a VLayer inductive, and one function, toSpecs, says what each contributes to the parameter list as (dims, initKind) pairs — 0 is He(fan-in), 1 is ones, 2 is zeros:
def toSpecs : VLayer -> Array (Array Nat × Nat)
  | dense ic oc => #[(#[ic,oc],0),(#[oc],2)]
  | ...
Two tensors: a \(784 \times 10\) weight matrix and a length-10 bias. That is this network’s entire parameter list, and d0, the input width the render needs, is derived from the same list rather than declared separately. Every chapter after this one adds an arm to that match. None of them changes this one, so this is the last time you will see it.
The init codes are the shared driver’s defaults, and this chapter is the one place they do not apply. trainLinear sets both tensors to zero outright rather than reading them off toSpecs, which is why the run at the top of the chapter lands on the same accuracy whatever the seed. From Chapter 2 onward the codes apply as written.
That binding is why the type exists. The spec lives in LeanMlir/Verified/NetsCore.lean rather than beside the trainer, because the theorem and the program have to name the same object. In LeanMlir/Proofs/SpecVJP.lean:
noncomputable def linearVerifiedHasVJP (W : Mat 784 10) (b : Vec 10) :
    HasVJP (denoteLinear linearVerified.layers W b) :=
  denseHasVJP W b
Read the type. The VJP is proved for the denotation of linearVerified.layers, and that is the same field the trainer reads to build its graph. Copy the layer list into a second definition and the proof would be about a different network than the one that runs.
The whole program.
The trainer is 54 lines including its docstring, so here it is entire, with the comments stripped:
import LeanMlir.Verified.NetsCore
import LeanMlir.Verified.Train

def linearConfig : VerifiedConfig where
  epochs    := 12
  batchSize := 128

def main (argv : List String) : IO Unit :=
  linearVerified.toNet.trainLinear linearConfig (argv.head?.getD "data")
That is apps/mnist/MainMnistLinearVerified.lean, all of it. One spec, one config, one call: toNet lowers the spec to the runtime net the driver consumes, and trainLinear trains it. The GPU backend does not appear in it at all, because the shim is opened with dlopen at run time.
Notice also what linearConfig does not carry: a learning rate. The real rate is baked into verified_mlir/linear_train_step.mlir at render time, so the recipe that trains is the recipe the proofs describe, and the two cannot drift apart.
The gradient, in math.
Backpropagation through this network produces a single outer product:
where \(e_t \in \mathbb {R}^{10}\) is the one-hot vector for the true class. The dense VJP and its weight and bias gradients (Theorems 19–21) and the softmax-CE gradient (Theorem 22) above are what guarantee these formulas are correct. The verified renderer emits exactly these as fused StableHLO, and that rendering is verified_mlir/linear_train_step.mlir, the file the run at the top of the chapter compiled.
Results.
The run at the top of this chapter is this network. Accuracy climbs from 89.77% after one epoch to 92.10% after twelve, and the curve is essentially flat from epoch 9 on, which is what a model with no hidden layer looks like once it has learned everything it can. Adding hidden layers and ReLU in Chapter 2 takes the same dataset and the same recipe to 97.81% (runs/2026-09-01-mlp-verified-xla-cuda/). That gap of about 5.7 points is the value of non-linearity on this task.
Where this goes.
Every architecture in Part 1 extends this template the same way, one new primitive at a time:
Ch 2 stacks dense layers and inserts ReLU between them. One new operator VJP.
Ch 3 swaps the dense forward for conv2d. One new operator VJP.
Ch 4 adds BatchNorm. One new operator VJP.
Ch 5 adds the residual skip. Additive fan-in, Theorem 12, and no new operator at all.
Ch 6 factors standard conv into depthwise plus pointwise. One new operator VJP, recombined through the chain rule.
Ch 7 adds the SE channel-attention block, which is an elementwise product over global pooling and dense layers. One new VJP composed from pieces we already have.
Ch 8 replaces ReLU with GELU. One new operator.
Ch 9 adds attention, which needs new matrix-level machinery and softmax-VJP chains.
The structural rules from this chapter never change. Later chapters add operator-specific theorems and compose them through the chain rule we just proved. The driver that runs all of them is the same Lean either way, and it is shorter than you would expect, which is the subject of §1.6.
1.5 MLIR: Linear
The StableHLO in this section is the artifact the proofs are about, and it is what XLA compiles and runs. Nothing between the theorem and the GPU rewrites it.
The forward half is short enough to print whole. This is verified_mlir/linear_fwd.mlir exactly as committed, and it is one of the two files the run at the top of the chapter compiled:
module @m {
  func.func @linear_fwd(%x: tensor<128x784xf32>,
                        %W0: tensor<784x10xf32>,
                        %b0: tensor<10xf32>) -> tensor<128x10xf32> {
    %v0 = stablehlo.dot_general %x, %W0,
            contracting_dims = [1] x [0],
            precision = [DEFAULT, DEFAULT]
            : (tensor<128x784xf32>, tensor<784x10xf32>)
              -> tensor<128x10xf32>
    %v1 = stablehlo.broadcast_in_dim %b0, dims = [1]
            : (tensor<10xf32>) -> tensor<128x10xf32>
    %v2 = stablehlo.add %v0, %v1 : tensor<128x10xf32>
    return %v2 : tensor<128x10xf32>
  }
}
Three operations for \(z = Wx + b\): a contraction, a broadcast of the bias across the batch, and an add. The shapes are the real ones, batch 128 against 784 inputs and 10 classes, because this file is the render that trains and not an illustration of one.
The backward is two gradients, not one. Nothing sits upstream of the input, so the linear classifier never needs \(dx\); what it needs is \(dW = x^{\! \top } dy\) and \(db = \sum _{\text{batch}} dy\), with \(dy = \mathrm{softmax}(\mathrm{logits}) - \text{onehot}\) the loss cotangent. Here they are as the other file the run compiled, verified_mlir/linear_train_step.mlir, emits them. The SSA names are the artifact’s, the default precision attribute is dropped, and the long lines are wrapped for the page:
%v7 = stablehlo.divide %v3, %v6 : tensor<128x10xf32>
%v8 = stablehlo.subtract %v7, %onehot : tensor<128x10xf32>
%v9 = stablehlo.dot_general %x, %v8, contracting_dims = [0] x [0]
      : (tensor<128x784xf32>, tensor<128x10xf32>) -> tensor<784x10xf32>
%v10 = stablehlo.constant dense<0.00078125> : tensor<784x10xf32>
%v11 = stablehlo.multiply %v9, %v10 : tensor<784x10xf32>
%v12 = stablehlo.subtract %W0, %v11 : tensor<784x10xf32>
// ...
%v23 = stablehlo.reduce(%v21 init: %v22)
      applies stablehlo.add across dimensions = [0] : (tensor<128x10xf32>,
      tensor<f32>) -> tensor<10xf32>
%v24 = stablehlo.constant dense<0.00078125> : tensor<10xf32>
%v25 = stablehlo.multiply %v23, %v24 : tensor<10xf32>
%v26 = stablehlo.subtract %b0, %v25 : tensor<10xf32>
%v8 is \(dy\). The dot_general at %v9 contracts axis \(0\) of \(x\) against axis \(0\) of \(dy\), the batch axis of each, which is \(x^{\! \top } dy\) summed over the 128 examples; %v10–%v12 scale it by \(0.00078125 = 0.1/128\) and subtract it from \(W_0\). The bias gradient at %v23 is the same batch sum with nothing to contract against, and %v26 is its update. Theorem 23 is the statement that these two returned tensors denote one SGD step on the certified gradient at batch 128, and that with the rate folded in as \(\alpha /N\) it is a step at rate \(0.1\) on the batch-mean loss. The graph that theorem is about is a Lean value, and tests/TestSmallNetsBatchedEmit.lean checks that printing it reproduces this file byte for byte.
Everything else in this book scales that one move up. Each architecture chapter closes with an “MLIR: operator” section that takes the chapter’s new operator, cuts the operations computing its backward out of the committed artifact of the chapter’s trained network, and names the theorem under which that text denotes a proven derivative. Those operators are dense layers, convolution, BatchNorm, the residual fan-in, depthwise convolution, squeeze-excitation, layer scale, and attention.
Every listing in those sections is an excerpt of a verified_mlir/ file at the shape that trained, with the artifact’s own SSA names, and a gate (scripts/book/book_listings.py) refuses any StableHLO in this book that is not, operation for operation, in the file it quotes. The book has no illustrative StableHLO. What is proven, what is tested and what is trusted on the way from a theorem to that text is set out in Appendix B: the denoted graph, the tie theorems, the printer, and the execution oracles.
1.6 What’s inside .train?
The section above treated linearVerified.toNet.trainLinear as a black box. You named the network, you named the epochs and the batch size, and training happened. That is deliberately the user-facing interface, but there is no magic underneath it. The driver is ordinary Lean in LeanMlir/Verified/Train.lean, and the interesting thing about it is how little it does.
The training loop, the way a math book would write it.
Algorithm: Mini-batch SGD, with the step compiled into the graph
Input:  net (a VerifiedNetSpec), cfg (epochs, batch size),
        dataset D = (X_train, y_train, X_test, y_test)
Output: trained parameters (W, b)

// 1. Open sessions over the two committed renders
ts  <- session(verified_mlir/<slug>_train_step.mlir)
fwd <- session(verified_mlir/<slug>_fwd.mlir)

// 2. Load data; zero-initialise the parameters
(X, y), (Xt, yt) <- load(D)
(W, b) <- 0

// 3. Epoch loop
for epoch = 1 to cfg.epochs:

    // 4. Batch loop: ONE call per batch
    for each mini-batch (x, t) of size B:
        (W, b) <- ts(x, W, b, onehot(t))

    // 5. Evaluate on the whole test set
    eval(fwd, W, b, Xt, yt)
The same loop, in Lean.
Here is VerifiedNet.trainLinear, the driver that produced the run at the top of this chapter. Three things are left out: the IO.getStdout flushes, two environment-variable overrides (LEAN_MLIR_PERTURB_R, which displaces the initialisation for a residency check, and LEAN_MLIR_MAX_EPOCHS, which caps the epoch count), and everything after the loop, which dumps the final parameters so the two lowerers can be diffed tensor by tensor. Two long lines are wrapped; every line that computes the answer is here:
def VerifiedNet.trainLinear (net : VerifiedNet) (cfg : VerifiedConfig)
    (dataDir : String) : IO Unit := do
  let bs := cfg.batchSize
  let d0 := net.d0
  let d1 := net.nClasses
  net.printBlurb
  -- 1. One session per committed render
  let tsSess  <- mkSession s!"{net.mlirDir}/{net.slug}_train_step.mlir"
  let fwdSess <- mkSession s!"{net.mlirDir}/{net.slug}_fwd.mlir"
  -- 2. Data, shapes, the entry point in each render, zero-initialised
  --    parameters
  let (trainImg, trainLbl, nTrain, evalImg, evalLbl, nEval, _trainPix, _crop) <-
    loadData net dataDir
  let evalName := match net.data with | .imagenette => "val" | _ => "test"
  IO.println s!"  train {nTrain}, {evalName} {nEval};
                  dense {d0}->{d1}, bs {bs}, SGD"
  let nb  := nTrain / bs
  let nbt := (nEval + bs - 1) / bs   -- ceil: last eval batch is zero-padded
  let shapes := net.shapesBA          -- packed [W0|b0] layout for the forward
  let xShape := net.xShape bs
  let tsFn  := s!"m.{net.slug}_train_step"
  let fwdFn := s!"m.{net.slug}_fwd"
  let mut W0 <- F32.const (d0 * d1).toUSize 0.0
  let mut b0 <- F32.const d1.toUSize 0.0
  let nResident : USize := 2          -- W0 and b0 stay on the device
  let pBytes := (d0 * d1 + d1) * 4
  let mut packed := W0 ++ b0
  -- 3. Epoch loop
  for ep in [0:cfg.epochs] do
    let tEp0 <- IO.monoMsNow
    -- 4. Batch loop: forward, loss, backward, SGD -- one call
    for bi in [0:nb] do
      let xb := F32.sliceImages trainImg (bi * bs) bs d0
      let yb := F32.sliceLabels trainLbl (bi * bs) bs
      let out <- LowererSession.linearTrainStepV tsSess tsFn
                  xb W0 b0 yb bs.toUSize d0.toUSize d1.toUSize nResident
      packed := out
      W0 := out.extract 0 (d0 * d1 * 4)
      b0 := out.extract (d0 * d1 * 4) pBytes
    -- 5. Evaluate on the full test set, every epoch
    packed <- LowererSession.readParams tsSess packed pBytes.toUSize
    W0 := packed.extract 0 (d0 * d1 * 4)
    b0 := packed.extract (d0 * d1 * 4) pBytes
    let params := packed
    let mut correct := 0
    for bi in [0:nbt] do
      let xb := F32.sliceImagesPad evalImg (bi * bs) bs d0 nEval
      let logits <- LowererSession.forwardF32 fwdSess fwdFn params shapes
                      xb xShape bs.toUSize d1.toUSize
                      nResident (ep + 1).toUSize
      for j in [0:min bs (nEval - bi * bs)] do   -- score real rows only, not the pad
        let pred := (F32.argmaxN logits (j * d1).toUSize d1.toUSize).toNat
        let lbl  := F32.readLabel evalLbl (bi * bs + j)
        if pred == lbl then correct := correct + 1
    let acc := correct.toFloat / nEval.toFloat * 100.0
    let epMs := (<- IO.monoMsNow) - tEp0
    IO.println s!"  epoch {ep + 1}: {evalName}_acc = {correct}/{nEval} = {acc}%
                    [95% CI {wilson95 correct nEval}] ({epMs}ms)"
Walking through the numbered sections:
1. Sessions. mkSession takes the path to a committed .mlir, hands it to the shim, and gets back something callable. XLA compiles the StableHLO in process, which is the 604 ms the run reported.
2. Data and initialisation. loadData mmaps the on-disk binaries into F32Array buffers. trainImg holds flattened pixels and trainLbl holds integer class labels. Weights start at zero rather than He-initialised, which is fine for a model with no hidden layer and no symmetry to break.
3. Epoch loop. Twelve passes over the training set. Notice what is not here: no learning-rate computation, because the rate is baked into the render.
4. Batch loop, the core of training. Slice a batch of images and labels, then call linearTrainStepV. That one call does everything: the forward pass, the cross-entropy loss, the backward pass built from the VJPs proved earlier in this chapter, and the SGD update. It returns the new parameters packed as [W0|b0].
This one line is where the whole pipeline pays off. There is no Python. There is no per-step graph construction. There is no autograd interpreter walking a tape. The training step was compiled once at startup, in 604 ms, and every batch after that is a single dispatched call. Chapter 1’s run does 468 of those per epoch and finishes an epoch in about 224 ms including a full pass over the 10,000 test images.
5. Validation. Every epoch, not every tenth, because a forward pass over the test set is cheap next to the training epoch. Two details are worth naming now because every later chapter inherits them. The eval loop reads the parameters back with readParams rather than using the W0/b0 it already has, because under device residency those two are stale by design and packed is the authoritative copy. And nbt rounds up: the last eval batch is zero-padded to bs and the inner loop scores only the real rows, so a test set whose size is not a multiple of the batch size is fully scored rather than silently truncated. Ten thousand images and a batch of 128 would otherwise drop the last 16. The forward-only render is a separate artifact rather than a branch inside the training graph, which matters more from Chapter 4 on.
That is the whole function. The reason it is short is that everything heavyweight lives in one compiled graph on the GPU. Lean’s job here is not to compute gradients. It is to specify what the training step is, prove that specification correct, and invoke it. Three concerns, cleanly separated, and only the middle one is unusual.
Every chapter after this one hands a different VerifiedNetSpec to the same driver. Only the spec changes. That is the framework pitch in concrete form: once the driver is written and the layers are proved one at a time, every architecture in the book runs through it with no further infrastructure code. It all runs on your hardware, and Getting started, at the front of the book, is the install.
1.7 MLIR: Training Step
Section 1.6 made a claim about the inner call. One dispatched StableHLO graph does the forward pass, the loss, the backward pass, and the optimizer update, with no tape and no per-step graph construction. The “MLIR: Linear” section above read the two gradient bands out of this file. Here is the whole thing the linear classifier compiles to. This is verified_mlir/linear_train_step.mlir as committed, with the default precision attributes dropped and the long type signatures wrapped for the page. Nothing else is removed, including one band that repeats:
func.func @linear_train_step(
    %x: tensor<128x784xf32>,  %W0: tensor<784x10xf32>,
    %b0: tensor<10xf32>,      %onehot: tensor<128x10xf32>)
    -> (tensor<784x10xf32>, tensor<10xf32>) {
  // -- forward + softmax-CE cotangent (rendered from lossCotGraph) --
  %v0 = stablehlo.dot_general %x, %W0, contracting_dims = [1] x [0]
          : (tensor<128x784xf32>, tensor<784x10xf32>) -> tensor<128x10xf32>
  %v1 = stablehlo.broadcast_in_dim %b0, dims = [1]
          : (tensor<10xf32>) -> tensor<128x10xf32>
  %v2 = stablehlo.add %v0, %v1 : tensor<128x10xf32>
  %v3 = stablehlo.exponential %v2 : tensor<128x10xf32>
  %v4 = stablehlo.constant dense<0.0> : tensor<f32>
  %v5 = stablehlo.reduce(%v3 init: %v4)
          applies stablehlo.add across dimensions = [1]
          : (tensor<128x10xf32>, tensor<f32>) -> tensor<128xf32>
  %v6 = stablehlo.broadcast_in_dim %v5, dims = [0]
          : (tensor<128xf32>) -> tensor<128x10xf32>
  %v7 = stablehlo.divide %v3, %v6 : tensor<128x10xf32>   // softmax
  %v8 = stablehlo.subtract %v7, %onehot : tensor<128x10xf32>   // dy
  // -- W0:  dW0 = x^T . dy,  then theta' = theta - lr*dW0 --
  %v9 = stablehlo.dot_general %x, %v8, contracting_dims = [0] x [0]
          : (tensor<128x784xf32>, tensor<128x10xf32>) -> tensor<784x10xf32>
  %v10 = stablehlo.constant dense<0.00078125> : tensor<784x10xf32>
  %v11 = stablehlo.multiply %v9, %v10 : tensor<784x10xf32>
  %v12 = stablehlo.subtract %W0, %v11 : tensor<784x10xf32>
  // -- v13-v21: v0-v8 emitted a SECOND time, verbatim --
  %v13 = stablehlo.dot_general %x, %W0, contracting_dims = [1] x [0]
          : (tensor<128x784xf32>, tensor<784x10xf32>) -> tensor<128x10xf32>
  %v14 = stablehlo.broadcast_in_dim %b0, dims = [1]
          : (tensor<10xf32>) -> tensor<128x10xf32>
  %v15 = stablehlo.add %v13, %v14 : tensor<128x10xf32>
  %v16 = stablehlo.exponential %v15 : tensor<128x10xf32>
  %v17 = stablehlo.constant dense<0.0> : tensor<f32>
  %v18 = stablehlo.reduce(%v16 init: %v17)
          applies stablehlo.add across dimensions = [1]
          : (tensor<128x10xf32>, tensor<f32>) -> tensor<128xf32>
  %v19 = stablehlo.broadcast_in_dim %v18, dims = [0]
          : (tensor<128xf32>) -> tensor<128x10xf32>
  %v20 = stablehlo.divide %v16, %v19 : tensor<128x10xf32>   // softmax again
  %v21 = stablehlo.subtract %v20, %onehot : tensor<128x10xf32>   // dy again
  // -- b0:  db0 = sum_batch dy,  then the same three-op update --
  %v22 = stablehlo.constant dense<0.0> : tensor<f32>
  %v23 = stablehlo.reduce(%v21 init: %v22)
          applies stablehlo.add across dimensions = [0]
          : (tensor<128x10xf32>, tensor<f32>) -> tensor<10xf32>
  %v24 = stablehlo.constant dense<0.00078125> : tensor<10xf32>
  %v25 = stablehlo.multiply %v23, %v24 : tensor<10xf32>
  %v26 = stablehlo.subtract %b0, %v25 : tensor<10xf32>
  return %v12, %v26 : tensor<784x10xf32>, tensor<10xf32>
}
One function, one straight line of dataflow, no control flow: the signature takes the parameters and a batch of data and returns the updated parameters, \((\theta ,\, \text{data}) \mapsto \theta '\). Read it in four bands. The first (%v0–%v8) fuses the forward pass and the loss cotangent, so it holds dot_general for the logits, the exp/reduce/divide softmax, and the subtract %onehot that yields \(dy = \partial \mathrm{CE}/\partial \text{logits}\). That whole band is the rendering of a single verified graph, lossCotGraph, certified equal to the softmax–cross-entropy gradient by lossCotGraph_isCEgrad. The second (%v9–%v12) is the weight half: dot_general %x, %v8 is exactly the move from the “MLIR: Linear” section, \(x^{\! \top } dy\), now serving as the weight gradient, and the three operations after it scale by the learning rate and subtract.
The third band (%v13–%v21) is the first band over again, operation for operation. The printer emits one cotangent chain per parameter rather than computing \(dy\) once and using it twice, so the forward pass and the softmax appear a second time before the fourth band (%v22–%v26) sums \(dy\) over the batch for the bias gradient and applies the same three-operation update. Whether the copy survives to the GPU is the compiler’s business — common-subexpression elimination is a standard pass — but the certified artifact contains both, and what this section shows is the artifact. Nothing is gained by pretending otherwise, and the duplication is a fair picture of what naive rendering costs: 27 operations where 19 would do.
There is no fifth band, no copy-back, and no separate update kernel. Forward, loss, backward, and step are one compiled function, which is exactly why § 1.6’s loop can treat a training step as a single dispatch.
Why SGD here. linearVerified trains with plain \(\theta ' = \theta - \alpha \nabla \) at a constant learning rate, which is three operations per tensor — the listing’s last band is the entire optimizer. Adam is available here and the deeper chapters use it, but it costs roughly 2.3 times the graph: Chapter 4’s CIFAR network, rendered both ways (verified_mlir/cifar8w_bn_{sgd,adam}_train_step.mlir), goes from 1,001 StableHLO operations under SGD to 2,293 under AdamW, because the first- and second-moment buffers enter and leave the signature and an rsqrt appears. Size is not the deciding reason, though. Both optimizers are proved faithful, each emitted update certified to be its own update law applied to the same proven gradient (Theorem 63). Only SGD also gets a descent theorem, that the step decreases the loss — and Adam cannot have one, because it is not monotone. That is a fact about Adam, the AMSGrad counterexample, and not a gap in the formalization. SGD is the optimizer here where both halves close, which is why it is the one to read first. Appendix B carries both certificates, and how far up the depth the descent half actually reaches.
The learning rate is folded in. The weight-gradient dot_general contracts the batch axis, so \(dW_0\) is a batch sum rather than a mean. The constant 0.00078125 is \(\alpha /N = 0.1/128\), the per-sample rate that turns that sum back into the mean update. Everything else in the listing is the rendering of a theorem proved earlier in this chapter: Theorem 23 certifies the two updates at every batch size, the batch sum and the \(\alpha /N\) scale included, so with \(\alpha /N = 0.1/128\) the emitted step is one step at rate \(0.1\) on the batch-mean loss.
That one function is the only heavy thing in the loop that drives it. Strip § 1.6’s driver of its logging and its session setup and it is the Foundations chapter’s five lines. The train_step call is the listing above; the eval is the forward render printed in “MLIR: Linear”, which is this listing’s first three operations; and the loop around them counts epochs and slices batches, nothing more.
Where this stands. The scheme above is the one every architecture in Part I trains under, and the book’s official claim is exactly this, no more and no less: every architecture in Part I trained end-to-end under one machine-checked scheme. What stays open is three things, stated once here and accounted for in Appendix B: the theorems are over \(\mathbb {R}\) while the GPU runs a finite precision, and § B.5 is the budget that sits between them; each operator’s printed text is trusted to compute what its graph node denotes, the per-op lexing the whole suite shares; and the compiler between the text and the card is trusted, not proved.
1.8 Recap
This chapter is the machinery, and every chapter after it is one layer dropped into it. The partial-derivative function \(\operatorname {pdiv}\) with its three rules, chain, sum and product, is the calculus; a \(\mathsf{HasVJP}\) record is a backward function bundled with the proof that it is the transpose of the Jacobian; and a trainer is four of those composed, forward, loss, backward, step, printed as one StableHLO function and run on the GPU as it was printed. For the one-layer classifier the chain closes as far as the scheme reaches: Theorem 23 says the emitted step is the certified gradient step on the batch-mean loss, at every batch size, and Theorem 25 says that under its small-step conditions one SGD step on the weights decreases one example’s loss.
What it leaves open is stated once here and carried through the book: the theorems are over \(\mathbb {R}\) while the card computes in a finite format, with §B.5 the budget between them, and each operator’s printed text is trusted to compute what its node denotes (Appendix B). The other limit is the network’s. A single dense layer is a linear map, and a linear map can only cut pixel space with flat boundaries, so the next chapter puts a non-linearity between two of them and applies the chain rule twice.