2 MNIST: 1D MLP
One layer learned; now stack them
Chapter 1 built the calculus, proved the dense layer’s backward pass, and trained it. A single dense layer is a linear map, and a linear map can only cut pixel space with flat boundaries. This chapter adds the two things a hidden layer needs: a non-linearity between the dense layers, ReLU, and the chain rule applied more than once. Every theorem here is the same question as before — if I jiggle this input by \(\varepsilon \), how does the output jiggle? — asked about ReLU, and then about the whole stack.
2.1 Run it first
Before any of the math, train the thing. Four commands and about twelve seconds of GPU time:
lake exe cache get                         # Mathlib oleans, ~30 s
./scripts/datasets/download_mnist.sh       # ~11 MB
lake build mnist-mlp-verified
./.lake/build/bin/mnist-mlp-verified data
On one RTX 4060 Ti (CUDA 12.9), from runs/2026-09-01-mlp-verified-xla-cuda/. XLA’s startup banner is removed and two long lines are wrapped:
[pjrt_ffi] XLA backend: PJRT 0.114, 1 device(s)
[pjrt_ffi] command buffers: enabled (CUDA default)
[pjrt_ffi] compiled verified_mlir/mlp_train_step.mlir
             (@mlp_train_step, 7 outputs, 1 replica) in 2123 ms
[pjrt_ffi] compiled verified_mlir/mlp_fwd.mlir
             (@mlp_fwd, 1 outputs, 1 replica) in 157 ms
MNIST-MLP via the VERIFIED renderer (784→512→512→10) → XLA/PJRT → GPU
  xla/pjrt verified_mlir/mlp_train_step.mlir
  xla/pjrt verified_mlir/mlp_fwd.mlir
  train 60000, test 10000; bs 128, MNIST-MLP (6 params, 669706 floats),
    mean-loss SGD lr=0.100000, He init
  epoch 1: loss = 0.413496, test_acc = 9199/10000 = 91.990000%  [95% CI 91.44–92.51] (870ms)
  epoch 2: loss = 0.191186, test_acc = 9526/10000 = 95.260000%  [95% CI 94.83–95.66] (879ms)
  epoch 3: loss = 0.139057, test_acc = 9636/10000 = 96.360000%  [95% CI 95.97–96.71] (888ms)
  epoch 4: loss = 0.109009, test_acc = 9690/10000 = 96.900000%  [95% CI 96.54–97.22] (842ms)
  epoch 5: loss = 0.088619, test_acc = 9716/10000 = 97.160000%  [95% CI 96.82–97.47] (847ms)
  epoch 6: loss = 0.073548, test_acc = 9732/10000 = 97.320000%  [95% CI 96.98–97.62] (864ms)
  epoch 7: loss = 0.061923, test_acc = 9746/10000 = 97.460000%  [95% CI 97.13–97.75] (802ms)
  epoch 8: loss = 0.052682, test_acc = 9762/10000 = 97.620000%  [95% CI 97.30–97.90] (818ms)
  epoch 9: loss = 0.045157, test_acc = 9767/10000 = 97.670000%  [95% CI 97.36–97.95] (841ms)
  epoch 10: loss = 0.038872, test_acc = 9771/10000 = 97.710000%  [95% CI 97.40–97.99] (831ms)
  epoch 11: loss = 0.033574, test_acc = 9778/10000 = 97.780000%  [95% CI 97.47–98.05] (847ms)
  epoch 12: loss = 0.029061, test_acc = 9781/10000 = 97.810000%  [95% CI 97.50–98.08] (850ms)
done (trained MNIST-MLP via the proof-rendered StableHLO).
Twelve epochs at about 850 ms each, and 97.81% on the full 10,000-image test set. Adding two hidden layers to the linear model of Chapter 1 buys 5.7 points of accuracy over its 92.10% (runs/2026-09-01-linear-verified-xla-cuda/) at 850 ms an epoch against its 224.
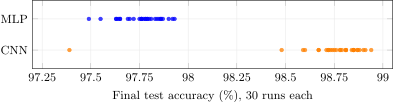
The linear model has no seed to spend — it starts at zero — so it has no spread to report. This one does. Run at five seeds it averages \(97.73\% \) with a spread of \(0.06\) either side, and every one of those five sits inside the interval printed above — which is \(\pm 0.29\) points on its own. Worth noticing once, because it holds for the rest of the book: changing the seed moves these numbers less than a single run can pin them down. The interval is the wider of the two, and it is the one to check a claimed improvement against.
ReLU: the piecewise case
ReLU is the function \(\mathrm{relu}(x) = \max (x, 0)\) applied coordinatewise. Its Jacobian is a diagonal matrix: each output coordinate depends only on the matching input coordinate. The diagonal entry is \(1\) where \(x_i {\gt} 0\) and \(0\) where \(x_i {\lt} 0\). At \(x_i = 0\) the function is not differentiable in the classical sense, because the slope jumps from \(0\) to \(1\). For our purposes this matters less than you might fear. Theorem 25 states the Jacobian at smooth points, and the codegen substitutes the standard subgradient convention at the kink and we move on. The kink is the only place in the chapter where “differentiable” becomes slightly subtle.
Composition
A three-layer MLP is \(\mathrm{dense}_2 \circ \mathrm{relu} \circ \mathrm{dense}_1 \circ \mathrm{relu} \circ \mathrm{dense}_0\). The VJP chain rule (Theorem 10) says the backward of a composition is the backwards run in reverse order, so the MLP’s backward is three dense backwards — each a multiplication by that layer’s \(W\) — with ReLU’s diagonal mask applied between them. That is the structural fact the rest of the book leans on: a network’s backward pass is its layers’ backward passes, composed.
There is one catch, and it is ReLU’s. Theorem 10 asks for both functions to be differentiable everywhere, and ReLU is not. So the whole-network result is stated at a point: wherever no pre-activation is exactly zero, the composed backward equals the \(\operatorname {pdiv}\)-contracted Jacobian (Theorem 28). The VJP record mlpHasVJP, with the \(\operatorname {pdiv}\)-derived backward (Definition 27), is the object later chapters name; the theorem is what makes naming it a claim.
2.2 The theorems
assume:
\(x\) is a smooth point of \(\mathrm{ReLU}\): every coordinate \(x_k \neq 0\) [h_smooth]
prove: for all \(i, j\):
where \([P]\) is the Iverson bracket (\(1\) if \(P\) holds, else \(0\)).
Sketch: near a smooth point, ReLU is a fixed linear map (each coordinate is committed to its branch of the \(\max \)); compute that map’s derivative and transport it.
Define \(\Lambda _x := \Pi _k\, (\text{if } x_k {\gt} 0 \text{ then } \mathrm{proj}_k \text{ else } 0)\), the diagonal indicator CLM (reluLinearPart).
Let \(r := \min _k |x_k|\). Then \(r {\gt} 0\), and \(\mathrm{ReLU}\) agrees with \(\Lambda _x\) on the ball \(B(x, r)\).
proof: \(r {\gt} 0\) by assumption 1. For \(y \in B(x, r)\) and every \(k\): \(|y_k - x_k| \le \lVert y - x \rVert {\lt} r \le |x_k|\), so \(y_k\) has the sign of \(x_k\); both functions then return \(y_k\) where \(x_k {\gt} 0\) and \(0\) where \(x_k {\lt} 0\).\(\mathrm{ReLU}\) has Fréchet derivative \(\Lambda _x\) at \(x\).
proof: A continuous linear map is its own derivative; by 2 the two functions agree on a neighborhood of \(x\), and HasFDerivAt.congr_of_eventuallyEq transports the derivative across that agreement.q.e.d.
proof: By Definition 1 and 3, \(\operatorname {pdiv}(\mathrm{ReLU})\, x\, i\, j = \Lambda _x(\mathbf{e}_i)_j = [x_j {\gt} 0] \cdot (\mathbf{e}_i)_j\); case split on \(i = j\) (when they coincide, \([x_j {\gt} 0] = [x_i {\gt} 0]\)) gives the goal.
The ReLU’s VJP record, with the \(\operatorname {pdiv}\)-derived backward: off the kink the cotangent is masked by \([x_j {\gt} 0]\); at the kink it is zero, as the emitted mask \([x {\gt} 0]\) is.
The MLP’s VJP record as one function, with the \(\operatorname {pdiv}\)-derived backward. The composed per-layer backward of Theorem 28 agrees with it at smooth inputs.
assume:
no coordinate of the first pre-activation \(\mathrm{dense}(W_0, b_0)\, x\) is zero [h_smooth_0]
no coordinate of the second pre-activation \(\mathrm{dense}(W_1, b_1)\bigl(\mathrm{relu}(\mathrm{dense}(W_0, b_0)\, x)\bigr)\) is zero [h_smooth_1]
prove: the backward composed from the five per-layer backwards in reverse order satisfies, for all \(dy\), \(i\):
Off the two conditions the composed backward is not defined; Definition 27 is the object that stands in.
Chain rule at a point, five times; see Proofs.mlpHasVJPAt_correct.
prove: mlp_train_step.mlir emits six update operations, the weights and biases of all three dense layers, and each denotes \(\theta - \alpha \, \partial L/\partial \theta \): the output layer’s against the gradient of the whole loss, the two hidden layers’ against the certified per-layer VJP at the chain cotangent, with the loss cotangent \(\mathrm{softmax}(z) - \mathrm{onehot}(\ell )\) pinned to its proven graph.
A fold over the six updates: each denotes its parameter minus \(\alpha \) times the dense gradient of Theorem 19 or 20 at the cotangent the chain hands it; see Proofs.MlpFold.mlp_train_step_tied_certified.
assume:
both hidden pre-activations are off the ReLU kink [h\(_0\), h\(_1\)]
\(L\) is any loss of the logits, with gradient \(g\) there [hL]
prove: for each of the six parameters, the gradient node at the chain cotangent of Theorem 29 is \(\partial L/\partial \theta \) of mlpForward with that one parameter varied. Instantiated at the softmax cross-entropy with the emitted loss cotangent.
Theorem 15 at each layer’s parameter Jacobian, the cotangent pulled back through the certified ReLU and dense backwards above it; see Proofs.MlpFold.mlp_net_lossGrad.
assume:
the pixels and the two upper weight matrices are bounded, \(|x_i| \le a\) and \(|W_k| \le w_k\) [hx, hW\(_1\), hW\(_2\)]
a margin at every ReLU of both hidden layers, so the step stays inside the smooth cell [hmargin0, hmargin1]
an \(\eta \)-accurate gradient oracle, and the small-step and dominance conditions of Theorem 24 [hgh, hsmall, h1, h2]
prove: one SGD step on the input layer’s weights decreases the cross-entropy loss:
The same holds at \(W_1\) and at the biases, and with the binary32 gradient in place of \(g\) for the weights, its \(\eta \) the rounding budget of § C.4.
As Theorem 24, with the ReLU masks fixed inside the margin cell: the logits move linearly in \(W_0\) through the masks, and the descent lemma runs with the margins supplying its Lipschitz constant; see Proofs.mlp_input_sgd_descends.
2.3 Example: MNIST MLP
The theorems above are the calculus. Here is a concrete architecture built from those pieces: a three-layer fully-connected classifier for 28\(\times \)28 MNIST digits.
Dataset overview
MNIST is the standard testbed for image-recognition learning. It’s a collection of 28\(\times \)28 grayscale images of handwritten digits 0–9: 60 000 training images and 10 000 test images, each with a label indicating which digit was drawn. The dataset has been around since 1998. At 784 pixels per image and 10 classes, MNIST is small enough that you can train a competitive model on a laptop CPU in minutes while still having a nontrivial learning problem.
Our goal in this chapter is to correctly classify a held-out test digit based on a model trained from the 60 000 training digits. We’re going to ignore the 2D spatial structure of the image entirely for now, so just flatten each 28\(\times \)28 image into a 784-dim vector and treat it as a plain supervised-learning classification problem. This is the multilayer perceptron (MLP). Chapter 3 revisits MNIST with convolutions that respect the spatial structure.
Architecture
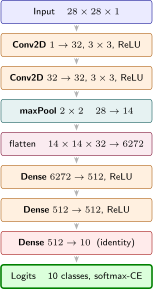
Three dense layers stacked with ReLU non-linearities between them: \(784 \to 512 \to 512 \to 10\). First layer ingests the flattened image. The two hidden layers let the network learn nonlinear features. The final layer maps to 10-dimensional logits, one per digit class.
The verified spec and program
The network above is a VerifiedNetSpec, the same object type Chapter 1 used for the linear model, now with two hidden layers and ReLU between them:
def mlpVerified : VerifiedNetSpec where
  name     := "MNIST-MLP"
  slug     := "mlp"
  inC      := 1
  imageH   := 28
  imageW   := 28
  data     := .mnist
  layers   := [.dense 784 512, .relu,
               .dense 512 512, .relu,
               .dense 512 10]
  blurb    := "MNIST-MLP via the VERIFIED renderer
                (784→512→512→10) → %LOWERER% → GPU"
  lossSlot := true
Five entries where Chapter 1 had one, and nothing else about the type changes. (layers and blurb are each one line in the source, wrapped here.) The slug binds the spec to verified_mlir/mlp_train_step.mlir and verified_mlir/mlp_fwd.mlir, and Proofs.StableHLO.mlpTrainStepText is what emits the train step. lossSlot is the field behind the loss column in §2.1’s transcript, which Chapter 1’s does not have: it tells the driver this render returns a trailing scalar to print. That scalar is also the one line of verified_mlir/mlp_train_step.mlir that is not pretty of a proven graph node, and the render says so itself, in a comment of its own: %loss below is REPORT-ONLY (logging), NOT pretty(AST node). Nothing reads it but the printer and no theorem depends on it. The six parameter outputs are the proved ones — MlpFold shows each denotes the certified gradient-descent step derived from the Mathlib \(\operatorname {fderiv}\) math.
What .relu contributes.
Nothing:
| relu => #[]
ReLU carries no parameters, so its toSpecs arm is the empty array and the five-entry layers list above still yields six tensors — three weight matrices and three biases, the 6 params, 669706 floats the run reported. A layer with no state is still a layer: it holds a position in the list because the render needs it in order, not because the optimizer does.
The tie back to the proofs has the same shape as before, now at a point, because ReLU has a kink. In LeanMlir/Proofs/SpecVJP.lean:
noncomputable def mlpVerifiedHasVJPAt (W0 b0 W1 b1 W2 b2) (x)
    (h0 : ∀ k, dense W0 b0 x k ≠ 0)
    (h1 : ∀ k, dense W1 b1 (relu 512 (dense W0 b0 x)) k ≠ 0) :
    HasVJPAt (denoteMLP mlpVerified.layers W0 b0 W1 b1 W2 b2) x := ...
Again the backward — the five per-layer backwards composed, at an input where neither ReLU sits on its kink — is proved for the denotation of the spec’s own layers field, and that is the field the trainer reads to build its graph. The whole program is short enough to print:
import LeanMlir.Verified.NetsCore
import LeanMlir.Verified.Train

def mlpConfig : VerifiedConfig where
  epochs    := 12
  batchSize := 128

def main (argv : List String) : IO Unit :=
  mlpVerified.toNet.train mlpConfig (argv.head?.getD "data")
That is apps/mnist/MainMnistMlpVerified.lean. The only difference from Chapter 1’s driver is .train in place of .trainLinear, because the MLP carries six parameter tensors packed together rather than a separate W0 and b0.
The two compile lines in §2.1 are where that shows up: the train step compiles in 2,123 ms against the linear step’s 604 (its transcript in Chapter 1, from runs/2026-09-01-linear-verified-xla-cuda/), which is the cost of six parameter tensors and two ReLU subgradients rather than one dense layer.
Results
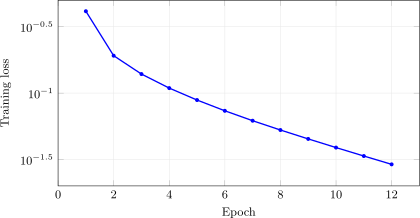
The run in §2.1 is the result. Its per-epoch training loss, on a log scale:
MNIST MLP (\(784{\to }512{\to }512{\to }10\)), SGD 0.1, 12 epochs, log-scale mean training loss per epoch (runs/2026-09-01-mlp-verified-xla-cuda/). The loss falls \(14\times \) across the run, and test accuracy ends at 97.81%.
Both numbers come off the same binary this chapter’s theorems describe.
2.4 Return on width
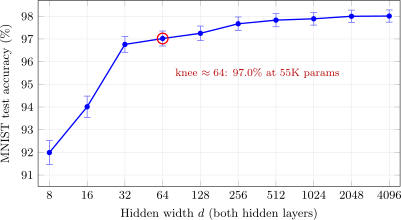
The \(512{\to }512\) hidden size is a convention, not a measurement. The verified renderer is parametric in the layer dimensions and mlpHasVJP is polymorphic in \(d_0,d_1,d_2,d_3\), so one theorem covers every width and we can sweep the hidden size, training each point on its own proof-rendered StableHLO. The mnist-mlp-grid driver does exactly this: it renders \(784{\to }d{\to }d{\to }10\) from the faithful emitter and trains it end to end. Sweeping \(d\) over the powers of two from 8 to 4096 (each 12-epoch SGD, on the GPU) gives the accuracy-vs-width curve below.
Return on width for the verified MNIST MLP (\(784{\to }d{\to }d{\to }10\)): test accuracy versus hidden width \(d\) (log scale), 12-epoch SGD on the proof-rendered StableHLO (runs/mlp_grid_results_xla.tsv). Bars are the 95% Wilson interval on 10,000 test images — the same interval the transcripts print, and about \(\pm 0.3\) points once accuracy is in the nineties.
The curve flattens hard after \(\sim \)64 neurons: widening \(8{\to }64\) buys \(+5.0\) points, but \(64{\to }4096\), at \(64\times \) the width and \(364\times \) the parameters, buys only \(+1.0\). A \(32{\to }32\) MLP already reaches 96.8% at 27K parameters, \(755\times \) smaller than the \(4096{\to }4096\) net (98.0%).
The bars are what make that plateau concrete rather than merely visible. Every point from \(d = 256\) rightward has an interval overlapping every other, so a \(16\times \) increase in width and \(74\times \) in parameters buys nothing this test set can resolve. The climb up to the knee is real — \(d = 64\) and \(d = 4096\) do not overlap — and the plateau past it is not. The canonical \(512{\to }512\) sits comfortably on that plateau, and anything past it is paying for the third decimal place.
Off the diagonal the story is capacity rather than failure. A \(784{\to }8{\to }4096{\to }10\) net averages 93.70% over five seeds, with a spread of \(0.56\) — about a point and a half above what the \(8{\to }8\) net manages on its own (92.0%). The 8-unit layer is a bottleneck, and width behind it cannot recover signal that the narrow layer already discarded.
That point is also the one place in this sweep where three runs would have been misleading, which is worth seeing once. The first three seeds land between 93.14 and 93.70%, a tight and plausible-looking range; the fourth comes in at 94.53%, most of a point above the top of it. Three observations of a quantity with this much spread will happily agree with each other and still be wrong about where the next one falls. The diagonal points plotted above are one run each, and are best read with half a point of give.
2.5 MLIR: Dense
What is already proven. mlpForward is the three-dense-layer network, and mlpHasVJPAt proves its reverse-mode derivative (the vector–Jacobian product) by chaining the per-layer chain rule vjpCompAt (Theorem 28). The parameter gradients are pinned by denseWeightGrad_correct and denseBiasGrad_correct, and the loss gradient by softmaxCE_grad. So what the gradient is, is not in question.
The gap and how we close it. The emitted backward is a value of a Lean datatype, Back, with a denotation \([\! [\cdot ]\! ]\) into the proofs’ own vector type. For the MLP the graph is
rooted at the incoming cotangent, with \([\! [\texttt{dotGeneral}\, W]\! ] = \texttt{Mat.mulVec}\, W\) and \([\! [\texttt{selectPos}\, p]\! ] = (v \mapsto \text{if } p{\gt}0 \text{ then } v \text{ else } 0)\), and the bridge theorem
says the denotation of that graph is the proven derivative. The forward, the loss cotangent, and the parameter gradients are covered the same way.
Here is what IRPrint.lean prints for that graph, one stablehlo op per node (default precision attributes elided for the page). Back carries real-valued operands and cannot be printed directly, so the printer walks a mirror of it, Hlo, built node for node from emitMlpBack’s shape with SSA names in place of values; that the mirror matches is checked by reading the two definitions side by side, not by a theorem:
func.func @mlp_back(%dy: tensor<2x2xf32>, %W0: tensor<4x3xf32>,
    %W1: tensor<3x3xf32>, %W2: tensor<3x2xf32>,
    %p0: tensor<2x3xf32>, %p1: tensor<2x3xf32>) -> tensor<2x4xf32> {
  %bk0 = stablehlo.dot_general %dy, %W2, contracting_dims = [1] x [1]
           : (tensor<2x2xf32>, tensor<3x2xf32>) -> tensor<2x3xf32>
  %bk1 = stablehlo.constant dense<0.0> : tensor<2x3xf32>
  %bk2 = stablehlo.compare GT, %p1, %bk1
           : (tensor<2x3xf32>, tensor<2x3xf32>) -> tensor<2x3xi1>
  %bk3 = stablehlo.select %bk2, %bk0, %bk1
           : tensor<2x3xi1>, tensor<2x3xf32>
  %bk4 = stablehlo.dot_general %bk3, %W1, contracting_dims = [1] x [1]
           : (tensor<2x3xf32>, tensor<3x3xf32>) -> tensor<2x3xf32>
  %bk5 = stablehlo.constant dense<0.0> : tensor<2x3xf32>
  %bk6 = stablehlo.compare GT, %p0, %bk5
           : (tensor<2x3xf32>, tensor<2x3xf32>) -> tensor<2x3xi1>
  %bk7 = stablehlo.select %bk6, %bk4, %bk5
           : tensor<2x3xi1>, tensor<2x3xf32>
  %bk8 = stablehlo.dot_general %bk7, %W0, contracting_dims = [1] x [1]
           : (tensor<2x3xf32>, tensor<4x3xf32>) -> tensor<2x4xf32>
  return %bk8 : tensor<2x4xf32>
}
Read it against the graph: each dot_general (%bk0, %bk4, %bk8) is a dotGeneral \(W\) node, whose denotation is \(\texttt{Mat.mulVec}\, W\). Each compare GT + select pair (%bk2/%bk3, %bk6/%bk7) is a selectPos \(p\) node, which is the ReLU subgradient. The bridge theorem is precisely the claim that this text computes mlpHasVJPAt’s backward.
Caveats.
ReLU is a smooth-point bridge. Where a pre-activation is exactly zero ReLU has no derivative. The emitted compare GT 0 sends that case to \(0\), and the bridge is permitted to fail on that measure-zero set.
Representative scale. Shown small. The trained net is \(784{\to }512{\to }512{\to }10\).
Trusted surface. The printer’s faithfulness and the lowerer’s translation are tested rather than proved. Rounding \(\approx \mathbb {R}\) is not on this list: it is a theorem layer over an arbitrary rounding model (§ C.4), conditional on two measured constants rather than assumed outright. Appendix C.2.1 has the full accounting.