12 Beyond recognition
The training signal stops being a label. It is the next token, the noise added to an image, a density, a chirp buried in detector noise, an energy, the distance between two residues of a protein — and where the field has an exact answer, quadrature, the matched filter’s closed form, a solved spin chain, or a blind competition’s table, the demo is scored against it rather than against a held-out set. The networks are the same kit; what changes is the outer loop, and the catalogue beside each demo is that domain’s architectures. The games, whose signal is a reward and whose answers are theorems about the rules, are Chapter 13.
12.1 Natural language processing — demo: TinyGPT on Shakespeare
The architectures here all consume a sequence of token IDs and emit either a sequence of next-token logits (decoder-only: GPT) or a single classification head (encoder-only: BERT). At the layer level they reduce to one of three shapes: a stack of .transformerEncoder (with or without a causal mask), a state-space stack (.mambaBlock), or a conv/attention hybrid (.separableConv plus .transformerEncoder, QANet). What’s different from the vision side of the bestiary isn’t the layer kit — the kit is the same set of primitives Ch 9 introduced — it’s everything around the layers: the data pipeline, the loss, and the inference loop.
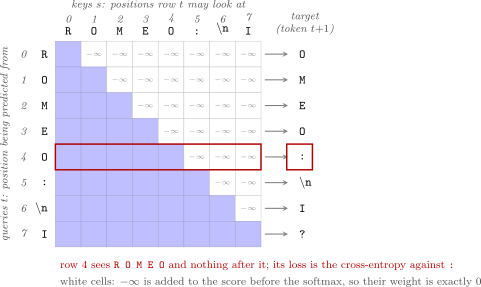
TinyGPT, in passing.
The demos/MainTinyGptShakespeare.lean trainer in this repo is a working char-level transformer at 212K params (\(T{=}64\), \(D{=}64\), 4 layers, 2 heads). Ten thousand Adam steps take three minutes on one RTX 4060 Ti through XLA, compile included, and land at 2.28 bits/char on tinyshakespeare’s held-out split — against 3.56 for a bigram table and 6.02 for guessing uniformly over the 65 characters. Sampling after that produces recognizable Shakespeare cadence, real character names (NORTHUMBERLAND, QUEEN MARGARET, MERCUTIO, BRUTUS) and multi-line dialog. Three things change relative to the image trainers shown throughout Part 1, and they capture what NLP training is:
Input is a vocabulary index, not a pixel. The first layer of every NLP spec is .tokenPositionEmbed (one-hot \(\to \) learnable token embedding \(+\) learnable position embedding). Image stacks open with .conv2d or .patchEmbed acting on \(H \times W \times 3\) floats; the NLP stack starts with vocabulary IDs flowing through a lookup table. Replace patches with tokens and the rest of a ViT is shape-identical to a GPT.
Loss is per-token, averaged over the sequence. Image classifiers compute one cross-entropy at the end of the network: pool to a vector, dense to logits, compare to one ground-truth class. Language models compute cross-entropy at every position — each of the \(T\) tokens predicts the next one, and the per-token losses are averaged. Our trainer reuses the same cross-entropy path through a flag (useSeg in TrainConfig) that switches the loss from “one vector versus one class” to “\(T\) vectors versus \(T\) classes.” No new VJP machinery; the per-token softmax-CE backward is the same one Ch 1 derived, applied \(T\) times in parallel.
Inference is autoregressive. The training loop is a single forward pass per batch, just like image classification, but inference is a \(T\)-step loop: the network predicts token \(t{+}1\) from tokens \([0..t]\), the sampled token is appended to the context, and the network runs again for \(t{+}2\). Our tinygpt-shakespeare sample executable implements exactly this loop — \(\sim \)30 lines of plain Lean, no proof machinery, running the same spec’s forward graph at batch one through XLA on the parameters the trainer saved. The architectural cost is the causal mask (Figure 12-1): during training, attention at position \(t\) must not see positions \(t{+}1\) onward, or the model would trivially predict the answer it can see. We expose this via the causalMask flag on .transformerEncoder; the rest of the kit is shared with ViT.
That’s the entire delta. Same Adam optimizer, same VJP machinery, same StableHLO-through-XLA pipeline. The bestiary entries below all reduce to either “GPT shape” (decoder-only, causal mask, autoregressive sampling) or “BERT shape” (encoder-only, bidirectional attention, classification head); the architectural differences between them are smaller than the chapter-to-chapter deltas in Part 1.
Mamba (Bestiary/Mamba.lean)
One new primitive (§ 167). Variants: Mamba-130M / 370M / 790M / tiny, matching Gu & Dao’s (2023, arXiv:2312.00752) param counts within \(\sim \)5%.
def mamba130M : NetSpec where
  name   := "Mamba-130M"
  imageH := 2048                                  -- context length (L tokens)
  imageW := 1
  layers := [
    -- dim=768, state=16, expand=2, 24 blocks
    .mambaBlock 768 16 2 24,
    .dense 768 50280 .identity                    -- LM head (GPT-NeoX vocab)
  ]
BERT / RoBERTa (Bestiary/BERT.lean)
Zero new primitives — uses .transformerEncoder, same kit as ViT / DETR, plus .dense vocab\(\to \)dim standing in for the token-embedding table (faithful param count, shape semantics cheat since a linear NetSpec can’t express the \(L \to L \times D\) lookup). Variants: BERT-base (109M, paper 110M), BERT-large (335M, paper 340M), RoBERTa-base (124M, paper 125M), RoBERTa-large (355M, paper-exact), tinyBERT fixture. The architectural lesson is that RoBERTa (Liu et al. 2019, arXiv:1907.11692) = BERT (Devlin et al. 2018, arXiv:1810.04805); all RoBERTa gains came from training procedure (dynamic masking, more data, bigger batches, dropped NSP) — none of which lives in the NetSpec.
def bertBase : NetSpec where
  name   := "BERT-base"
  imageH := 512                                   -- max context length
  imageW := 1
  layers := [
    -- Token-embedding lookup approximated as dense (vocab → D)
    .dense 30522 768 .identity,
    -- 12 encoder blocks, post-norm, GELU, mlpDim = 4·D
    .transformerEncoder 768 12 3072 12,
    -- [CLS] pooler (tanh applied downstream)
    .dense 768 768 .identity
  ]
GPT-1 / GPT-2 (Bestiary/GPT.lean)
Zero new primitives. GPT-1 (Radford et al. 2018, OpenAI TR) and GPT-2 (Radford et al. 2019, OpenAI TR) are decoder-only counterparts of BERT. Same .transformerEncoder, now read as a stack of decoder blocks with a causal attention mask (a training-time detail, not a parameter). No pooler; GPT-2 uses pre-norm instead of BERT’s post-norm (zero-parameter swap). Weight tying: the LM head reuses the token-embedding matrix, so our .dense vocab\(\to \)D stand-in already pays for both input and output sides. Variants: GPT-1 (116M, paper 117M), GPT-2 small (123M, paper 124M), medium (353M), large (772M, paper 774M), XL (1.56B, paper 1.5B), tinyGPT fixture. Reference implementation: Karpathy’s nanoGPT (\(\sim \)300 lines of PyTorch) targets GPT-2 small and is the canonical mental model.
def gpt2Small : NetSpec where
  name   := "GPT-2 small"                         -- the nanoGPT target
  imageH := 1024                                  -- context length
  imageW := 1
  layers := [
    -- Tied token embedding (also serves as LM head projection)
    .dense 50257 768 .identity,
    -- 12 decoder blocks, pre-norm (mask is attention-time, not a param)
    .transformerEncoder 768 12 3072 12 (causalMask := true)
  ]
QANet (Bestiary/QANet.lean)
One new primitive (.separableConv). The 2018 reading-comprehension architecture that killed the BiLSTM for SQuAD-style tasks (Yu et al. 2018, arXiv:1804.09541). Core contribution: an encoder block combining 4 depthwise- separable convs (local context) with a self-attention + FFN transformer block (global context) — the “conv + attention hybrid” shape MobileViT and ConvNeXt rediscovered in 2022. Expressed with primitives we already have: 4 .separableConv 128 128 1 calls + 1 .transformerEncoder 128 8 512 1 per block. Per-block count: \(\sim \)270K for the embedding-encoder block; the model-encoder blocks carry two separable convs rather than four, and the paper’s seven-block stack lands at \(\sim \)1.6M, repeated 3 times in the full architecture. The BiDAF- style context-query attention and character/word embedding tables are omitted from the spec; described in prose. QANet’s headline number was 3–4\(\times \) training speedup over BiLSTM-based competitors, a clean example of hardware (parallelization of convs vs. sequential RNN roll-outs) forcing an architectural choice. BERT landing 7 months later ended the SQuAD-as-benchmark era, but QANet’s hybrid shape lived on — showed up repeatedly in vision 4 years later.
def qanetEncoderBlock : NetSpec where
  name   := "QANet encoder block (4× sep-conv + self-attn + FFN)"
  imageH := 400                                   -- representative context length
  imageW := 1
  layers := [
    -- 4 depthwise-separable convs (local context, kernel 7 in paper)
    .separableConv 128 128 1,
    .separableConv 128 128 1,
    .separableConv 128 128 1,
    .separableConv 128 128 1,
    -- Self-attention + FFN + 2 LayerNorms (global context)
    .transformerEncoder 128 8 512 1
  ]
Nyströmformer (Bestiary/Nystromformer.lean)
Zero new primitives. An efficient-attention transformer (Xiong et al. 2021, arXiv:2102.03902) that replaces the \(O(n^2)\) softmax attention with an \(O(n)\) Nyström-approximation computed via \(m\) landmark tokens, \(m \ll n\). Crucially, this is a compute change, not a parameter change: the \(W_Q / W_K / W_V / W_O\) projections and the FFN are identical to a standard transformer. Our .transformerEncoder spec is therefore identical to BERT’s at each scale — base lands at 108M (vs BERT-base 109M), large at 333M (vs BERT-large 335M). The entry’s pedagogical value is prose-level: most of the 2020–2022 efficient-attention literature (Linformer, Performer, Longformer, BigBird, Reformer, FlashAttention) is parameter-identical to vanilla attention, and the bestiary can’t differentiate them at the layer level. Nyströmformer is worth highlighting because the specific trick — a 1930 result from numerical linear algebra, routed through kernel-method literature in the early 2000s, finally surfacing in transformers — is a genuinely long arc for one math idea.
def nystromformerBase : NetSpec where
  name   := "Nyströmformer base (BERT-base-shaped, O(n) attention)"
  imageH := 4096                                  -- long context
  imageW := 1
  layers := [
    -- Architecturally identical to BERT-base; Nyström approximation
    -- lives inside the attention kernel, not the NetSpec.
    .dense 30522 768 .identity,
    .transformerEncoder 768 12 3072 12
  ]
12.2 Image generation
Networks whose output is a novel image. Two families covered here: variational autoencoders and GANs. Backbones overlap heavily with segmentation (UNet again). Diffusion models, also generative, are the subsection after this one.
VAE (Bestiary/VAE.lean)
One new primitive (§ 164). The classical variational autoencoder (Kingma & Welling 2013, arXiv:1312.6114): encoder outputs \((\mu , \log \sigma ^2)\) (represented as a single tensor with doubled final width), the reparameterization trick \(z = \mu + \sigma \odot \epsilon \) samples \(z\) in training code, the decoder reconstructs. KL divergence between the learned latent distribution and a standard normal is the regularizer. Variants: MNIST MLP VAE (20-dim latent, textbook example), CIFAR conv VAE (\(4 \times 4 \times 4\) spatial latent, SD-style), tiny fixture. All shown as encoder + decoder pairs. Training-code details (the actual sampling step, the KL loss) live outside the NetSpec. The same architectural template scales up to Stable Diffusion’s VAE (see StableDiffusion.lean); 2013’s 20-dim MNIST latent and 2022’s \(64 \times 64 \times 4\) SD latent are the same idea at different scales. VQ-VAE (discrete-codebook variant) and \(\beta \)-VAE (scaled KL) are mentioned in the prose notes.
def mnistVAEEncoder : NetSpec where
  name   := "MNIST VAE encoder (MLP, 20-dim latent)"
  imageH := 28
  imageW := 28
  layers := [
    .flatten,
    .dense 784 400 .relu,
    -- Output is 2×20 = 40: first 20 are μ, last 20 are log σ².
    .dense 400 40 .identity
  ]
DCGAN (Bestiary/DCGAN.lean)
Zero new primitives. Deep Convolutional GAN (Radford et al. 2015, arXiv:1511.06434) — the paper that made GAN training reliably work. Eight design guidelines (strided convs instead of pooling, BN everywhere except \(G\)’s output / \(D\)’s input, no hidden FC layers, ReLU in \(G\) / LeakyReLU in \(D\), Adam with specific hyperparams) that became the default for every GAN paper since. Three NetSpecs: noise projector (dense \(100 \to 4 \times 4 \times 1024\), 1.65M), generator convs (11M, paper \(\sim \)12M), discriminator (11M, paper-exact). Transposed convs in \(G\) are approximated by standard convs of matching kernel and channels (same params, spatial doubling is forward-pass-only); same hack appears in VAE and Stable Diffusion entries. GAN training dynamics (mode collapse, equilibrium stability) are all training-procedure concerns living outside the NetSpec.
def dcganGenerator : NetSpec where
  name   := "DCGAN generator (64×64 RGB)"
  imageH := 4                                     -- starting spatial (post-projection)
  imageW := 4
  layers := [
    -- Each .convBn stands in for a 4×4 transposed conv doubling spatial;
    -- same params (ic × oc × k²), upsampling is a forward-pass detail.
    .convBn 1024 512 4 1 .same,                  --  4×4 →  8×8
    .convBn 512  256 4 1 .same,                  --  8×8 → 16×16
    .convBn 256  128 4 1 .same,                  -- 16×16 → 32×32
    .convBn 128   64 4 1 .same,                  -- 32×32 → 64×64
    .conv2d   64   3 4 .same .identity           -- RGB output (tanh in real)
  ]
Pix2Pix (Bestiary/Pix2Pix.lean)
Two new primitives (§ 163, § 164). The paired-data ancestor of CycleGAN, from the same lab 9 months earlier (Isola et al. 2017, arXiv:1611.07004). UNet generator (8 levels, \(\sim \)62M vs paper \(\sim \)54M — our .unetDown / .unetUp use 2 convs per level where Pix2Pix uses 1 strided conv, so we overcount) + PatchGAN discriminator (identical to CycleGAN’s, 2.8M). Trained with GAN loss + L1 reconstruction — the L1 term is a direct supervision signal that exists only because pairs exist. When you don’t have pairs you fall back to CycleGAN’s cycle-consistency trick. Hardware context: 2016–2017, 54M UNet on \(256 \times 256\) images meant batch size 1 on a GTX 1080 Ti, which is how InstanceNorm became the default normalizer in this lineage — it was what fit.
def pix2pixGenerator : NetSpec where
  name   := "Pix2Pix generator (8-level UNet, 256×256 RGB)"
  imageH := 256
  imageW := 256
  layers := [
    -- Encoder: 8 × unetDown, channels 64 → 128 → 256 → 512 → 512 ×4
    .unetDown 3    64, .unetDown 64  128,
    .unetDown 128 256, .unetDown 256 512,
    .unetDown 512 512, .unetDown 512 512,
    .unetDown 512 512, .unetDown 512 512,         -- bottleneck at 1×1×512
    -- Decoder: 8 × unetUp mirroring the encoder
    .unetUp 512 512, .unetUp 512 512,
    .unetUp 512 512, .unetUp 512 512,
    .unetUp 512 512, .unetUp 512 256,
    .unetUp 256 128, .unetUp 128  64,
    .conv2d 64 3 1 .same .identity                -- 1×1 to RGB (tanh in real)
  ]
CycleGAN (Bestiary/CycleGAN.lean)
Zero new primitives. Unpaired image translation (Zhu et al. 2017, arXiv:1703.10593): two generators \(G : X \to Y\) and \(F : Y \to X\) plus two PatchGAN discriminators, trained with adversarial loss + cycle consistency loss \(\| F(G(x)) - x\| _1\). The cycle constraint is what makes unpaired training work — without it, \(G\) could mode-collapse every \(x\) to one target. Generator is a Johnson-style ResNet (Johnson et al. 2016, arXiv:1603.08155): convs down + 9 .residualBlocks at 256 channels + convs up (11.4M, paper \(\sim \)11M). Discriminator is a PatchGAN: 5 strided convs with a \(70 \times 70\) receptive field, outputs an \(N \times N\) grid of patch real/fake logits (2.8M, paper \(\sim \)2.8M). Four-network pattern shown as two specs (\(G\) and \(D\)); the other \(F\) and \(D_X\) are architecturally identical copies. The “one clever loss” does the work — the architecture is quite ordinary.
def cycleganGenerator : NetSpec where
  name   := "CycleGAN generator (9-block ResNet, 256×256 RGB)"
  imageH := 256
  imageW := 256
  layers := [
    .convBn 3 64 7 1 .same,                       -- 7×7 stem
    .convBn 64  128 3 2 .same,                    -- 256 → 128
    .convBn 128 256 3 2 .same,                    -- 128 →  64
    .residualBlock 256 256 9 1,                   -- 9 res blocks (bottleneck)
    .convBn 256 128 3 1 .same,                    -- upsample stand-in
    .convBn 128  64 3 1 .same,
    .conv2d 64 3 7 .same .identity                -- 7×7 to RGB
  ]
12.3 Diffusion — demo: DDPM on MNIST
Generative models that predict the noise added to a clean image, with inference iterating the reverse (noise in, image out). The architecture is a UNet — often with cross-attention bolted in for text conditioning. The novelty lives in the noise schedule and the sampling loop, not in layer design.
DDPM on MNIST.
The demos/MainMnistDdpmTrain.lean trainer (its CIFAR-10, sinusoidal-time and attention variants are archived beside it) is a timestep-conditioned UNet trained to predict the Gaussian noise added to an image; mnist-ddpm-sample runs the reverse loop and writes a grid. The backbone is literally the segmentation UNet of § 11.7. Three things change relative to the classifiers, segmentation nets and detectors so far:
The target is the noise, and it is self-supervised. Every model so far compares against something a human provided — a class, a mask, a set of boxes. Diffusion manufactures its own: sample a timestep \(t\), sample noise \(\varepsilon \), add it per the schedule, predict \(\varepsilon \), under the same squared-error backward from Part 1 (the demo compiles its own train step, with useDdpm := true).
The backbone is the segmentation UNet, conditioned on \(t\). One network must denoise at every level, so \(t\) is fed in: this demo concatenates it as an extra channel (hence .unetDown 2 16 — one image channel plus one time channel), and the archived CIFAR variant embeds it with the positional-encoding primitive NeRF introduced. Diffusion adds only the conditioning.
Inference is an iterative loop, not one forward pass. What that loop costs is Table 12-2.
Scoring it needs an instrument, not an eye.
Unconditional image generation is the only demo in this book whose success criterion is “does that look like a digit to you.” It does not have to be: Chapter 3’s verified CNN maps an image to ten numbers, and in that space the usual statistics work. What matters more than any row is that the scale is bracketed at both ends, since a metric that only ever reports “bad” is indistinguishable from a broken one. Table 12-1 is the bracket.
|
coverage |
confidence |
energy (\(\times \) floor) |
pixel mean |
|
|
real MNIST, scored as if generated |
10/10 |
\(99.40\% \) |
\(0.0020\) (\(1\times \)) |
\(0.122\) |
|
the model, ancestral sampling |
10/10 |
\(92.98\% \) |
\(0.0067\) (\(4\times \)) |
\(0.118\) |
|
the model, deterministic DDIM |
10/10 |
\(90.94\% \) |
\(0.0237\) (\(15\times \)) |
\(0.138\) |
|
unstructured pixels |
4/10 |
\(58.47\% \) |
\(0.3674\) (\(231\times \)) |
\(0.132\) |
The instrument scores \(98.66\% \) on the real split, which is the check that its weights loaded. A checkpoint that writes pixels outside \([0,1]\) fails the bracket before anyone looks at a grid. \(\triangleright \) And read the confidence column against the others: noise still posts \(58\% \), so the usable range is \(58\)–\(99\) rather than \(0\)–\(100\), and on its own it is the metric most likely to mislead.
The continuous-time view, and which solver to use.
Everything above is discrete: a schedule tabulated at \(t = 0 \dots T{-}1\) and a fixed reverse recipe. Score-SDE (Song et al. 2021, arXiv:2011.13456) reads the same object as a stochastic differential equation in continuous time, \(\mathrm{d}x = f(x,t)\, \mathrm{d}t + g(t)\, \mathrm{d}w\), whose reverse is driven by the score \(\nabla _x \log p_t(x)\). That view costs no retraining here, which is the point worth taking away: under the variance-preserving SDE the score is \(-\hat\varepsilon (x,t)/\sigma _t\), so the \(\varepsilon \)-predicting network the trainer above already produces is a score model up to a scale factor. Sampling is then whatever you choose to integrate, on frozen weights: the reverse SDE, its deterministic twin the probability-flow ODE, or the family between them that DDIM’s \(\eta \) (Song, Meng & Ermon 2020, arXiv:2010.02502) interpolates.
So it can be measured. Energy distance against real MNIST, budget in network evaluations:
|
sampler |
NFE \(10\) |
NFE \(20\) |
NFE \(50\) |
NFE \(200\) |
|
DDIM, \(\eta = 0\) (deterministic) |
\(0.0874\) |
\(0.0437\) |
\(0.0237\) |
\(0.0188\) |
|
DDIM, \(\eta = 1\) (ancestral) |
\(\mathbf{0.0455}\) |
\(\mathbf{0.0132}\) |
\(\mathbf{0.0067}\) |
\(\mathbf{0.0099}\) |
|
reverse SDE (Euler–Maruyama) |
\(1.1837\) |
\(0.9870\) |
\(0.3382\) |
\(0.0211\) |
|
probability-flow ODE (Euler) |
\(0.3542\) |
\(0.2053\) |
\(0.0910\) |
\(0.0288\) |
Noise in the reverse process helps, and the effect is monotone in \(\eta \) at every budget — the two intermediate arms, \(\eta = 0.25\) and \(\eta = 0.5\), sit in order between the first two rows. Ancestral sampling at \(50\) evaluations beats the deterministic sampler at \(200\) by nearly \(3\times \), on a quarter of the compute. Figure 12-2 is the process itself, forward and reverse.
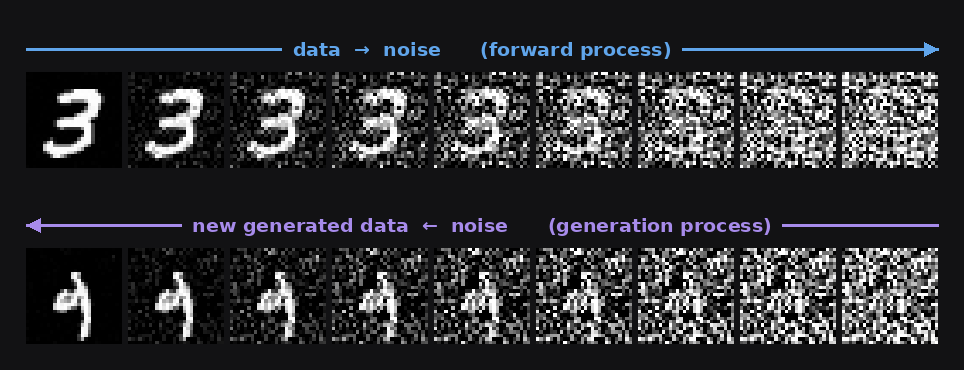
Which makes the third row the instructive one. The reverse SDE and ancestral sampling are the same idea — integrate the stochastic reverse process — and they land at opposite ends of this table, because one of them discretises it well and the other does not. The reverse process is stiff, \(\beta (t)\) diverging as \(t \to 1\), and the Euler–Maruyama arm diverges below \(200\) evaluations (pixel mean \(2.90\) against the data’s \(0.13\), two classes of ten covered) while posting the highest confidence in this section — the previous paragraph’s warning arriving from a second direction. The probability-flow row lags for the same reason, more mildly. So the choice that matters here is not stochastic versus deterministic; it is how the linear part gets integrated, and DDIM does it exactly at either \(\eta \).
The shape carries all the way up: the bestiary DDPM entry below is the same UNet at CIFAR scale, and Stable Diffusion is the same UNet on VAE latents with text cross-attention spliced in. Encoder-decoder-with-skips plus a sampling loop is the whole generative pipeline.
DDPM (Bestiary/Diffusion.lean)
Three new primitives (§ 163, § 164, § 169). The denoiser in Ho et al.’s DDPM (2020, arXiv:2006.11239) is a UNet — literally the same § 163 and § 164 Ronneberger shipped in 2015. Everything “diffusion” lives in the training loop: a forward noise schedule adds Gaussian noise over \(T\) steps, a reverse process learns to predict the added noise, sampling iterates the reverse from pure noise back to a clean image. None of that is a layer. The timestep conditioning MLP (sinusoidal \(\to \) dense \(\to \) dense) is shown as a standalone NetSpec that reuses positionalEncoding from NeRF. Variants: CIFAR config (32x32 backbone), 256x256 high-res config, tiny fixture, timestep embed. Our simplified backbone undercounts vs paper (paper DDPM adds residual blocks, GroupNorm, attention-at-low-res, and per-block time-embedding projection on top of the UNet); the spec’s value is showing the architectural shape, not an exact param match. The lesson is the same one CLIP and NeRF taught: the novelty lives in the training procedure, not in layer design.
def ddpmCifar : NetSpec where
  name   := "DDPM (CIFAR-10, backbone approx)"
  imageH := 32
  imageW := 32
  layers := [
    -- Encoder: 32 → 16 → 8 → 4
    .unetDown 3   128,                            -- 32 → 16
    .unetDown 128 256,                            -- 16 →  8
    .unetDown 256 256,                            --  8 →  4
    .convBn 256 256 3 1 .same,                    -- bottleneck
    .convBn 256 256 3 1 .same,
    -- Decoder: 4 → 8 → 16 → 32
    .unetUp 256 256, .unetUp 256 256, .unetUp 256 128,
    .conv2d 128 3 1 .same .identity               -- predict added noise (3-ch)
  ]
Stable Diffusion (Bestiary/StableDiffusion.lean)
Three new primitives (§ 163, § 164, § 161). The paper that made generative image models consumer-reachable (Rombach et al. 2022, arXiv:2112.10752). Two architectural moves over DDPM, each individually small: (a) latent diffusion — run the diffusion process on 64\(\times \)64\(\times \)4 VAE latents instead of 512\(\times \)512 pixels, cutting spatial work \(\sim \)64\(\times \); (b) text conditioning via cross-attention — at each interior UNet resolution, insert a spatial transformer block that cross-attends from image tokens to CLIP text embeddings. Shown as six separate NetSpecs: VAE encoder, VAE decoder, CLIP text encoder (123M, matches CLIP ViT-L/14 exactly), UNet backbone (190M backbone approx; real SD 1.5 UNet is 865M, missing \(\sim \)675M is the interleaved cross-attention), an explicit spatial-transformer-block spec (uses .transformerDecoder with nQueries = 0 — same primitive Whisper’s decoder uses, same mechanism as DETR’s decoder applied at image-feature resolution), and a tiny end-to-end fixture. Three components are pretrained and frozen during SD’s main training (VAE + text encoder) or constrained-frozen (CLIP); only the UNet trains. SDXL scales the UNet to 2.6B; SD 3 switches the UNet for a DiT transformer. The latent-diffusion plus text-conditioning template is the same.
def sdUNet15 : NetSpec where
  name   := "SD 1.5 UNet denoiser (backbone approx)"
  imageH := 64                                    -- latent resolution, not pixel
  imageW := 64
  layers := [
    .conv2d 4 320 3 .same .identity,              -- stem (latent → channels)
    -- Encoder: 64 → 32 → 16 → 8
    .unetDown 320  640,
    .unetDown 640  1280,
    .unetDown 1280 1280,
    -- Bottleneck at 8×8 (real SD inserts a spatial transformer here)
    .convBn 1280 1280 3 1 .same,
    .convBn 1280 1280 3 1 .same,
    -- Decoder: 8 → 16 → 32 → 64
    .unetUp 1280 1280,
    .unetUp 1280 1280,
    .unetUp 1280 640,
    .conv2d 640 4 3 .same .identity               -- predict noise (4-ch latent)
  ]
12.4 Physics — demo: Boltzmann generator on Müller–Brown
Networks whose target is a physical law rather than a labelled set: a Boltzmann density here, a PDE residual, a solution operator and the atmosphere six hours ahead in the entries below. The architectural side is small — an MLP, or a ViT with a Fourier mixer where its attention would be — and the novelty lives in what the model is asked to produce and in what is done with it afterwards.
A Boltzmann generator.
The target is not a dataset. It is a density, \(\exp (-U/kT)\) on the three-well surface Müller and Brown proposed in 1979 as the test case for reaction paths, and the training set is whatever overdamped Langevin manages to produce at \(kT = 20\) in a fixed budget: eight chains of \(10^5\) steps, the Euler–Maruyama integrator the diffusion demo’s table (§ 12.3) retired as a sampler, doing its actual job. The network is the 2-D toy demo’s MLP (demos/MainDiffusion2d.lean, \(18{,}178\) parameters, the sincos time channel at \(H = W = 1\)), the loss is that demo’s rank-2 squared-error block, and the flow flag changes one thing in the trainer, the interpolant: \(x_t = (1-t)\, x_0 + t\, \varepsilon \) with target \(\varepsilon - x_0\) (Lipman et al. 2022, arXiv:2210.02747) in place of the cosine-schedule \(x_t\) with target \(\varepsilon \). The sampler is Euler on \(\mathrm{d}x/\mathrm{d}t = v_\theta (x, t)\) from \(t = 1\) to \(0\). Three things change relative to the MNIST demo:
The ground truth is a formula. \(U\) has a closed form, so the well populations, the mean energy, the free-energy difference between wells and the exact likelihood are all numbers by quadrature on a \(360 \times 360\) grid. Every column of Tables 12-3 and 12-4 is exact for the quadrature row.
A sample set is a free-energy estimate. \(\Delta F_{AB} = -kT \ln (p_A / p_B)\) is read off the populations, and populations are assigned by gradient descent to a minimum rather than by nearest minimum, because the wells are elongated and Voronoi cells put part of A’s basin in C.
Temperature is a knob the trained model can be moved along without retraining. Every sample carries its own log-density: the Jacobian of each Euler step is two central differences in 2-D, and \(\log |\det (I + h\, \partial v/\partial x)|\) integrated beside the state is the continuity equation for the map actually run. With it, the importance weight \(\exp (-U/kT') / p_\theta (x)\) is a number, and that is the Boltzmann generator of Noé et al. 2019 (Science 365), on an 18k-parameter MLP.
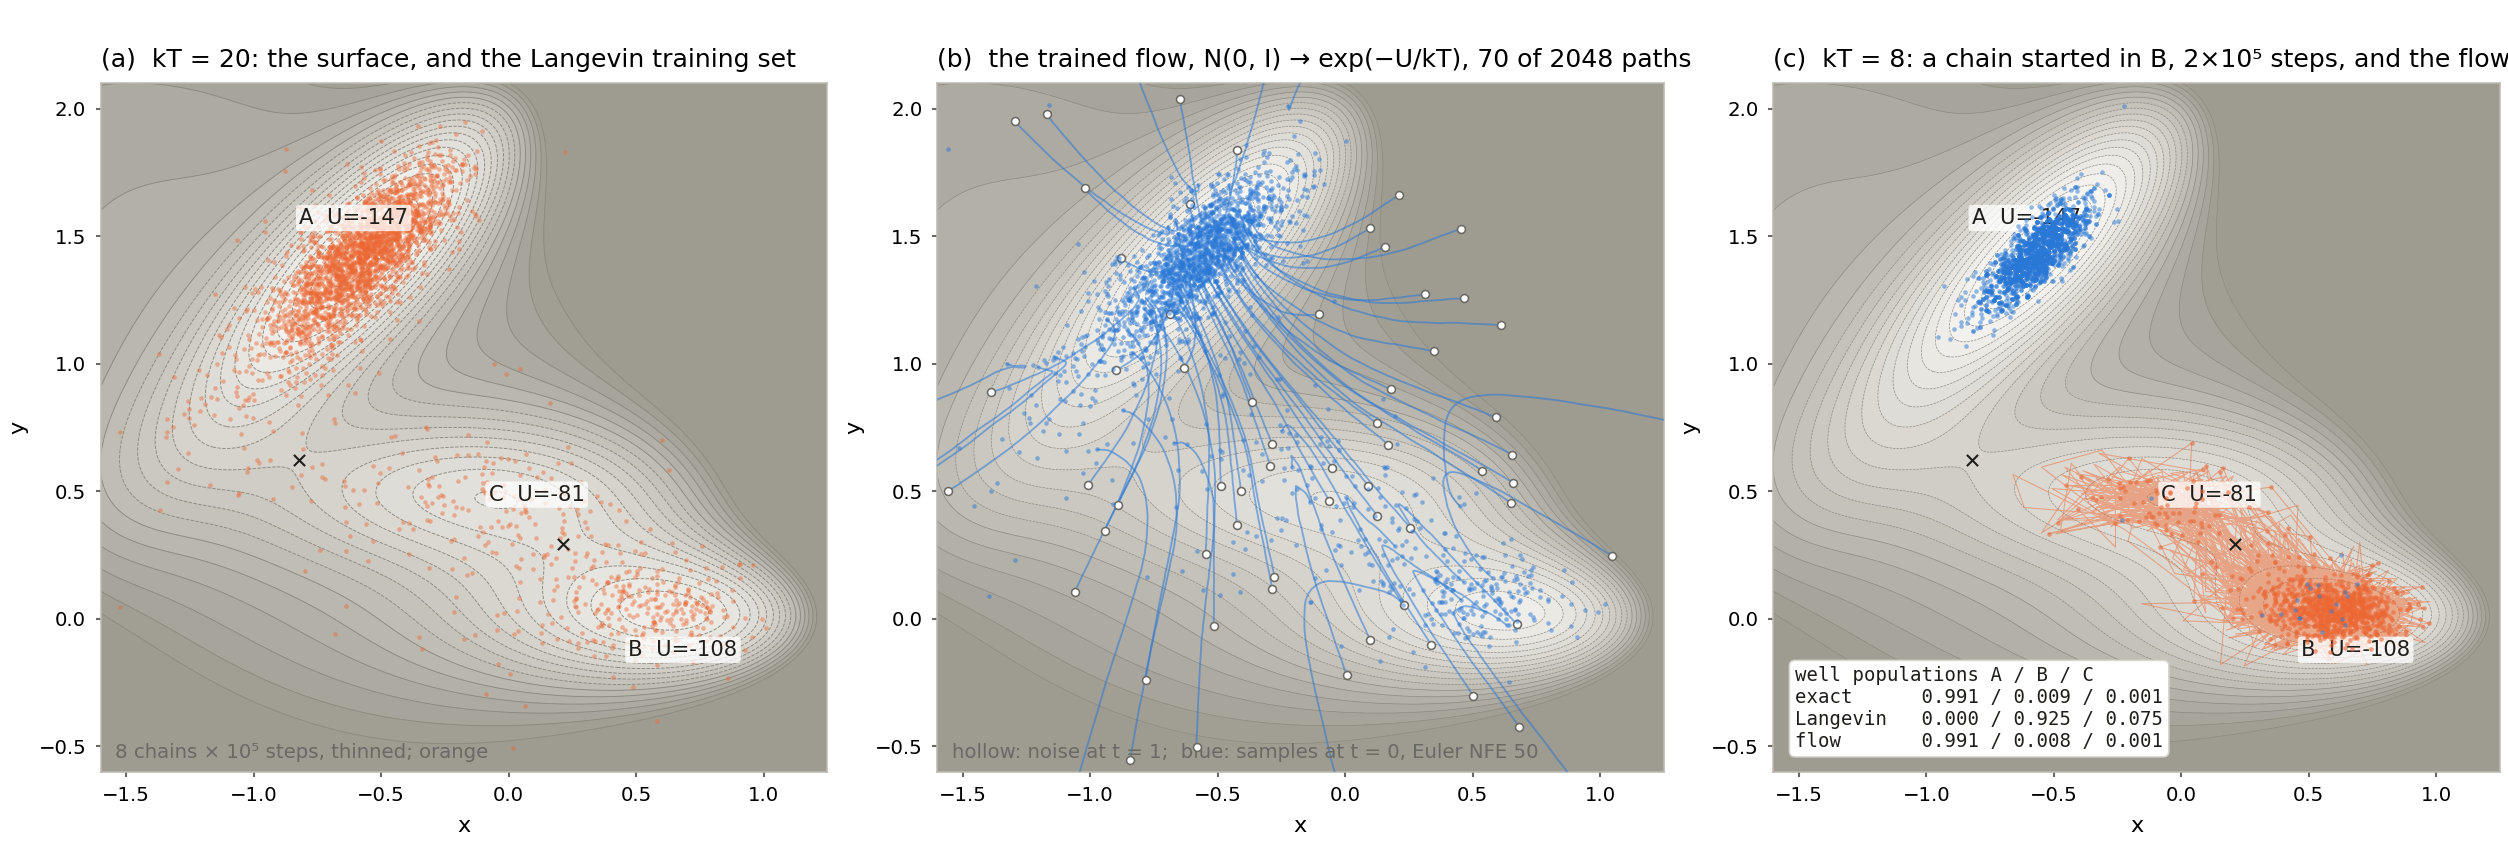
Figure 12-3 is the surface, the trained flow, and the reweighting that the chain cannot do.
Scored by quadrature, not by eye.
\(kT = 20\), \(2{,}048\) samples per row, the energy distance against an independent exact draw as a multiple of the exact-against-exact floor. The DDPM row is the same network, loss and budget with the cosine-schedule interpolant and DDIM in place of Euler:
|
source |
\(p_A \, /\, p_B \, /\, p_C\) |
\(\langle U \rangle \) |
\(\Delta F_{AB}\) |
energy (\(\times \) floor) |
|
quadrature (exact) |
\(0.806 \, /\, 0.129 \, /\, 0.065\) |
\(-113.6\) |
\(-36.6\) |
\(1\times \) (\(0.0015\)) |
|
Langevin training set, \(8 \times 10^5\) steps |
\(0.844 \, /\, 0.101 \, /\, 0.054\) |
\(-112.6\) |
\(-42.4\) |
\(4.1\times \) |
|
flow, Euler, NFE 50 |
\(0.834 \, /\, 0.103 \, /\, 0.063\) |
\(-112.4\) |
\(-41.9\) |
\(\mathbf{3.2\times }\) |
|
reweighted by \(p_{20} / p_\theta \) |
\(0.805 \, /\, 0.129 \, /\, 0.066\) |
\(-112.8\) |
\(-36.7\) |
— |
|
flow, Euler, NFE 10 |
\(0.840 \, /\, 0.086 \, /\, 0.073\) |
\(-117.7\) |
\(-45.5\) |
\(8.6\times \) |
|
flow, Euler, NFE 2 |
\(0.891 \, /\, 0.006 \, /\, 0.103\) |
\(-97.4\) |
\(-98.9\) |
\(91\times \) |
|
DDPM, DDIM, NFE 50 |
\(0.895 \, /\, 0.059 \, /\, 0.046\) |
\(-114.7\) |
\(-54.4\) |
\(18\times \) |
|
\(N(0, I)\) prior, no flow |
\(0.419 \, /\, 0.195 \, /\, 0.385\) |
\(57.2\) |
\(-15.3\) |
\(306\times \) |
The model is faithful to its training set, not to the physics: it over-weights A because the Langevin chains do. Reweighting its own samples by \(p_{20} / p_\theta \) recovers the quadrature row to the last digit. At NFE 2 well B empties while the populations still look plausible, which is why \(\langle U \rangle \) and \(\Delta F\) are columns.
MCMC stalls below the barrier; the generator does not.
The \(kT = 20\) samples reweighted to \(kT' = 12\) and \(8\), naively and with the model’s density in the weight, against a Langevin chain of \(2 \times 10^5\) steps started in well B:
|
\(kT'\) |
source |
\(p_A \, /\, p_B \, /\, p_C\) |
\(\Delta F_{AB}\) |
ESS |
|
12 |
quadrature (exact) |
\(0.949 \, /\, 0.042 \, /\, 0.009\) |
\(-37.4\) |
— |
|
Langevin from B, \(2 \times 10^5\) steps |
\(0.869 \, /\, 0.103 \, /\, 0.029\) |
\(-25.6\) |
— |
|
|
flow at \(kT = 20\), reweighted |
\(0.960 \, /\, 0.032 \, /\, 0.008\) |
\(-40.8\) |
\(1435\) |
|
|
with \(1/p_\theta \) in the weight |
\(0.949 \, /\, 0.042 \, /\, 0.009\) |
\(\mathbf{-37.4}\) |
\(1394\) |
|
|
8 |
quadrature (exact) |
\(0.991 \, /\, 0.009 \, /\, 0.001\) |
\(-38.0\) |
— |
|
Langevin from B, \(2 \times 10^5\) steps |
\(0.000 \, /\, 0.925 \, /\, 0.075\) |
— |
— |
|
|
flow at \(kT = 20\), reweighted |
\(0.993 \, /\, 0.006 \, /\, 0.000\) |
\(-40.7\) |
\(1001\) |
|
|
with \(1/p_\theta \) in the weight |
\(0.991 \, /\, 0.008 \, /\, 0.001\) |
\(\mathbf{-38.3}\) |
\(958\) |
The barrier out of B is 36 units; at \(kT = 8\) the chain never crossed. The naive weights carry the model’s bias in full; with \(1/p_\theta \) in them, samples drawn once at \(kT = 20\) land within 0.3 of quadrature at both temperatures. That is the paper’s claim, and it is the density that makes it.
Straightening the paths.
Rectified flow (Liu, Gong & Liu 2022, arXiv:2209.03003) retrains on the trained flow’s own (noise, sample) pairs; minibatch optimal-transport coupling (Tong et al. 2023, arXiv:2302.00482) pairs each batch’s noise to its data by a minimum-cost assignment. Neither changes the network. Table 12-5 is the energy distance as a multiple of the floor, with Liu’s straightness at NFE 50.
|
coupling |
NFE 1 |
NFE 2 |
NFE 5 |
NFE 10 |
NFE 50 |
straightness |
|
independent (flow matching) |
\(233\times \) |
\(91\times \) |
\(20\times \) |
\(8.6\times \) |
\(\mathbf{3.2\times }\) |
\(0.52\) |
|
minibatch OT |
\(7.2\times \) |
\(5.4\times \) |
\(4.7\times \) |
\(4.9\times \) |
\(5.1\times \) |
\(0.004\) |
|
reflow |
\(\mathbf{4.9\times }\) |
\(\mathbf{4.1\times }\) |
\(\mathbf{3.7\times }\) |
\(\mathbf{3.7\times }\) |
\(3.7\times \) |
\(0.0003\) |
A one-step generator: after reflow one Euler step lands at \(4.9\times \) the floor where the independent coupling needs ten. The price is the ceiling: both straightened arms plateau above it at NFE 50, because their training set is the first model’s output, biases included.
Boltzmann generator (Bestiary/BoltzmannGenerator.lean)
Zero new primitives for the flow-matching version, one if the original is shown. Noé et al.’s network is RealNVP (Dinh et al. 2017, arXiv:1605.08803): a stack of affine coupling blocks, each splitting the coordinates in half, passing one half through and scaling and shifting the other by two small dense nets of the first. Its log-density is the sum of the log-scales, exact and cheap, and the coupling split is a branch-and-merge the linear NetSpec cannot spell, so the entry shows one conditioner as its own dense net and the block structure in prose, the way the DCGAN entry stands in for transposed convs. The flow-matching version, which is what this book trains, is the demo’s velocity net verbatim; the exact log-density comes from the continuity equation instead of the coupling scales. Variants: the velocity net (18k), one RealNVP conditioner at alanine dipeptide’s width (25k), tiny fixture. The lesson is the one CLIP, NeRF and DDPM taught: the novelty is in what the model is asked to produce — a density, not a picture — and what is done with it afterwards. The architecture is an MLP.
def boltzmannVelocityNet : NetSpec where
  name   := "Boltzmann generator (flow-matching velocity net, Müller-Brown)"
  imageH := 1
  imageW := 1
  layers := [
    .dense 10 128 .relu,        -- 2 coordinates + 8 sincos time channels
    .dense 128 128 .relu,
    .dense 128 2 .identity      -- the velocity ε - x₀, rank-2 MSE block
  ]
Physics-informed neural network (Bestiary/PINN.lean)
Zero new primitives. Raissi, Perdikaris & Karniadakis (2019, J. Comput. Phys. 378; arXiv:1711.10561): the network is a small dense net \(u_\theta (x, t)\) and the loss is the differential equation, its residual evaluated at collocation points by differentiating the network with respect to its own inputs — Burgers’ equation needs \(u_t\), \(u_x\) and \(u_{xx}\) of the net, and the gradient of that residual with respect to the weights is a third-order object. Nothing in the architecture is new; everything in the training signal is. It is an entry and not a demo for that reason: Part 1’s VJP suite differentiates a parameter loss once, and the Boltzmann generator above is the physics this book can train, its physics entering through the target density rather than through derivatives of the network. Variants: the paper’s Burgers net (\(3{,}021\) parameters, the number every reimplementation quotes), Schrödinger (\(4 \times 100\), complex output as two channels), the Navier–Stokes inverse problem (stream function and pressure, two PDE coefficients learned alongside), tiny. \(\tanh \) is modelled as .gelu: the enum has no \(\tanh \), and a ReLU PINN would have \(u_{xx} = 0\) almost everywhere.
def pinnBurgers : NetSpec where
  name   := "PINN (Burgers, 8 x 20 tanh)"
  imageH := 1
  imageW := 1
  layers := [
    .dense 2 20 .gelu,        -- (x, t)
    .dense 20 20 .gelu,
    .dense 20 20 .gelu,
    .dense 20 20 .gelu,
    .dense 20 20 .gelu,
    .dense 20 20 .gelu,
    .dense 20 20 .gelu,
    .dense 20 20 .gelu,
    .dense 20 1 .identity     -- u(x, t)
  ]
Fourier neural operator (Bestiary/FNO.lean)
One new primitive, not shown. Li et al. (2021, arXiv:2010.08895) learn the solution operator of a PDE family rather than one solution: initial condition in, solution out, at any resolution. Four blocks of \(v \mapsto \sigma (Wv + \mathcal{F}^{-1}(R \cdot \mathcal{F} v))\): a pointwise \(1 \times 1\) conv \(W\) beside a spectral convolution that FFTs the field, keeps the lowest \(k\) modes and multiplies each by its own learned complex matrix. The spectral convolution is where the parameters and the idea live, and it is an FFT, a truncation and a per-mode matmul — none of which is a Part 1 layer — so the spec is the non-spectral skeleton (lifting, the four \(W\) bypasses, projection) with the spectral weights counted in prose: the 2-D Navier–Stokes config’s skeleton is \(4{,}577\) parameters and its four \(R\) tensors add \(921{,}600\), so the paper’s \(\sim \)926k model is 99.5 % a layer the linear spec cannot spell. Resolution invariance is that layer’s property alone; the pointwise parts would have it in any architecture. Variants: 2-D Navier–Stokes (width 20, 12 modes), 1-D Burgers (width 64, 16 modes), tiny.
def fno2dNavierStokes : NetSpec where
  name   := "FNO-2d (Navier-Stokes, width 20, 12 modes; non-spectral skeleton)"
  imageH := 64
  imageW := 64
  layers := [
    .conv2d 3 20 1 .same .identity,     -- P: lift (a, x, y) → width
    .conv2d 20 20 1 .same .gelu,        -- Fourier layer 1: W bypass (+ R, 230,400 reals)
    .conv2d 20 20 1 .same .gelu,        -- Fourier layer 2
    .conv2d 20 20 1 .same .gelu,        -- Fourier layer 3
    .conv2d 20 20 1 .same .identity,    -- Fourier layer 4
    .conv2d 20 128 1 .same .gelu,       -- Q: project
    .conv2d 128 1 1 .same .identity     --    → u(x, y)
  ]
FourCastNet (Bestiary/FourCastNet.lean)
One new primitive, shown with the primitive it replaces. Pathak et al. (2022, arXiv:2202.11214) put a ViT on ERA5’s \(0.25^\circ \) grid — \(720 \times 1440\) pixels, 20 variables, \(8 \times 8\) patches, \(16{,}200\) tokens of dimension 768, 12 blocks — and train it to predict the state six hours ahead; rollouts of that map are the forecast. The token mixer is not attention but the adaptive Fourier neural operator (Guibas et al. 2022, arXiv:2111.13587): the FNO’s spectral convolution made data-dependent and block-sparse, \(O(N \log N)\) in tokens where attention is \(O(N^2)\), and at \(16{,}200\) tokens that difference is the model. The spec keeps the patch embedding, dimension, depth and MLP and puts .transformerEncoder where the AFNO block goes, which overcounts: attention at 768 spends \(4 \times 768^2 \approx 2.36\) M parameters a block where AFNO’s block-diagonal complex MLP spends \(0.30\) M; the MLPs, three quarters of a block either way, are the same. Variants: the paper’s model, a \(2^\circ \) version at a size one card trains, tiny.
def fourCastNet : NetSpec where
  name   := "FourCastNet (AFNO-ViT, 0.25°, attention standing in for AFNO)"
  imageH := 720
  imageW := 1440
  layers := [
    .patchEmbed 20 768 8 16200,           -- 20 variables, 8×8 patches → 16,200 tokens
    .transformerEncoder 768 12 3072 12,   -- 12 blocks; the paper's mixer is AFNO
    .dense 768 1280 .identity             -- back to an 8×8×20 patch
  ]
12.5 Signal processing — demo: gravitational-wave detection on LIGO strain
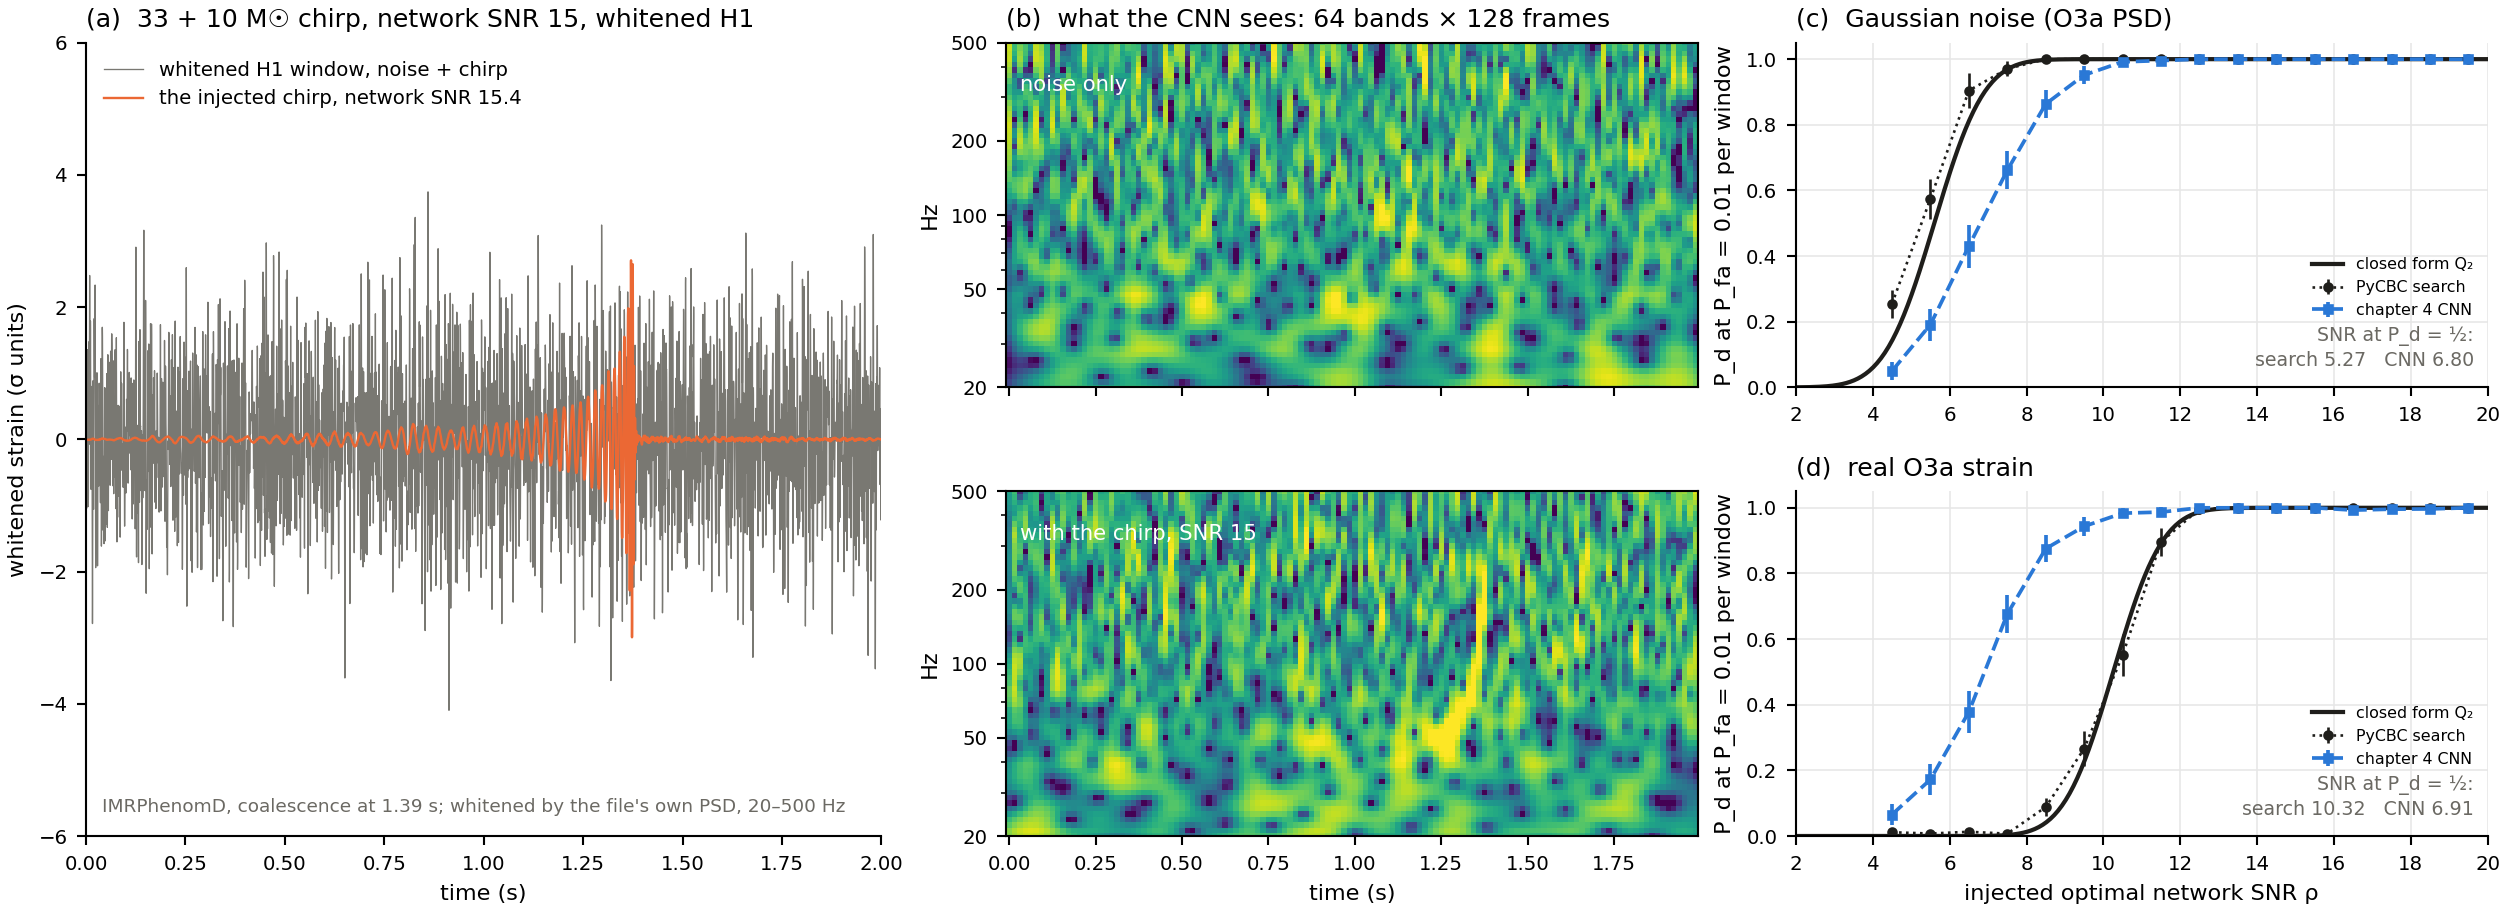
Networks whose input is a waveform: strain from an interferometer, raw audio, the spectrogram of a voice. The demo scores a chapter-4 CNN against the detector its field already has, whose performance in Gaussian noise is a closed form; the two entries after it are the audio architectures that read the same kind of input, one sample at a time and one spectrogram frame at a time. Figure 12-4 is the demo on one page: a window, the two spectrograms, and the detection curves in both noises.
A CNN against the matched filter on LIGO strain.
This demo has a theorem for a ceiling the way Leduc poker has its best response (§13.2) and the Boltzmann generator has quadrature. Advanced LIGO’s strain is a time series at audio rates, and a binary-black-hole merger is a chirp that sweeps from 25 to a few hundred Hz in under a second. The Gravitational Wave Open Science Center publishes every observing run under CC BY 4.0 (Abbott et al. 2023, ApJS 267, 29); real events are too few to train on, so the training set is real detector noise with simulated chirps injected at chosen signal-to-noise ratios. The detector to beat is the matched filter: in stationary Gaussian noise it is the Neyman–Pearson optimum, and its detection probability at threshold \(\rho ^\ast \) for a signal of optimal SNR \(\rho \) is a Marcum \(Q\)-function. Three things change relative to the CIFAR demo:
The data is real detector noise with the signal we chose. Twenty-six file pairs of O3a strain from H1 and L1, science-mode and free of hardware injections, cut into \(2\) s windows and whitened by each file’s own median-Welch PSD over 20–500 Hz. Half the windows carry an IMRPhenomD chirp from PyCBC, masses uniform in \([10, 50]\, M_\odot \), random sky position, projected onto both detectors and scaled to a network SNR uniform in \([4, 20]\). Two noise sets share every window and every injection: Gaussian noise coloured by the same PSD, the theorem’s regime, and the strain itself. \(40{,}760\) training and \(12{,}228\) validation windows.
The instrument is a closed form, and the filter is checked against it first. PyCBC’s matched filter with the injected template, at the known arrival time, reproduces \(Q_1(\rho , \rho ^\ast )\) on the Gaussian set to within binomial error in every SNR bin — the SNR at half detection is \(4.68\) against the theorem’s \(4.75\) for H1 at a false-alarm rate of \(10^{-2}\) per window — so the injection’s SNR and the whitening agree on one PSD. The search statistic then maximises over the window and the \(\pm 10\) ms inter-detector delay, exactly as a search must, and the CNN, which sees no time, is compared to that.
The network is Chapter 4’s CIFAR net. CIFAR-CNN8-wide-BN: eight convolutions in four conv-conv-pool stages at 16, 16, 32, 32 channels into the \(2 \times 512\) head. The two edits are the two-channel stem and the two-way output, \(0.83\) M parameters at this input. The input is a \(2 \times 64 \times 128\) image, each channel a constant-Q spectrogram of one detector’s whitened window (64 log-spaced bands over 20–500 Hz, 128 frames); the ordinary train step with integer labels, Adam at \(10^{-3}\) with one warm-up epoch and cosine decay, batch 64, six epochs, under two minutes on one card. Nothing in the codegen moved.
Scored against the theorem.
Detection probability by injected network SNR on the Gaussian set, \(12{,}228\) validation windows, every threshold set on the \(8{,}177\) noise-only windows so that one in a hundred exceeds it. The last column of Table 12-6 is the SNR at which each row crosses one half.
|
\(\rho \) |
4 |
5 |
6 |
7 |
8 |
9 |
10 |
12 |
\(\rho _{1/2}\) |
|
closed form \(Q_2(\rho , \rho ^\ast )\), \(\rho ^\ast = 5.86\) |
\(0.14\) |
\(0.46\) |
\(0.80\) |
\(0.96\) |
\(1.00\) |
\(1.00\) |
\(1.00\) |
\(1.00\) |
\(5.63\) |
|
PyCBC coherent search, true template |
\(0.26\) |
\(0.58\) |
\(0.90\) |
\(0.97\) |
\(1.00\) |
\(1.00\) |
\(1.00\) |
\(1.00\) |
\(\mathbf{5.27}\) |
|
CNN on spectrograms, trained on Gaussian noise |
\(0.05\) |
\(0.19\) |
\(0.43\) |
\(0.66\) |
\(0.86\) |
\(0.95\) |
\(0.99\) |
\(1.00\) |
\(6.80\) |
|
random |
\(0.01\) |
\(0.01\) |
\(0.01\) |
\(0.01\) |
\(0.01\) |
\(0.01\) |
\(0.01\) |
\(0.01\) |
— |
The filter sits on its closed form and the CNN trails it by \(1.5\) units of SNR. Gabbard et al. 2018 (PRL 120) closed that gap with a one-dimensional network on the whitened strain and ten times the training set; a log-power spectrogram discards the phase the filter integrates, and this is the demo’s number, not the architecture’s ceiling.
Real noise costs the filter, not the network.
LIGO noise is neither stationary nor Gaussian, and the production search adds a \(\chi ^2\) veto for exactly that reason. Table 12-7 is the same rows on the strain itself, with each model trained on one noise set and scored on both.
|
\(\rho _{1/2}\) at \(10^{-2}\) |
\(10^{-3}\) |
||
|
trained on |
tested on Gaussian |
tested on real |
tested on real |
|
CNN, Gaussian noise |
\(6.80\) |
\(7.17\) |
\(18.7\) |
|
CNN, real O3a strain |
\(6.65\) |
\(\mathbf{6.91}\) |
\(\mathbf{7.52}\) |
|
PyCBC coherent search |
\(\mathbf{5.27}\) |
\(10.32\) |
— |
Each network is best on the noise it trained on, by a few tenths. The filter loses five units of SNR to glitches at \(10^{-2}\), and at \(10^{-3}\) its threshold is \(417\): eight validation windows hold a glitch that loud, and without a veto the filter has no row. The network trained on Gaussian noise needs an SNR of \(19\) there; the one trained on real strain still reaches half detection at \(7.5\). Training on the real detector is what teaches the glitch tail.
WaveNet (Bestiary/WaveNet.lean)
One new primitive (§ 168). Dilated causal convolutions for raw audio sample prediction (van den Oord et al. 2016, arXiv:1609.03499): exponential receptive field, linear parameter growth. The foundation of neural TTS and PixelCNN. Variants: single stack (0.4M), 3-stack (paper setup, with a NetSpec-linearity approximation), music (single stack, 4.1M), tiny. One honest limitation: the residual-vs-skip dual-output pattern doesn’t linearize cleanly, so the 3-stack variant uses a simplified channel-flow approximation.
def waveNet : NetSpec where
  name   := "WaveNet (single stack, speech)"
  imageH := 16000                                 -- 1 second @ 16 kHz
  imageW := 1
  layers := [
    -- Input embedding: 256 mu-law bins → 32 residual channels
    .conv2d 256 32 1 .same .identity,
    -- One stack of 10 dilated residual blocks (dilations 2⁰..2⁹)
    .waveNetBlock 32 512 10,
    -- Output head: skip-sum → 1×1 → 1×1, 256-way categorical
    .conv2d 512 256 1 .same .relu,
    .conv2d 256 256 1 .same .identity
  ]
Whisper (Bestiary/Whisper.lean)
One new primitive (§ 161). Encoder-decoder transformer over log-mel spectrograms (Radford et al. 2022, arXiv:2212.04356). Encoder is .transformerEncoder on the 1500 post-stem audio tokens; decoder is .transformerDecoder (from DETR) with nQueries = 0 — a clean seq2seq decoder with self-attn + cross-attn + FFN, text tokens coming from a separate .dense vocab\(\to \)D stand-in tied to the LM head. Variants: tiny (7M enc, paper 39M total), base (19M enc, paper 74M), small (85M enc + 153M dec+emb = 238M vs paper 244M), medium (302M enc, paper 769M), large (629M enc, paper 1.55B total), plus a shared decoder spec and tinyWhisper fixture. Encoder and decoder are the same size per variant; adding them together recovers paper totals within 2–3%. The multitask interface (swap a prefix token to change language or switch between transcribe / translate) is prompt-engineering, not architecture — Whisper’s architectural novelty is essentially zero.
def whisperSmall : NetSpec where
  name   := "Whisper small encoder"
  imageH := 1500                                  -- post-stem audio tokens (3000 / 2)
  imageW := 1
  layers := [
    -- 12 encoder blocks, dim 768, 12 heads, mlp 3072
    .transformerEncoder 768 12 3072 12
  ]
12.6 Beyond vision — demo: neural quantum states on the Ising chain
Architectures where the task domain is neither a 2D image nor a token sequence: a wavefunction, a radiance field, a shared embedding space. The demo points Chapter 9’s transformer, as an encoder and as a decoder, at a quantum ground state, where there is no dataset at all and the ceiling is a solved model; the entries after it (NeRF, CLIP, LLaVA) make the same point from the other side — several have essentially no architectural novelty, and the interesting work lives in the data, loss, or training procedure.
A transformer as a wavefunction.
Take a ring of \(N\) spins, each up or down. Neighbours want to agree, with strength \(J\); a field \(h\) wants each spin to point sideways, which in quantum mechanics means to be up and down at once. That is the transverse-field Ising chain, \(H = -J \sum _i \sigma ^z_i \sigma ^z_{i+1} - h \sum _i \sigma ^x_i\), and its lowest-energy state is the textbook quantum phase transition: for \(h {\lt} J\) the spins agree, for \(h {\gt} J\) they do not, and at \(h = J\) every pattern in between. The ground state is a probability amplitude \(\psi (\sigma )\) over all \(2^N\) configurations, and a neural quantum state (Carleo & Troyer 2017, Science 355, 602) is a network that maps a configuration \(\sigma \in \{ \pm 1\} ^N\) to its log-amplitude, trained by lowering the energy \(\langle \psi | H | \psi \rangle / \langle \psi | \psi \rangle \). The demo climbs a ladder of three such networks, each written as a closed-form reference times a learned residual, \(\psi _\theta = \psi _{\mathrm{ref}} \cdot \exp f_\theta \), with \(\psi _{\mathrm{ref}}\) the mean-field product state at its optimal angle — a log-amplitude linear in \(\sigma \) that the host adds to the network’s output before any ratio is formed. \(f_\theta \) is an MLP on the \(\pm 1\) spins (\(5{,}057\) parameters at \(N = 12\)); a ViT that reads patches of \(p\) spins as token ids through tokenPositionEmbed, two encoder blocks at \(d = 32\), a mean over tokens and a one-unit head (\(25{,}825\); the transformer wavefunctions of Viteritti, Rende & Becca 2023, arXiv:2211.05504); or a GPT on the same tokens, two causal blocks and an lmHead, whose conditionals are the wavefunction, \(|\psi (\sigma )|^2 = \prod _k p(\mathrm{patch}_k \mid \mathrm{patch}_{{\lt}k})\), so that a sample is an autoregressive draw through the TinyGPT sampling loop with a vocabulary of \(2^p\) (\(25{,}956\); Sharir et al. 2020, arXiv:1902.04057). Three things change relative to the TinyGPT demo:
There is no dataset. The training signal is the model’s own local energies, \(E_{\mathrm{loc}}(\sigma ) = -J \sum _i \sigma _i \sigma _{i+1} - h \sum _i \psi (\sigma ^{(i)}) / \psi (\sigma )\) with \(\sigma ^{(i)}\) the \(i\)-th spin flipped, so a batch of \(B\) configurations costs one extra forward at batch \(B \cdot N\). The energy is a weighted mean of \(E_{\mathrm{loc}}\) and its gradient, \(\partial _\theta E = 2 \sum _\sigma p_\sigma \, (E_{\mathrm{loc}}(\sigma ) - E)\, \partial _\theta \log \psi (\sigma )\), is one host weight \(w_\sigma \) per configuration. That weight enters the train step through the rank-2 squared-error block of the diffusion demo (§ 12.3) with the target set to \(\mathrm{out} - M w / 2\), so the block’s output cotangent is exactly \(w\): the Pong DQN’s trick (§ 13.1) with a physical target, and zero new codegen. At \(N = 12\) the sum runs over all \(4{,}096\) configurations and the gradient is exact; at \(N = 64\) the MLP and ViT sample by Metropolis on \(1{,}024\) chains and the GPT draws independent samples.
Structure first, the network models the rest. At \(f_\theta = 0\) the ansatz is the mean-field state, so step 0 of every run prints the mean-field energy to six digits and the network only has to learn what mean field gets wrong. For the MLP and ViT the reference is a fixed visible bias; for the GPT it is a fixed bias on the logits, so that the conditionals stay normalised.
The instrument is a solved model. Every number in Table 12-8 is bracketed by a closed form: enumeration of the \(4{,}096 \times 4{,}096\) Hamiltonian at \(N = 12\), and at \(N = 64\) the free-fermion solution of Pfeuty 1970, which agrees with enumeration to \(7 \times 10^{-15}\) where both apply. The variance of \(E_{\mathrm{loc}}\) over the samples is the instrument that needs no ceiling: zero for an eigenstate at any \(N\).
Figure 12-5 is the chain’s three phases as the network draws them, and the check against the exact ground state.
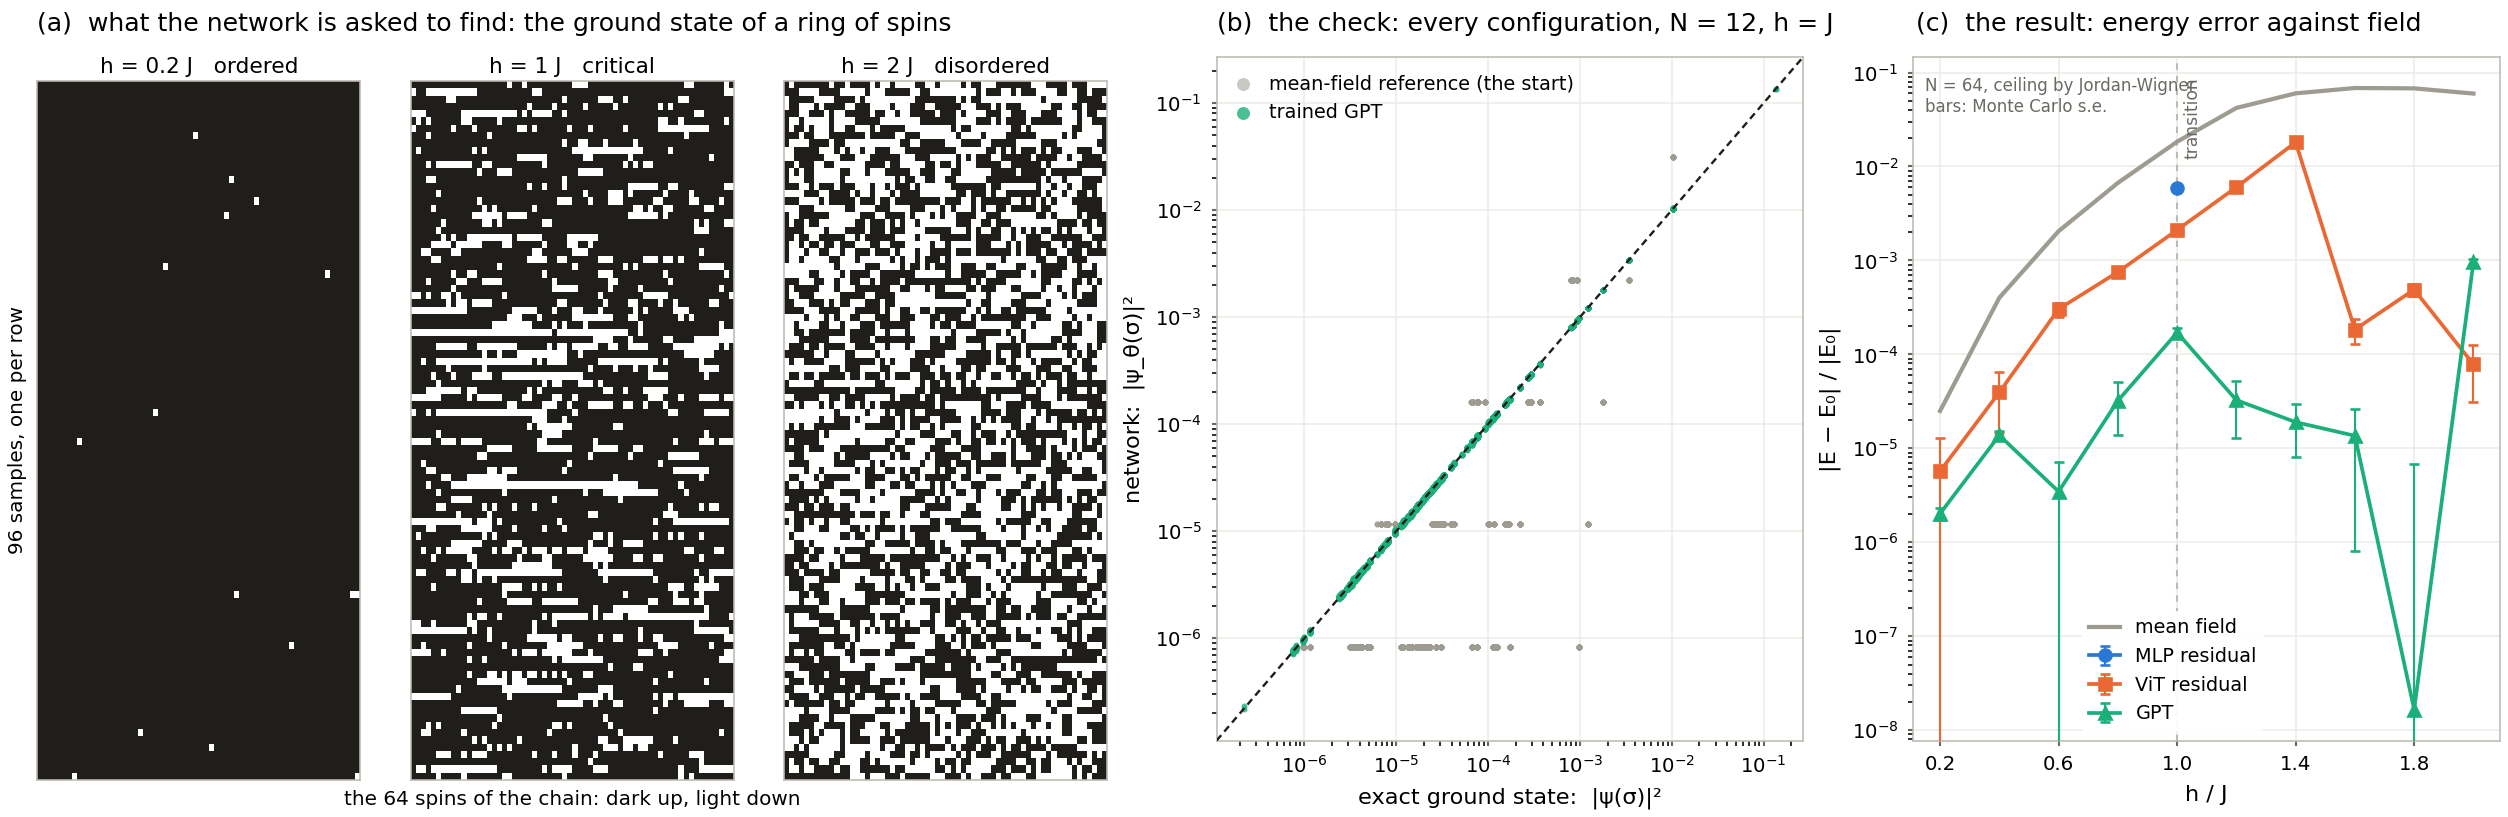
The ladder at the critical point.
\(h = J\), Adam with cosine decay, \(4{,}000\) steps at \(N = 12\) and \(2{,}000\) at \(N = 64\), one RTX 4060 Ti: 50 s to 330 s per row at \(N = 12\) with the XLA compile included and about twenty minutes at \(N = 64\). The \(N = 64\) energies are means over the final \(8{,}192\) samples, whose Monte Carlo standard error is below five percent of every entry. Table 12-8 is the ladder.
|
\(h = J\) |
params |
\((E - E_0)/|E_0|\) |
\(\mathrm{Var}(E_{\mathrm{loc}})\) |
\(\langle \sigma ^x \rangle \) |
\(\langle \sigma ^z_1 \sigma ^z_{1+N/2} \rangle \) |
|
\(N = 12\), exact gradient by enumeration |
|||||
|
mean field (floor) |
0 |
\(2.1 \times 10^{-2}\) |
0 |
0.5000 |
0.7500 |
|
MLP residual |
\(5{,}057\) |
\(1.6 \times 10^{-5}\) |
\(4.3 \times 10^{-3}\) |
0.6383 |
0.4613 |
|
ViT residual |
\(25{,}825\) |
\(1.5 \times 10^{-5}\) |
\(2.5 \times 10^{-3}\) |
0.6381 |
0.4618 |
|
GPT |
\(25{,}956\) |
\(\mathbf{3.3 \times 10^{-6}}\) |
\(5.2 \times 10^{-4}\) |
0.6384 |
0.4611 |
|
exact (enumeration) |
— |
0 |
0 |
0.6384 |
0.4610 |
|
\(N = 64\), \(p = 4\), \(1{,}024\) chains |
|||||
|
mean field (floor) |
0 |
\(1.8 \times 10^{-2}\) |
0 |
0.5000 |
0.7500 |
|
MLP residual, Metropolis |
\(8{,}385\) |
\(5.9 \times 10^{-3}\) |
\(3.7\) |
0.5660 |
0.6256 |
|
ViT residual, Metropolis |
\(26{,}529\) |
\(2.1 \times 10^{-3}\) |
\(0.48\) |
0.5921 |
0.5616 |
|
GPT, exact sampling |
\(27{,}056\) |
\(\mathbf{1.7 \times 10^{-4}}\) |
\(0.020\) |
0.6341 |
0.3498 |
|
exact (Jordan–Wigner) |
— |
0 |
0 |
0.6367 |
0.3036 |
At \(N = 12\) every rung sits three to four orders below the floor and the GPT, whose conditionals are the wavefunction, is the best of them at every field in the sweep. At \(N = 64\) the ladder separates, and the sampler is why: the GPT’s draws are independent and its gradient noise is only the batch’s, so it holds \(10^{-5}\) to \(10^{-4}\) at every field but the critical point, while the ViT on Metropolis chains is ten to a thousand times worse at the same parameter count and step budget, and at \(h = 1.4\) doubling its chains and steps makes it diverge. That is the regime stochastic reconfiguration (Sorella 1998, PRL 80, 4558) exists for; nothing at \(N = 12\) needed it.
Three things the sweep taught.
The reference decides the small-field rows, and the ablation says by how much: the same ViT, from the uniform state and from the mean-field state, is three orders of magnitude apart at \(h = 0.2J\) (\(3.0 \times 10^{-5}\) against \(1.6 \times 10^{-8}\)), two at \(0.4J\), and level at \(h = J\), where the reference is as wrong as the uniform state and the network does all the work either way. Low variance with a wrong energy is the wrong state: the ViT at \(N = 12\), \(h = 0.8J\) converges to \(5.4 \times 10^{-4}\) with a variance three times lower than its neighbours’, unmoved by seeds, steps, width, depth or patch size, and its excess energy is \(\Delta /2\) to three digits, \(\Delta \) the splitting between the even- and odd-parity states — it converged to the symmetry-broken half of the finite-\(N\) cat state that the product-state reference imprints, and the fix was more structure, not more network: the symmetrised reference \(\psi _{\mathrm{MF}}(\sigma ) + \psi _{\mathrm{MF}}(-\sigma )\), one logaddexp on the host, takes it to \(2.0 \times 10^{-5}\). And signs are the open row. The Ising ground state is positive, so the rungs above are real; the \(J_1\)–\(J_2\) Heisenberg chain is frustrated and its ground state has a sign structure, so the head gets a second slot, \((\log |\psi |, \varphi )\), with Marshall’s sign rule as the reference phase and two host weights per configuration through the same block. At \(N = 16\) the phase head learns the Marshall signs from scratch at \(J_2 = 0\) (fidelity \(0.9985\)), every arm finds the Majumdar–Ghosh dimer state at \(J_2 = J_1/2\) to \(3 \times 10^{-6}\) with fidelity \(1.000\), and past that point, where the rule breaks, every arm stalls at \(10^{-2}\) with a fidelity below \(0.6\) that four times the width and twice the steps move only to \(0.58\).
Two gates sit under the table. The autoregressive sampler, drawn \(16{,}384\) times from a trained \(N = 12\) state and scored by table lookup, lands within \(0.1\) standard errors of the same state’s enumerated energy; on a trained state a single check scatters wider than \(N(0, 1)\) because \(E_{\mathrm{loc}}\) is heavy-tailed, so the pooled test over eight draw seeds is the one that decides. And step 0 of every run is the floor row to six digits, which is the check that the host adds the reference where the ansatz says it does. The trainer is demos/MainNqsIsing.lean; the closed forms, the Lanczos ceiling and every table are scripts/demos/nqs_metrics.py.
NeRF (Bestiary/NeRF.lean)
Two new primitives (§ 169, § 170). The "it’s literally just an MLP" paper (Mildenhall et al. 2020, arXiv:2003.08934). Under 600K params at canonical config; the architectural novelty is nonexistent. What makes NeRF work is the positional encoding + the volumetric-rendering loss — both outside the network, not layers in it. Variants: canonical (593K), fast (167K hidden=128), tiny fixture.
def nerf : NetSpec where
  name   := "NeRF (canonical)"
  imageH := 1
  imageW := 1
  layers := [
    -- Positional encoding of (x,y,z): 3 coords × 2 × 10 freqs = 60-dim
    .positionalEncoding 3 10,
    -- 8-layer MLP with mid-skip + dual density/RGB heads.
    -- encodedDirDim = 3·2·4 = 24 (3D view direction, 4 frequencies)
    .nerfMLP 60 24 256
  ]
CLIP (Bestiary/CLIP.lean)
Zero new primitives. Two textbook encoders glued together by a contrastive loss (Radford et al. 2021, arXiv:2103.00020): a ResNet-50 or ViT-B for images, a 12-layer causal transformer for text, each with a final linear projection to a shared embedding space. Variants: CLIP-RN50, CLIP-ViT-B/32 (151M, paper-exact), CLIP-ViT-L/14 (427M, paper-exact), tiny fixture. The architectural lesson from CLIP is identical to NeRF’s: the novelty lives in data and objective, not in layer design.
def clipViTB32ImageEncoder : NetSpec where
  name   := "CLIP-ViT-B/32 (image encoder)"
  imageH := 224
  imageW := 224
  layers := [
    -- ViT-B/32: patch size 32 → 49 patches, dim 768, 12 blocks, 12 heads
    .patchEmbed 3 768 32 49,
    .transformerEncoder 768 12 3072 12,
    -- [CLS] token → shared 512-dim embedding space
    .dense 768 512 .identity
  ]
LLaVA / LLaVA-1.5 (Bestiary/LLaVA.lean)
Zero new primitives. The cleanest exhibit of the modern vision-language pattern (Liu et al. 2023, arXiv:2304.08485; LLaVA-1.5: arXiv:2310.03744): frozen CLIP ViT encoder + small MLP projector + (mostly) frozen LLaMA/Vicuna language model. Trained in two stages — projector-only pretrain, then joint instruction fine- tune. Shown as separate NetSpecs per component: vision encoder (303M, matching CLIP ViT-L/14), LLaVA-1 single-linear projector (4M), LLaVA-1.5 two-layer MLP projector (21M), LLM backbones at 7B and 13B. The LLM specs undercount real LLaMA by \(\sim \)23% because our .transformerEncoder uses a standard 2-projection FFN while LLaMA uses SwiGLU (3 projections); depth / width / heads still match. Key ratio: the projector is 0.3% of total LLaVA-1.5 7B parameters — the entire interesting work of the model lives in 21M of trainable bolt-on between two pretrained backbones. BLIP-2, Flamingo, and every modern VLM demo generalize this template with fancier adapters (Q-Former, Perceiver resampler, gated xattn-dense), but the frozen-backbone-plus-adapter shape is the same.
def llava15Projector : NetSpec where
  name   := "LLaVA-1.5 projector (2-layer MLP)"
  imageH := 576                                   -- visual token count (24×24)
  imageW := 1
  layers := [
    -- The entire LLaVA architectural contribution: map CLIP's 1024-dim
    -- image tokens into the LLM's 4096-dim embedding space. ~21M params
    -- — roughly 0.3% of total LLaVA-1.5 7B. GELU between is zero-param.
    .dense 1024 4096 .identity,
    .dense 4096 4096 .identity
  ]
12.7 Structure — demo: a distogram ResNet against the CASP16 field
Networks whose input is a protein’s sequence and whose output is its shape. The demo is the recipe that held the field from 2018 to 2020 — a deep two-dimensional residual network predicting a histogram of distances for every pair of residues, and a fold obtained by descending that histogram’s negative log-likelihood — with a frozen protein language model in place of the multiple-sequence alignment those methods read, scored on CASP16’s targets beside the groups that predicted them blind. The entry after it is the architecture that ended that era.
A residual network on residue pairs.
A protein is a string over twenty letters, and its fold is set by which residues end up near each other. Write the distance between the \(\beta \)-carbons of residues \(i\) and \(j\) as a histogram over 64 bins from 2 to 22 Å, one per pair: that \(L \times L\) array of histograms is the distogram, and AlphaFold 1 (Senior et al. 2020, Nature 577, 706) and trRosetta (Yang et al. 2020, PNAS 117, 1496) were exactly this shape: per-residue features tiled into an \(L \times L\) pair tensor, a deep 2D ResNet, a histogram per pair, and a fold by gradient descent on the histogram’s negative log-likelihood over coordinates. Those methods read a multiple-sequence alignment; here the per-residue features are the final-layer representation of ESM-2 (Lin et al. 2023, Science 379, 1123), a protein language model trained on sequences alone, frozen, \(2{,}560\) wide at its 3B-parameter size, with the model’s own contact map — a logistic regression on its attention heads — riding along as one pair channel. The input is a single sequence, and the language model runs once, outside the proof. The network is Chapter 5’s ResNet with its strides removed — sixteen of its basic blocks at 128 channels, residualBlock 128 128 16 1 — with one new layer in front (the pair tile, § 165: two dense maps and an outer sum) and a \(1 \times 1\) head of 132 channels — the 66-class distance head, which is the 64 bins, a “beyond 22 Å” class and an “unobserved” class at weight zero, how a missing residue leaves the loss, and trRosetta’s three orientation heads, the dihedrals \(\omega \) and \(\theta \) and the angle \(\varphi \) between the two residues’ \(\mathrm{C}_\alpha \)–\(\mathrm{C}_\beta \) bonds in \(15^\circ \) bins. \(5{,}418{,}244\) parameters. Training reads every protein chain the PDB released before CASP16 opened on 2024-05-01, one representative per 40 % sequence cluster, \(26{,}310\) chains, as random \(96 \times 96\) windows of their pair maps, 100 epochs in 21 hours on one RTX 4060 Ti; inference tiles the same window over a target at stride 32 and averages the logits, so the trained artifact is the one that is scored. The fold is Adam on the smoothed negative log-likelihood of the predicted distances and angles over one pseudo-\(\mathrm{C}_\beta \) point per residue, with a chain term and a clash term, from a classical-MDS start, in both mirror images. Three things change relative to the segmentation demo:
The input is a pair map built on the host from a frozen model’s output. The pair tile takes the two residue blocks of a crop, \(2 L D\) numbers per example, projects each through its own \(D \to C\) map and outer-sums them into the \([C, L, L]\) map; \(K\) host pair planes are concatenated behind the tile’s channels. It is the one new layer and the one new proof item, Proofs/Foundation/PairTile.lean: the backward in each weight is the cotangent summed over the broadcast axis, then contracted with the block — the two reduce + dot_general pairs the emitter writes — and there is no input gradient, because the blocks are the language model’s and it is not trained. Everything downstream of the tile is the chapter’s; the demo’s gradient evidence is the finite-difference check on the tile’s weights and the eval \(\equiv \) train identity, not a whole-net step tie.
The loss has four heads and the label is packed. perPixelMultiCE is the segmentation demo’s weighted per-pixel cross-entropy summed over \(K\) heads of one output tensor, the \(K\) labels carried mixed-radix in the one int32 plane the segmentation ABI already passes, each head’s “unobserved” class at weight zero. One sentence the fold needs: lDDT is a distance score and cannot see a mirror image, TM-score superposes with a proper rotation and can, and a fold from distances alone has that ambiguity — the true trace of T1235-D1 and its mirror both score a \(\mathrm{C}_\beta \)-lDDT of 1.00, at TM-scores of 1.00 and 0.34. The \(\omega \) dihedral is chiral, so with the orientation heads the hand is the lower-energy one.
The instrument is the field. CASP16’s Phase-1 targets — 84 evaluation units whose experimental structures were released after the predictions were in — scored the way CASP scored them: OpenStructure’s lDDT and US-align’s TM-score reproduce the official table to the printed digit on nine field models, and our fold and every group’s model are reduced to the same pseudo-\(\mathrm{C}_\beta \) atom before they are compared. The training set is the information the field had, a date cut; purging the 82 chains homologous to a target is an ablation, and is worth nothing. The single-sequence reference is ESMFold, the same language model under the folding trunk its authors trained for it.
Figure 12-6 is one target’s contact map, predicted against measured, and our fold beside the field’s.
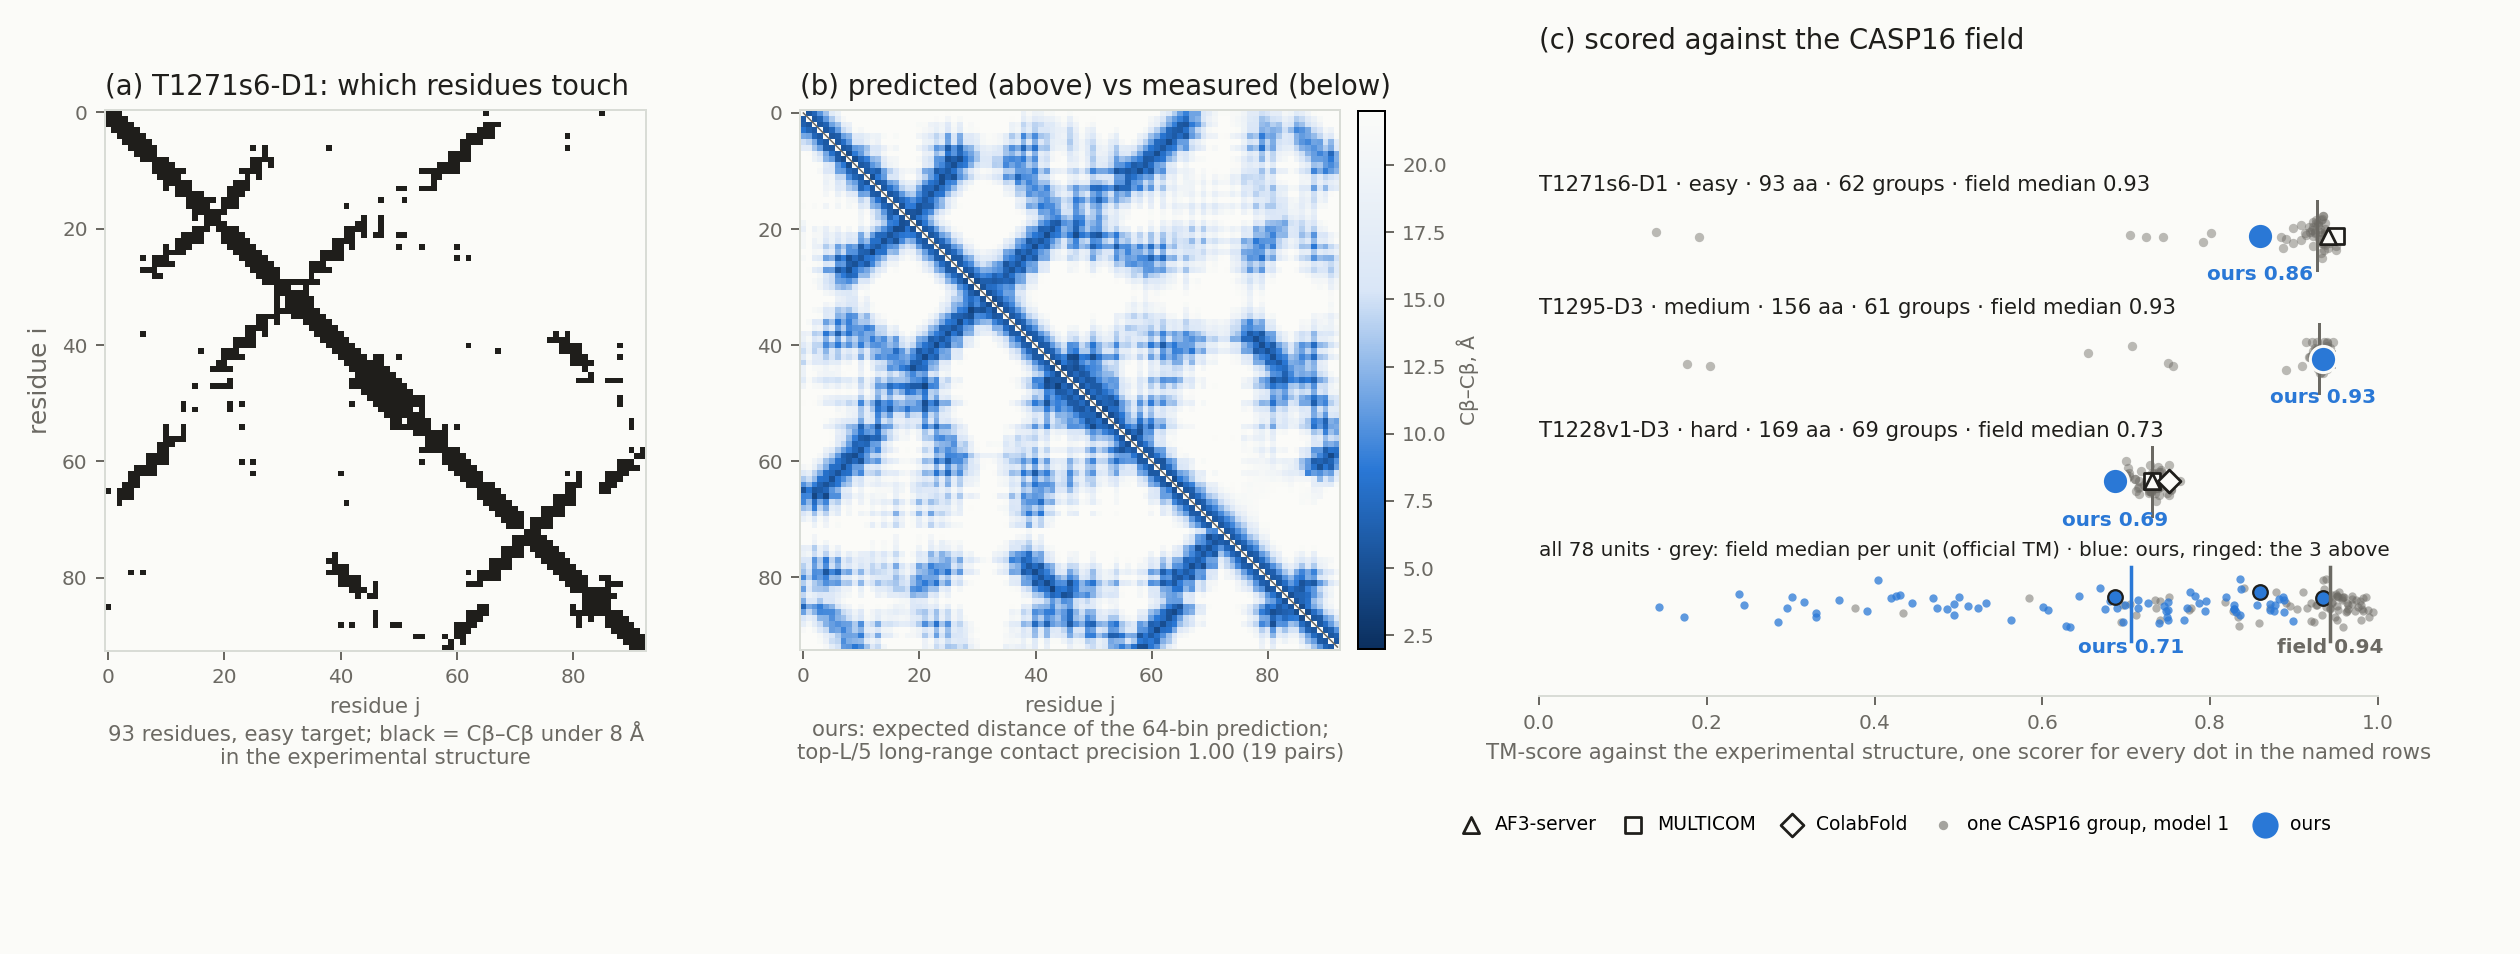
The bracket on the CASP16 targets.
Table 12-9 is the top-\(L/5\) long-range contact precision over the 84 evaluation units (a long-range pair is 24 or more residues apart; the number is the fraction of the \(L/5\) most confident such pairs that are within 8 Å), the recall of the true long-range contacts at \(P {\gt} 0.5\), and the fold’s \(\mathrm{C}_\beta \)-lDDT and TM-score over the 78 units the fold and the field both cover.
|
arm |
precision |
recall |
\(\mathrm{C}_\beta \)-lDDT |
TM |
|
one-hot residues, no language model, 64 ch |
0.252 |
0.001 |
0.319 |
0.228 |
|
ESM-2 3B’s own contact head, nothing trained |
0.759 |
|||
|
ESM-2 650M features, 64 ch, crop 64, 30 epochs |
0.838 |
0.387 |
0.569 |
0.572 |
|
the book run: 3B, its plane, 128 ch, crop 96, heads, 100 epochs |
\(\mathbf{0.873}\) |
\(\mathbf{0.476}\) |
\(\mathbf{0.627}\) |
\(\mathbf{0.646}\) |
|
ESMFold v1: ESM-2 3B under its own trunk |
0.751 |
0.778 |
||
|
CASP16 field, the median first model per unit |
0.892 |
The language model is the lever and the ladder says by how much: at 64 channels and 30 epochs the precision runs \(0.585 \to 0.735 \to 0.838 \to 0.840\) from ESM-2’s 35M to its 150M, 650M and 3B sizes, each model’s own contact head \(0.474 \to 0.623 \to 0.754 \to 0.759\) beneath it, so the network adds 0.08 to 0.11 on every language model and the ladder is flat on precision past 650M, where the 3B step shows in the fold (\(+0.012\)). On top of 650M each of width (128 channels), a 96-residue crop and the model’s contact map as a pair channel is worth \(+0.01\) to \(+0.02\) of precision and the three add, the plane giving the hard class the most (\(+0.09\) on its own); with the 3B features they reach \(0.880 / 0.622 / 0.632\) at 30 epochs, and the orientation heads cost 0.003 of precision and buy \(+0.013\) of TM-score through the \(\omega /\varphi \) restraints. The book run is that configuration at 100 epochs, and the schedule bought nothing: against its 30-epoch twin (\(0.877 / 0.628 / 0.645\)) the paired differences over units are \(-0.004\), \(-0.001\) and \(+0.001\) with every 95 % interval across zero, and validation precision is level from epoch 20. A second seed moves any arm by at most 0.002 on any column, an ensemble of five arms does not beat its best member, and the fold is converged: under its own potential the experimental trace has higher energy than our fold on 78 of 78 units, the map’s own mean distances score an lDDT of 0.615 against the fold’s 0.627, and the two correlate at 0.90, so what the fold realises is the map. Figure 12-7 is what each lever buys.
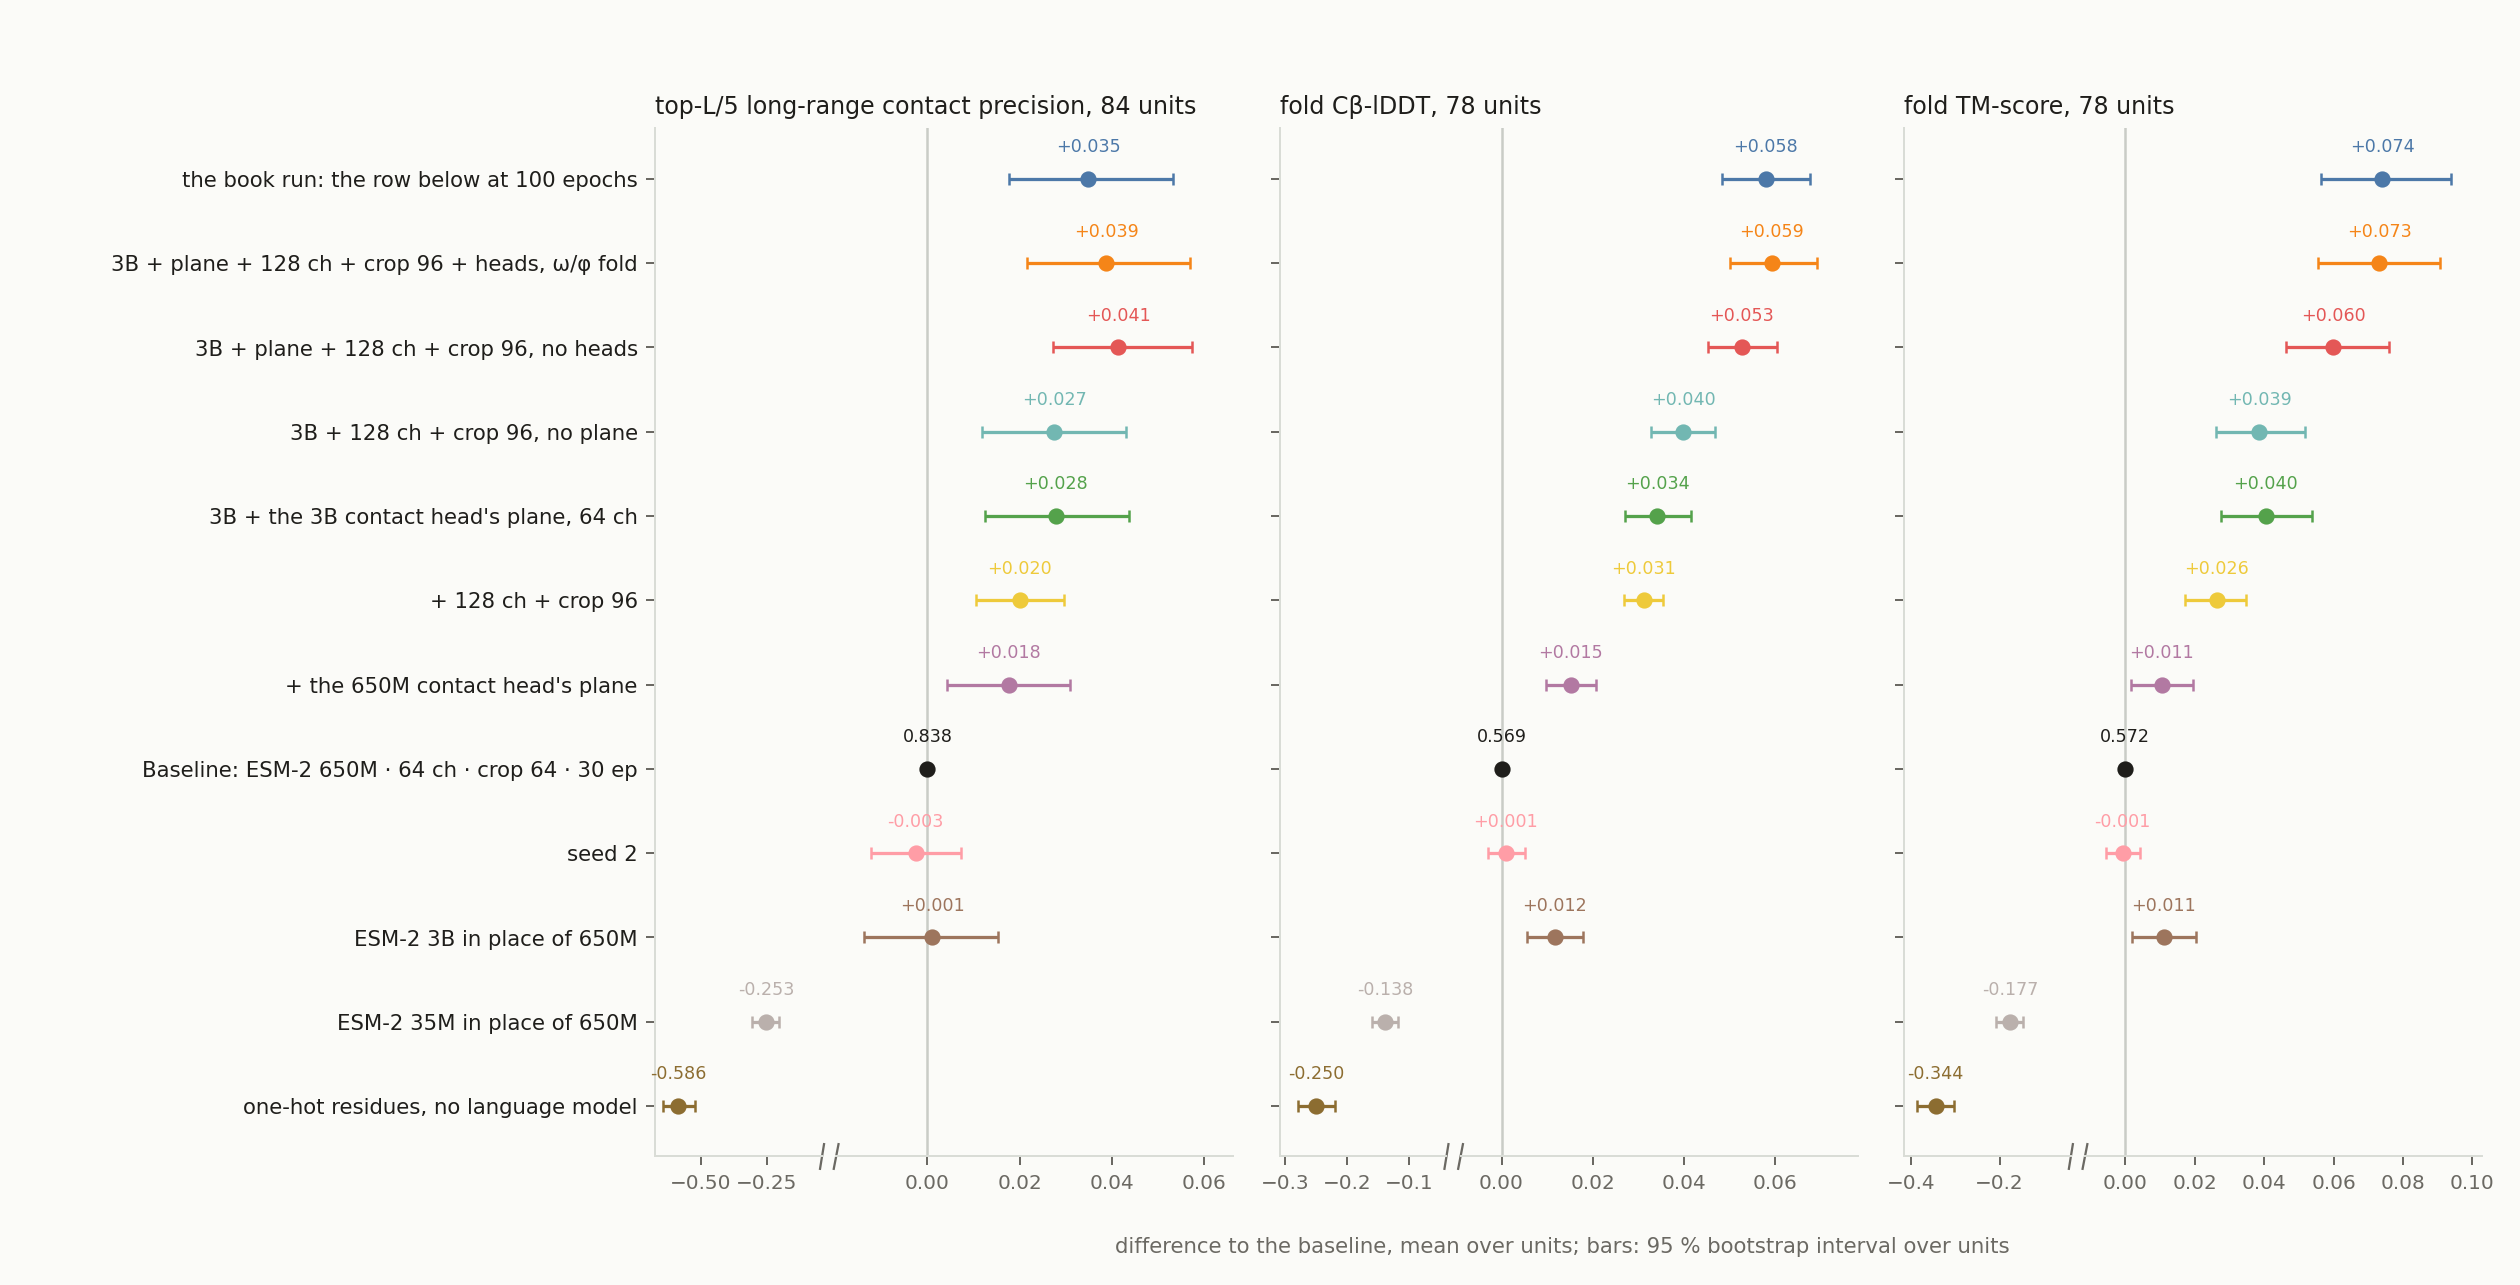
The gap is the story. Our TM-score of 0.646 sits at the field’s third percentile; the median first model is 0.892 over the same 78 units, \(0.945 / 0.883 / 0.656\) on the easy, medium and hard classes against our \(0.716 / 0.617 / 0.495\), and OpenComplex, the lowest of the thirty groups that predicted all 78, is at 0.768. Two readings, from the units themselves. Sixteen units have top-\(L/5\) precision under 0.85 and fold to 0.34 where the field’s median is 0.83 — four of them “easy”, which in CASP’s vocabulary means a template exists in the PDB, something a single-sequence model cannot see — and they are two fifths of the distance; the other 62 fold to 0.72 against 0.91, and there the top \(L/5\) pairs are right, the next \(L\) are half wrong and the recall at \(P {\gt} 0.5\) is 0.49. ESMFold places the two halves: the same language model under the trunk and structure module its authors trained for it folds the 78 to \(0.751 / 0.778\), \(+0.132\) of TM-score over our head with a 95 % interval of \([+0.103, +0.167]\) and better on 71, 0.84 against 0.72 on the 62 units where our top contacts are right and 0.53 against 0.34 on the 16 where they are not. So the head is the larger half of the gap and the input is the other: an alignment is what the field’s models read and ESMFold does not, and half of the sixteen are blind to the language model too.
What this is not: a 5.4M-parameter network on a single sequence, 65 residues of receptive field in a 96-residue window, folded as one point per residue. The field’s models read alignments and templates and build an all-atom chain through a structure module; the architecture that does so is the entry below, and AlphaFold 2’s distogram head is this demo’s network grown into a 48-block pair stack with the alignment beside it.
Four gates sit under the table. The scorer reproduces CASP16’s official lDDT and TM-score to the printed digit on nine field models — AF3-server, MULTICOM and ColabFold on three targets — and GDT_TS within a point. Folding a target’s true distogram recovers its structure (TM-score 0.9999 on T1235-D1) and the mirror scores 0.34. The packed training pools are checked against the per-chain files before any run, and a 64-chain memorization probe must leave the separation prior. And lake exe distogram-casp smoke finite-differences the emitted gradient of the pair tile’s weights, a body weight and each head’s bias against the step’s own first Adam moment, and checks that the evaluation forward’s loss at one batch’s statistics is the training step’s. The trainer is demos/MainDistogramCasp.lean; the chain list, labels, embeddings and packing are scripts/datasets/casp16_*.py, the fold, scoring, table and figures scripts/demos/casp16_*.py.
AlphaFold 2 Evoformer (Bestiary/Evoformer.lean)
Two new primitives (§ 171, § 172). Dual-representation (MSA + pair) doesn’t fit a linear NetSpec cleanly; the bestiary shows the two bundled primitives and notes the limitation (Jumper et al. 2021, Nature). Variants: full (76M), mini, tiny.
def alphaFold2 : NetSpec where
  name   := "AlphaFold 2 (Evoformer + StructureModule)"
  imageH := 384                                   -- max residues (N_res)
  imageW := 1
  layers := [
    -- 48 blocks of dual-representation processing (MSA + pair).
    -- Each block bundles: MSA row-attn (w/ pair bias), MSA col-attn,
    -- MSA transition, outer-product mean → pair, triangle-mul updates
    -- (out + in), triangle self-attention (start + end), pair transition.
    .evoformerBlock 256 128 48,
    -- Structure Module: 8 recurrent IPA rounds (weights shared).
    .structureModule 384 128 8
  ]
The two primitives are conceptually separate networks chained back to back; the linear NetSpec flattens that.
Evoformer (48 blocks) is the perception/refinement stage. It maintains a dual representation: a multiple-sequence-alignment tensor \(\mathrm{MSA}\! \in \! \mathbb {R}^{s \times r \times c_m}\) (where \(s\) is the number of homologs found by the database search and \(r\) is the number of residues) and a pair tensor \(\mathrm{Pair}\! \in \! \mathbb {R}^{r \times r \times c_z}\) encoding predicted residue-residue relationships. Each block updates both via seven stacked operations (row attention with pair bias, column attention, MSA transition, outer-product-mean into pair, two triangle multiplicative updates, two triangle attentions, pair transition). Forty-eight rounds of that turn raw evolutionary signal into a self-consistent geometry-implied pair representation.
Structure Module (8 recurrent rounds, shared weights) is the geometry stage. It consumes the final pair tensor + a per-residue “single” embedding and emits 3D backbone frames plus side-chain \(\chi \) angles. Each round runs Invariant Point Attention (IPA) over the residues, updates each residue’s local frame relative to its neighbors, and feeds back into the next round. The shared-weights recurrence is unusual — most networks unroll different parameters per layer — and reflects that each round is the same fixed-point iteration on the protein’s 3D structure.
The bundled-primitive shortcut means Lean sees one NetSpec with two layers; the actual graph is a much larger DAG with the dual representation and the cross-stage handoff. § 171 and § 172 document the bundling explicitly.